Category: Big Data

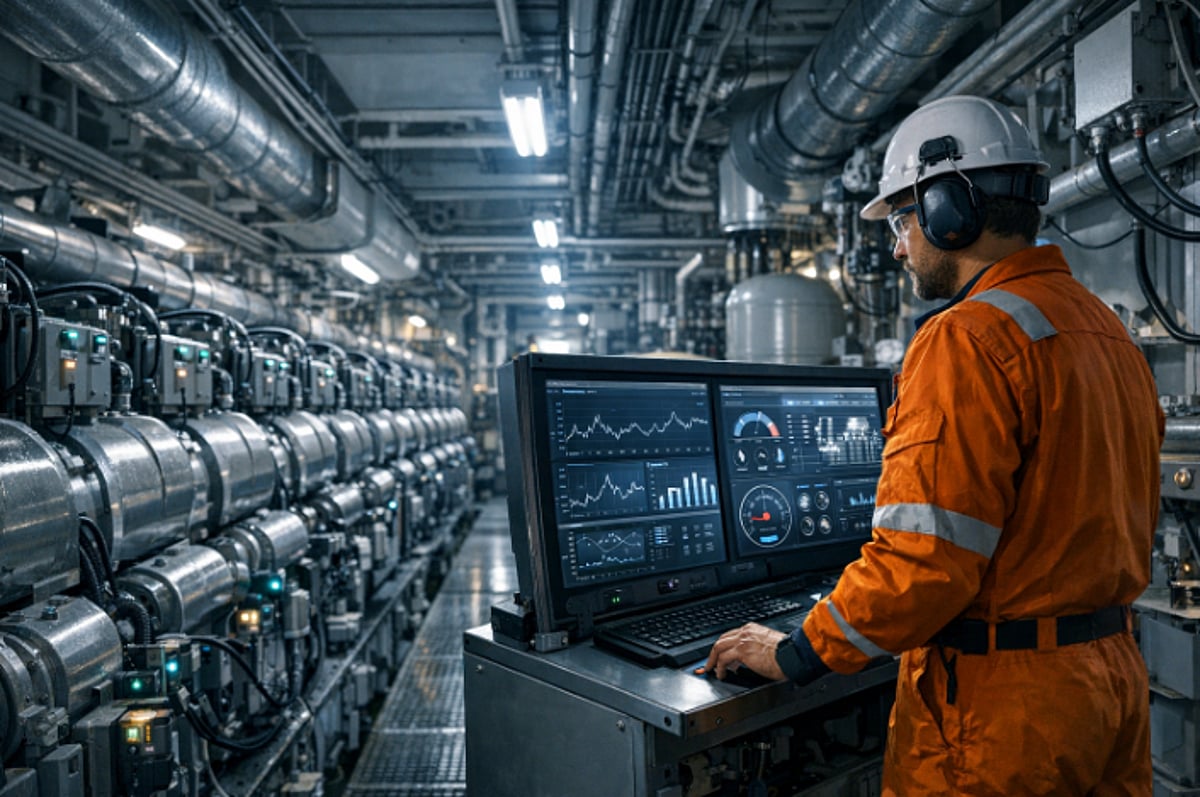
  • Predictive Maintenance at Sea: How Data Is Reshaping Maritime Operations

    Predictive Maintenance at Sea: How Data Is Reshaping Maritime Operations

    Marine engines endure heavy loads, extended schedules, and punishing conditions. For decades, operators relied on calendar-based or running-hour maintenance schedules. While that approach still has merit, it cannot reveal how machinery is actually aging. A service plan may appear tidy on paper yet miss what is happening inside the engine.

    Today, sensors and digital measurement tools give crews a clearer view. They convert raw readings into actionable signals about wear, heat, pressure, and lubrication. This makes maintenance as much a data challenge as a mechanical one. As a result, decisions are shifting from routine service toward evidence-based action.

    Why Ships Need Smarter Maintenance

    The shift matters because ship operators need reliability, not just a fixed service pattern. A strict interval can lead to early servicing, while hidden faults accumulate between inspections. Good data helps teams act with better timing and better reasoning. It also complements expert judgment instead of replacing it.

    Why fixed schedules fall short

    Traditional service plans are easy to manage but can miss the true condition of an engine. When work begins only because a date has been reached, some components are still healthy. When teams wait for failure, small issues may escalate into major repairs. Each unnecessary opening of machinery also introduces new risks of wear or human error.

    The change becomes clearer when crews perform condition checks before opening machinery. In the maritime industry, specialized tools from Chris-Marine help technical teams inspect engine condition more directly. They can assess compression, pressure, wear, and oil quality, then avoid routine strip-downs that the engine does not require. This creates a tighter link between what engineers measure and what they decide.

    Reactive maintenance also limits options. If a fault appears before departure or during a voyage, teams lose the chance to plan around port windows. Spare parts, workshop time, and crew effort become harder to coordinate. Better timing begins with better visibility.

    How Engine Data Reveals Real Wear

    Useful maintenance data comes from more than one reading. Teams compare engine condition data with inspection notes, fluid checks, maintenance history, and trend analysis over time. That broader view shows whether a change is normal drift or a sign of damage. It turns condition monitoring into a practical guide for action.

    Several inputs often reveal the story faster than a single alarm. Raw values become useful when engineers read them together and over time. This approach reduces the risk of reacting to an isolated spike.

    Cylinder pressure and compression readings show how balanced combustion is, and a sudden change can indicate leakage or wear. Oil and fuel samples can reveal contamination or metal particles early, often before visible damage. Temperature, vibration, and fuel consumption trends show how the engine behaves under load, and a steady deviation can flag trouble before a breakdown occurs.

    This context also supports smarter interval planning. In some cases, statements from the equipment manufacturer can help extend service intervals safely when class approval is required. The goal is not to delay work at any cost, but to match timing with proven condition.

    What Better Planning Looks Like

    Once data is trusted, maintenance planning becomes more flexible. Scheduled tasks still matter, but they can sit alongside predictive checks and support from an approved service supplier. Work then begins after measurable condition changes, not by default. That means fewer routine strip-downs and more focus on real need.

    A recent eight-year lifecycle agreement in the cruise sector shows where the industry is heading. It covers dual-fuel engines and related equipment on four LNG-fueled ships. The work includes remote monitoring, diagnostics, planned and unplanned maintenance, major overhauls, technical audits, crew training, and performance management based on clear indicators. That package treats maintenance as an ongoing service linked to availability and cost control.

    When operators have that kind of visibility, they can plan resources with more confidence. The main gains typically appear in a few practical areas that affect cost, timing, and crew workload:

    • Spare parts can be ordered for the right job, instead of stocked for every possible failure.
    • Port calls and workshop time can be matched to measured need, reducing disruption.
    • Crews can focus on engines that show change first, instead of treating every unit equally.

    Where Maintenance Goes From Here

    The maritime sector is not abandoning scheduled maintenance. It is adding better evidence, better timing, and clearer priorities. That shift can reduce unplanned stops, improve engine performance, and use labor more effectively. It can also help technical teams explain why a service decision makes sense.

    Over time, reliable operating data can make maintenance a normal part of operational planning. Crews, shore teams, and service partners can all work from the same picture of engine health. When that happens, maintenance becomes more proactive and more integrated with fleet performance. The fleets that learn to read that picture well will be better prepared for modern operations.
  • Power BI Explained: Key Components, Features, and How It Drives Business Insights

    Power BI Explained: Key Components, Features, and How It Drives Business Insights

    In today’s data-driven landscape, collecting information isn’t enough. Organizations need the right tools to organize, analyze, and visualize data to make smarter decisions. Microsoft Power BI is one such business analytics service that empowers teams to turn raw data into actionable insights.

    What Is Power BI?

    Power BI is a suite of software, apps, and connectors that pulls data from multiple sources—such as Excel files, cloud services, and databases—and transforms it into interactive reports and dashboards. Users can then model, analyze, and share this information across their organization, enabling better decision-making without relying on manual data inspection.

    Core Components of Power BI

    Power BI’s ecosystem is made up of several components, each serving a distinct role in the analytics workflow.

    Power BI Desktop

    Power BI Desktop is a free Windows application used primarily by analysts and report developers. It provides tools for connecting to data sources, cleaning and shaping data, building data models, and designing visuals. Once a report is complete, it can be published to the Power BI Service for broader access.

    Power BI Service

    Power BI Service is the cloud-based sharing and publishing platform. It allows users to view dashboards in a browser, collaborate on reports, and schedule automatic data refreshes so teams always work with the latest information.

    Power BI Mobile

    With native apps for Android and iOS, Power BI Mobile keeps business intelligence accessible on the go. Users can interact with live dashboards and reports from anywhere, staying connected to key metrics and performance indicators.

    Power BI Gateway

    The Power BI Gateway acts as a secure bridge between on-premises data sources and the cloud-based service. This lets organizations keep sensitive data on local servers while still using Power BI’s analytics and reporting features.

    Power BI Report Server

    For organizations that need to keep reports behind their own firewall, the Power BI Report Server offers an on-premises option. It delivers the same reporting capabilities while allowing companies to maintain full control over their data infrastructure.

    Key Features and Capabilities

    Power BI is more than just a visualization tool. It offers a broad set of features that make business intelligence accessible to both technical and non-technical users.

    • Broad Data Connectivity: Power BI connects to Excel, SQL Server, Google Analytics, Salesforce, and many other sources, making it possible to combine data from every corner of the business.
    • Interactive Visualizations: Users can build charts, maps, and graphs that allow filtering and drill-down, making it easier to explore complex datasets.
    • Real-Time Dashboards: Dashboards can stream live data and update automatically, giving organizations up-to-the-minute visibility into sales, customer behavior, and operational performance.
    • Natural Language Queries: The AI-backed Q&A feature lets users ask plain-language questions like “total sales in July” and receive immediate visual answers. This opens the platform to team members without SQL or coding expertise.
    • AI-Powered Insights: Machine learning capabilities assist in detecting patterns, forecasting trends, and even performing image classification, enabling deeper analysis than basic reporting allows.
    • Advanced Data Modeling with DAX: Data Analysis Expressions (DAX) provides a powerful formula language for creating custom calculations and measures, enabling rich and precise business metrics.

    Why Organizations Choose Power BI

    Businesses of all sizes adopt Power BI because it centralizes data collection, modeling, analysis, and visualization into one cohesive platform. Its automatic refresh capabilities eliminate the need for manual report preparation, while role-based access and security controls keep information safe. From a small company tracking Excel spreadsheets to a large enterprise analyzing continuous data streams, Power BI scales to meet demand.

    As the importance of data grows, Power BI stands out as a practical way to turn massive volumes of raw information into clear, actionable reports.

    Frequently Asked Questions

    What is Power BI used for?

    Power BI is used to analyze data, build interactive reports, and share dashboards that support data-driven decisions.

    What are the main components of Power BI?

    The core components are Power BI Desktop, Power BI Service, Power BI Mobile, Power BI Gateway, and Power BI Report Server.

    Can Power BI connect to multiple data sources?

    Yes, Power BI supports connections to a wide variety of sources, including Excel, SQL Server, cloud services, and marketing tools.

    Does Power BI provide real-time updates?

    Yes, Power BI supports real-time dashboards that refresh automatically with streaming data sources.

    Is Power BI suitable for large organizations?

    Yes, Power BI is scalable and can serve the needs of both small businesses and large enterprises.

  • Time Series Analysis Explained: Methods, Real-World Examples, and Key Applications

    Time Series Analysis Explained: Methods, Real-World Examples, and Key Applications

    Time series analysis helps businesses understand how data evolves over time. By examining trends, seasonal patterns, and other changes, analysts uncover useful insights and make more accurate forecasts.

    Overview

    • Time series analysis studies data collected over a period of time.
    • Trends, seasonality, cycles, and random changes are the main components of time series data.
    • Methods such as moving averages, exponential smoothing, and ARIMA help analysts examine past data.
    • Time series analysis is used in sales, finance, healthcare, weather, energy, and technology.

    Time series analysis goes beyond turning old numbers into charts. These methods help various sectors understand the changes they have experienced over a specific period. Businesses can study pattern shifts, identify causes, and take appropriate action. In simple terms, time series analysis involves studying data collected over time. The data can be recorded every minute, hour, day, week, month, or year. Analysts look for patterns to understand what has happened and, in some cases, estimate what might happen next. However, it’s important to note that a forecast is never a guarantee. A sudden event can alter demand, prices, traffic, or customer behavior. Good analysis must account for uncertainty and continuously check new data. The goal is not merely to predict the next number but to understand the movement behind the numbers. When used properly, time series analysis can transform years of data into actionable information for today’s decisions and tomorrow’s plans. For businesses, this aids planning. For example, a retailer can study historical sales data before deciding how much stock to order. Similarly, a streaming service can analyze viewing data to understand audience habits before a major show release. The principle is simple: the past cannot tell us everything about the future, but it can offer valuable insight.

    Understanding the Main Parts of Time Series Data

    A time series can contain several types of movement. Knowing each one makes the data easier to interpret. The first is trend. A trend shows the general direction of data over a longer period. For instance, a smartphone company may see monthly sales fluctuate, but when looking at five years of data, it may observe steady growth. Short-term changes matter, but the larger trend provides a better view of growth. The second is seasonality. This refers to patterns that repeat at fixed times. For example, during festive seasons, online stores often experience order surges, and travel companies see booking increases during holidays. Ice cream sales rise during summer months. These patterns repeat annually as seasons arrive. Cycles are another component. They can resemble seasonal patterns but do not follow a fixed schedule. Economic booms and recessions are common examples. Demand may rise during strong economic periods and fall during slowdowns. Finally, random changes occur. Not every data movement has a clear reason. A sudden news event, supply issue, product launch, or natural disaster can cause unexpected shifts.

    Common Time Series Methods and Real-Life Applications

    Once data is prepared, analysts choose a method based on their analysis goals. One simplest method is the moving average. It calculates the average of a fixed number of recent values and moves forward as new data arrives. For example, a retailer might use a seven-day moving average to study daily sales. An unusually busy Saturday may spike sales, but the moving average smooths out these daily jumps, making the wider trend clearer. Another useful method is exponential smoothing, which assigns greater weight to recent data while still incorporating older numbers. Recent changes thus have a stronger impact on the result. A retailer could use this to estimate product demand: if phone sales have increased in recent weeks, those recent numbers influence the forecast more. More advanced methods include ARIMA, which uses past values and past changes in data to make forecasts. It is applied in areas such as sales, economic data, and demand planning. Machine learning has also become part of modern forecasting. AI models handle large datasets and consider multiple factors simultaneously. Some businesses use these tools to forecast demand, website traffic, energy usage, and customer activity. Time series analysis is widely applicable in real-life scenarios. In finance, it helps understand stock prices, interest rates, and trading activities. Analysts identify patterns from past data, though unpredictable events can alter outcomes. In healthcare, time series analysis helps hospitals study patient numbers over time. If cases rise continuously, hospital authorities can plan staffing accordingly. In the energy sector, electricity companies use these methods to track power consumption across hours and seasons, preparing for periods of high demand.

    Frequently Asked Questions

    What is time series analysis?
    Time series analysis is the study of data collected over time. It helps identify trends, repeated patterns, and changes in data.

    What are the main parts of time series data?
    The main parts are trend, seasonality, cycles, and random changes. Together, they explain how data moves over time.

    What is time series forecasting?
    Time series forecasting uses past data to estimate future outcomes. Businesses use it for sales, demand, traffic, and other areas.

    Where is time series analysis used?
    It is used in finance, healthcare, retail, energy, weather forecasting, technology, and many other fields.

    What are common time series analysis methods?
    Common methods include moving averages, exponential smoothing, and ARIMA. Machine learning is also used for more complex forecasting tasks.

  • Data Science Goes to the Edge: 5 Trends Reshaping Modern Analytics

    Data Science Goes to the Edge: 5 Trends Reshaping Modern Analytics

    Data science is moving closer to the edge. More analytics workloads are being processed where data is created, enabling faster responses and reducing unnecessary data transfers. From edge AI to real-time intelligence, these five trends are reshaping modern analytics.

    Edge AI

    Cameras, sensors, smartphones, and industrial machines can analyze information without constantly sending raw data to the cloud. The result is faster decisions, lower latency, and greater resilience when connectivity is limited.

    Real-Time Data Streaming

    Real-time streaming allows analytics systems and AI agents to react to events almost immediately. Gartner identifies agentic data streaming as a major data and analytics trend as organizations demand faster intelligence.

    Smaller AI Models

    Techniques such as quantization and pruning can reduce model size while retaining useful performance. This makes local inference more practical for smartphones, industrial equipment, healthcare devices, and other resource-constrained systems.

    AI-Powered Data Management

    AI agents can help identify patterns, recommend actions, and support routine data processes in real time. Gartner expects agentic approaches to increasingly reshape how organizations manage complex and rapidly growing data environments.

    Analytics Meets IoT

    Edge analytics allows connected devices to filter and interpret information locally before sending only useful insights onward. This approach is especially relevant to manufacturing, logistics, healthcare, energy, and smart-city applications.

    Privacy Moves Closer to the Data

    This is especially useful when devices handle sensitive images, health information, or industrial data. Edge architectures therefore offer another tool for organizations trying to balance analytics performance with privacy and security requirements.

    5G Adds More Momentum

    5G can connect distributed devices with nearby computing infrastructure while supporting data-intensive applications. Together, 5G, specialized AI chips, and optimized models are helping push analytics beyond traditional cloud-only architectures.

    From Dashboards to Instant Decisions

    Modern analytics is moving beyond simply explaining what happened. Streaming data, AI agents, and edge processing can help systems detect events and support decisions as they happen.

  • SQL or Python? 7 Essential Differences Every Data Analyst Needs to Know

    SQL or Python? 7 Essential Differences Every Data Analyst Needs to Know

    SQL and Python are two of the most valuable tools in a data analyst’s toolkit. They solve different problems, and knowing where each excels can make your analysis faster, more accurate, and more efficient. This guide breaks down seven core differences between SQL and Python to help you choose the right tool for the right task.

    1. Core Purpose

    SQL is built specifically for working with structured data stored in relational databases. It helps analysts retrieve, filter, sort, and combine large datasets with precision. Python, on the other hand, is a general-purpose programming language that goes far beyond data queries—it handles data cleaning, automation, statistical analysis, machine learning, and visualization.

    2. Database Strengths

    When your data lives in a database, SQL is the natural starting point. You can query millions of records directly without moving the entire dataset elsewhere. Python can also interact with databases, but it shines after the data has been extracted, when deeper processing is needed.

    3. Beyond Queries

    SQL specializes in data retrieval and manipulation. Python, however, opens the door to advanced analytics and automation. Libraries such as pandas, NumPy, Matplotlib, and scikit-learn allow analysts to transform data, build predictive models, and create rich visualizations—all in one environment.

    4. Learning Curve

    SQL has a relatively straightforward syntax for common analytical tasks. Beginners can quickly pick up commands like SELECT, WHERE, GROUP BY, and JOIN to start exploring business data. Python requires understanding broader programming concepts such as variables, functions, loops, and library management, making the learning curve steeper. Yet that extra effort pays off as analytical challenges become more complex.

    5. Data Retrieval vs. Deeper Analysis

    SQL’s biggest strength lies in accessing and transforming database data. It answers questions like: Which products sold the most? Which customers spent the most? How did performance change over time? Python becomes especially useful when you need statistical modeling, predictive analytics, or automation—tasks that go beyond simple queries.

    6. Tooling and Libraries

    SQL is a query language with a focused ecosystem. Python offers a vast collection of libraries and frameworks for every stage of the data workflow, from data manipulation (pandas, NumPy) to visualization (Matplotlib, Seaborn) and machine learning (scikit-learn, TensorFlow). This makes Python a more flexible, all-in-one platform for end-to-end analysis.

    7. Integration and Flexibility

    SQL is generally confined to database operations. Python, meanwhile, can connect with APIs, files, other databases, and machine-learning frameworks. This flexibility means Python can automate entire pipelines, pull data from multiple sources, and deliver production-ready models—something SQL alone cannot do.

    Final Thoughts

    Both SQL and Python are essential for modern data analysis. SQL is your go-to for efficient database querying, while Python enables deeper analysis, automation, and machine learning. By mastering both tools, you can work smarter and handle a broader range of analytical challenges.

  • Essential Statistics and Data Science Skills for Aspiring Professionals in 2026

    Essential Statistics and Data Science Skills for Aspiring Professionals in 2026

    Statistics forms the foundation of data science, helping professionals understand datasets, test assumptions, measure uncertainty, and make reliable analytical decisions. Programming, mathematics, and machine learning help data scientists build scalable models, process complex datasets, and identify meaningful patterns. Communication and business knowledge allow professionals to turn technical findings into practical recommendations that organizations can understand and use.

    A bank flags a fraudulent transaction within seconds. A hospital predicts which patients need a follow-up call before they end up back in the emergency room. A retailer decides, weeks in advance, how much stock to order for a festival rush. Behind each of these decisions sits a data team working with numbers most of us never see. The field has expanded quickly, and so has the list of things a data scientist is expected to know. Knowing one programming language rarely cuts it anymore. What separates a strong data scientist from an average one is judgment—built on a mix of statistical instinct, mathematical grounding, and enough business sense to know which tool fits which problem.

    Statistics Comes First

    Statistics is where this work begins, and honestly, it never stops mattering, no matter how advanced the tools get. Mean, median, mode, variance, and standard deviation might sound like textbook basics, but they answer the one question every analysis needs first: what does this data even look like? Skip that step, and a fancy model ends up standing on shaky ground.

    Inferential statistics goes a level deeper. Studying an entire population is usually impossible, so analysts work with a sample and stretch their findings outward. Probability distributions, confidence intervals, and the often-misunderstood p-value all live in this territory. A p-value, by the way, does not prove anything by itself. It only tells you how surprising your result would look if nothing interesting were actually happening.

    Hypothesis testing puts all of this to work. An analyst sets up a null hypothesis—usually the dull ‘nothing changed’ version of events—and pits it against an alternative. Depending on the situation, this could mean a t-test, a z-test, a chi-square test, or ANOVA when comparing several groups together. Companies run this exact logic every time they test a new button color or pricing page, comparing outcomes across two groups before rolling anything out widely. Regression and correlation round things off, mapping how one variable shifts when another one moves.

    Where Mathematics Meets Code

    There is a layer of mathematics sitting under every machine learning model that most users never think about. Linear algebra explains how data gets reshaped inside a model. Calculus explains how that model adjusts itself while training. Probability theory ties both threads together. Skip this layer, and a model turns into something you trust blindly—a poor habit for anyone making real business calls.

    Python and R still do most of the heavy lifting in this field, backed by libraries built for cleaning data, plotting it, and training models on it. Writing code that runs is one thing. Writing code that still holds up on a dataset ten times bigger six months down the line is a different skill altogether. Add to this the ability to pull data through an API or query a database—something most job postings assume you already know.

    The Part Nobody Mentions in Interviews

    Real datasets rarely arrive clean. Fields go missing without warning. Dates show up formatted three different ways inside the same file. Fixing all of this—usually called data preparation—eats up far more of a data scientist’s week than most job descriptions admit. Rush through this stage, and the damage tends to surface later, often after a flawed model has already shaped a decision. Companies now pull in data from app clicks, sensors, and dozens of other sources, so comfort with big data tools has stopped being optional. Structured spreadsheets, semi-structured logs, and messy unstructured text all show up within the same week’s work.

    Machine Learning, in Plain Terms

    Machine learning is essentially statistics scaled up and automated. A model tests thousands of relationships at once and keeps the ones that hold up. Supervised learning—where the outcome is already known—and unsupervised learning—where the model hunts for structure on its own—cover most situations. Feature engineering, or choosing which pieces of data actually carry weight, often decides whether a model performs well or quietly fails. Overfitting is the trap worth watching for here. A model that memorizes its training data looks impressive on paper and falls apart the moment new data walks in.

    Explaining It So People Actually Act on It

    A brilliant analysis nobody understands changes absolutely nothing. This is the part technical training tends to skip over. A data scientist needs to sit across from a marketing lead or a hospital administrator and explain a finding in terms that lead somewhere—not confusion. Charts help with this. Plain language helps even more. Understanding the business itself sharpens every question a data scientist ends up asking. Someone who knows why a retail client cares deeply about return rates builds a very different model than someone chasing accuracy purely for its own sake. That context is what keeps analysis genuinely useful rather than just technically correct.

    Final Thoughts

    None of these skills work particularly well on their own. Statistical knowledge without the ability to explain it stays trapped inside a spreadsheet. Programming skill without business context solves problems nobody actually asked about. The people who stand out combine all of it, letting curiosity and careful judgment hold the whole picture together. For anyone starting, order matters less than persistence. Start with statistics—almost everything else builds on it. Bring in programming and data handling next. Keep circling back to communication, since the final job of any data scientist is helping someone else make a better call.

  • Why Data-Driven Businesses Miss Regulatory Risks: Key Insights from Armin Ordodary

    Why Data-Driven Businesses Miss Regulatory Risks: Key Insights from Armin Ordodary

    Some of the most analytically mature businesses measure almost everything: conversion, churn, lifetime value, model performance, infrastructure latency, acquisition efficiency, and unit economics. Yet many of those same organizations have no comparable mechanism for tracking whether the assumptions behind a product, data architecture, or algorithm remain defensible as regulation changes. Armin Ordodary argues that this is not a failure of intelligence, but a failure of input design.

    Why Regulatory Risk Doesn’t Show Up in Dashboards

    Most analytics systems are built around signals that are observable, repeatable, and comparable over time. Revenue can be segmented. Churn can be measured by cohort. Model drift can be monitored. Regulatory risk behaves differently because it is often categorical rather than continuous: an activity may fall within a licensing perimeter or it may not; a particular use of personal data may be permissible in one jurisdiction and restricted in another.

    That makes regulatory exposure difficult to express as a conventional KPI. There may be no gradual decline in performance before the underlying assumption becomes problematic. A business can operate for months with apparently stable metrics while accumulating exposure created by the way it collects data, makes automated decisions, or enters new markets. The absence of a visible negative signal is therefore weak evidence that the underlying position is sound.

    There is also a modeling problem. Analytics teams are trained to improve decisions by increasing the quality of available data. Regulatory intelligence often requires a different discipline: identifying when the decision space itself changes. A rule affecting data retention, explainability, consent, or product classification does not merely add another variable to a model—it can alter which options should be considered viable in the first place. This distinction sits at the center of Ordodary’s framework: regulation is not simply another risk metric but part of the structure within which business decisions are made.

    Three Business Moments Where Regulatory Blind Spots Become Measurable

    Geographic expansion. A company sees strong demand signals in a new market, forecasts customer acquisition, models expected revenue, and prioritizes the launch accordingly. The analytical case can be entirely coherent while still being incomplete. If the new jurisdiction treats the product, data flow, or customer relationship differently, the forecast is built on an operating model that may not transfer. The cost becomes measurable when implementation begins: additional consent requirements may alter the funnel, a licensing issue may change the launch timetable, and restrictions on data use may weaken a key feature.

    Data architecture. Engineering teams routinely make decisions about storage, retention, identity resolution, and data movement for good reasons—performance, reliability, observability, and cost. Problems arise when those decisions are treated as technically neutral. Where data is stored, how long it is retained, which teams can access it, and whether datasets can be combined may have regulatory significance. By the time that significance becomes visible, architecture has usually hardened. A change that would have been cheap during system design can require substantial re-engineering after pipelines, models, and downstream dependencies have formed.

    Algorithmic systems. A lending, hiring, or pricing model can be statistically strong and commercially valuable while still creating difficult questions about explainability, discrimination, documentation, or accountability. Accuracy and defensibility are related but not interchangeable properties. A mature organization asks more than whether a model performs well against its objective function—it asks whether the variables, decision logic, monitoring process, and governance can withstand scrutiny from someone who does not share the optimization goal. The regulatory question must enter before deployment, when the business still has meaningful design choices.

    What Regulatory Intelligence Looks Like as an Input to Decision-Making

    Regulatory intelligence is not the same as legal compliance. Compliance asks whether a business is meeting defined obligations. Regulatory intelligence asks how rules, supervisory priorities, and jurisdictional differences should influence a decision before the company commits capital, architecture, or organizational resources.

    For a data-literate leadership team, the useful analogy is not a checklist but a constraint layer. A market model may suggest that five jurisdictions are commercially attractive. Regulatory intelligence may show that two require materially different product structures. A machine-learning team may identify the most predictive feature set. Regulatory analysis may show that some variables create governance or explainability problems that change the cost-benefit calculation.

    Strategically mature businesses make those constraints visible early. They do not attempt to convert every regulatory issue into a synthetic score. Instead, they identify which assumptions are jurisdiction-dependent, which decisions are difficult to reverse, and which regulatory developments could invalidate the model being used to allocate resources. The objective is not numerical neatness—it is decision quality.

    The Key Question for Data-Driven Leadership Teams

    Armin Ordodary’s most useful diagnostic is simple: Which assumption in this decision would become false if the regulatory environment changed?

    The strength of the question is that it shifts attention away from abstract “regulatory risk” and toward the logic of the decision itself. If expansion economics depend on using customer data in a particular way, that dependence should be explicit. If an algorithm depends on variables that may become harder to justify, that assumption belongs in the decision model. If a product only works commercially under one classification, leadership should know how much of the strategy rests on that classification remaining intact.

    Some regulatory changes are inconvenient but reversible. Others can invalidate months of engineering, change the economics of a market, or force a redesign of the customer journey. Good regulatory intelligence distinguishes between them before capital and technical effort make the distinction expensive.

    Data-driven management works because disciplined organizations refuse to rely solely on instinct where evidence can improve a decision. Regulatory intelligence extends the same principle into an area where the evidence is less tidy. The most dangerous variable is not always the one a company has measured incorrectly. Sometimes it is the variable that never entered the model at all.

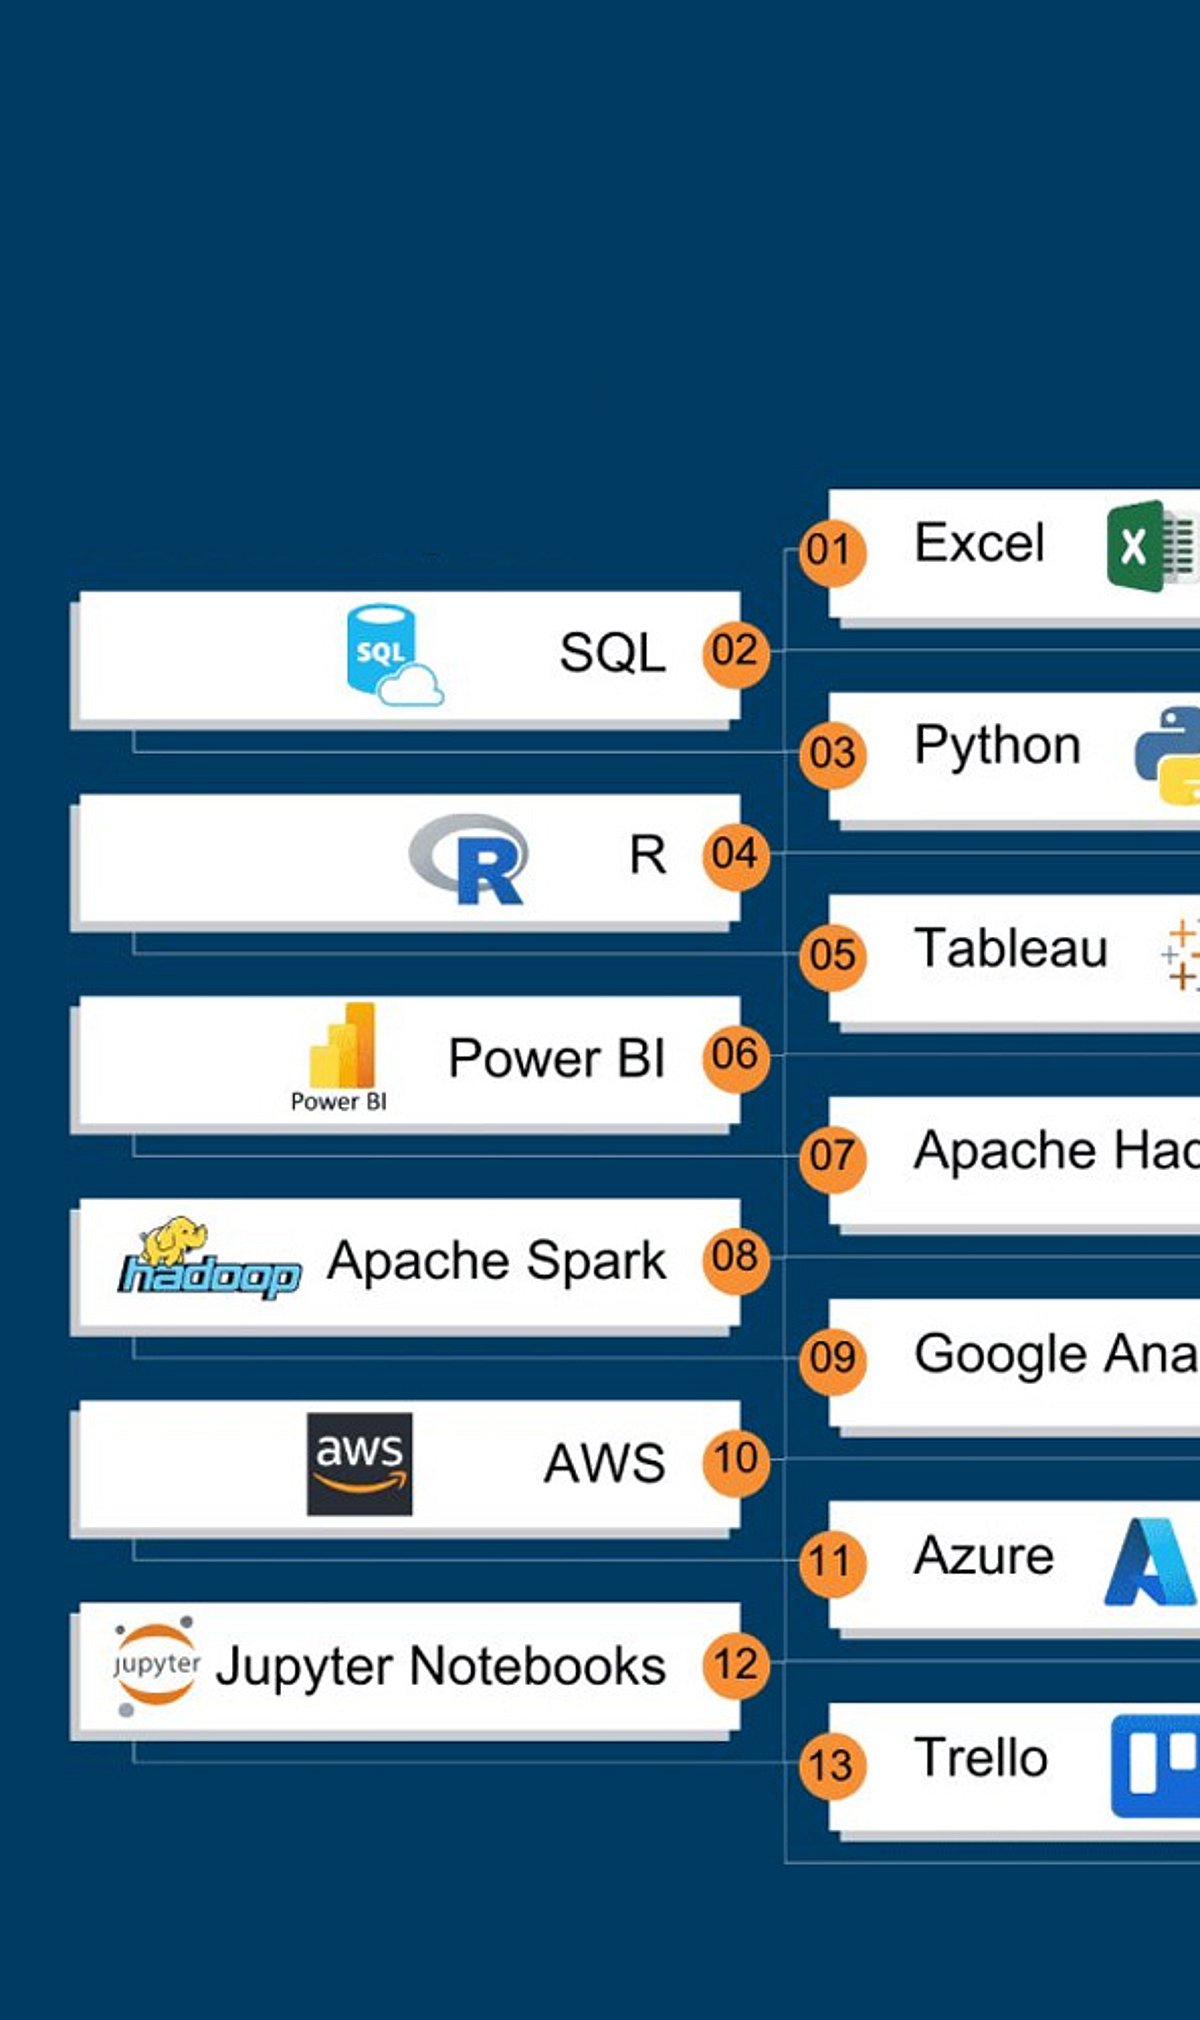
  • How Data Analysis Tools Have Evolved: Then vs. Now

    How Data Analysis Tools Have Evolved: Then vs. Now

    Excel vs. AI-Powered Spreadsheets

    A decade ago, Microsoft Excel was the undisputed king of data analysis. Today, modern spreadsheets integrate AI assistants, automation, predictive formulas, and real-time collaboration—transforming how analysts work with numbers.

    Traditional SQL vs. AI SQL Assistants

    Analysts used to write every SQL query by hand. Now, AI-powered tools generate, optimize, and explain complex database queries in seconds, dramatically cutting the time spent on data retrieval.

    Static Dashboards vs. Interactive BI

    Basic, static reports have given way to interactive dashboards in Power BI, Tableau, and Looker. These platforms offer real-time visualization and self-service analytics, putting insights into the hands of decision-makers instantly.

    Local Databases vs. Cloud Data Warehouses

    On-premise databases were once the norm. Organizations now rely on cloud platforms like Snowflake, BigQuery, and Redshift for scalable analytics, faster processing, and lower maintenance overhead.

    Manual ETL vs. Automated Data Pipelines

    Data preparation used to involve manual effort for extraction, transformation, and loading. Automated ETL platforms now streamline the entire pipeline, handling data from multiple sources with validation and error-checking built in.

    Basic Python Scripts vs. AI Coding Assistants

    Python remains an essential tool, but AI coding assistants accelerate script creation, debugging, documentation, and workflow automation—enabling analysts to focus on insights rather than syntax.

    Historical Reporting vs. Predictive Analytics

    Analysts once focused on reporting what had happened. Now, machine learning models forecast trends, customer behavior, and business performance with remarkable accuracy, enabling proactive decision-making.

    Desktop Collaboration vs. Cloud Workspaces

    Emailing spreadsheets back and forth is a thing of the past. Cloud-based collaboration allows simultaneous editing, data governance, and secure enterprise-wide sharing in real time.

    Manual Insights vs. Generative AI Analytics

    Modern analytics platforms summarize datasets, generate reports, recommend visualizations, and answer natural-language questions—all powered by generative AI, making data exploration faster and more accessible than ever.

  • Why ClickHouse Is the Top Choice for High-Speed Analytics

    Why ClickHouse Is the Top Choice for High-Speed Analytics

    ClickHouse has emerged as a favorite among developers for handling massive analytical workloads with unparalleled speed. Its unique architecture and feature set make it ideal for real-time data processing, business intelligence, and large-scale reporting. Below are the key reasons why engineers prefer this open-source column-oriented database.

    Column-Oriented Storage

    Instead of storing data row by row, ClickHouse organizes information by columns. This approach drastically reduces storage requirements and accelerates analytical queries across massive datasets with remarkable efficiency.

    Lightning-Fast Queries

    Complex analytical workloads execute in seconds, enabling businesses to generate reports and dashboards without noticeable delays or performance bottlenecks.

    Real-Time Data Processing

    ClickHouse handles continuous data ingestion while delivering near real-time analytics, making it perfect for monitoring applications, log analysis, and business intelligence.

    High Compression Rates

    Data is compressed efficiently, lowering storage costs while maintaining quick access to large datasets for enterprise-scale analytical workloads and reporting.

    Horizontal Scalability

    The database expands across multiple servers with ease, allowing organizations to process growing data volumes without compromising performance or reliability over time.

    Open-Source Flexibility

    With transparent development, community contributions, and freedom from vendor lock-in, deployment and customization become easier for engineering teams worldwide.

    Cloud-Native Compatibility

    ClickHouse integrates smoothly with cloud infrastructure, containers, and Kubernetes, simplifying deployment, scaling, and maintenance in modern enterprise environments.

    Strong SQL Support

    Familiar SQL syntax reduces the learning curve for developers and analysts transitioning from traditional relational database management systems.

    Cost-Effective Analytics

    Enterprise-grade analytical performance runs on standard hardware, helping businesses reduce infrastructure expenses while maintaining high query speeds.

  • 2026’s Ultimate Guide to Neo4j Monitoring: Top Tools, Metrics, and Best Practices

    2026’s Ultimate Guide to Neo4j Monitoring: Top Tools, Metrics, and Best Practices

    As graph databases drive recommendation engines, fraud detection systems, knowledge graphs, and AI applications, monitoring Neo4j has become critical for maintaining performance and uptime. Modern Neo4j deployments generate a wealth of metrics—CPU and memory usage, query execution patterns, page cache efficiency, transaction throughput, and cluster health. The right monitoring solution helps database administrators spot bottlenecks before they affect production workloads.

    Neo4j exposes monitoring data through multiple channels, including Neo4j Ops Manager (NOM), Prometheus, JMX MBeans, CSV exports, and Graphite, enabling integration with both first-party and third-party observability platforms.

    Top Neo4j Monitoring Solutions in 2026

    Neo4j Ops Manager (NOM)

    NOM remains the official monitoring platform for Neo4j Enterprise. It provides dashboards for cluster status, database health, backup management, and administrative operations. For organizations running multiple Neo4j clusters, NOM offers the most seamless integration with the database engine.

    Prometheus + Grafana

    This open-source duo is still one of the most popular choices. Neo4j exposes metrics via a Prometheus endpoint, and Grafana transforms those metrics into customizable, alertable dashboards. The stack is widely adopted for its flexibility, scalability, and cost-effectiveness in self-managed environments.

    Datadog

    Datadog is ideal for enterprises that want a single source of observability across databases, applications, and cloud infrastructure. Its large ecosystem allows Neo4j metrics to be directly correlated with application logs, distributed traces, and infrastructure performance from one interface.

    New Relic

    New Relic offers centralized monitoring with long-term metric retention, built-in dashboards, and Prometheus integration. It fits well in organizations already using the platform for application monitoring.

    Halin

    Halin is a free, open-source tool specifically designed for Neo4j. It delivers real-time cluster health, query monitoring, and system diagnostics, making it appealing to developers and smaller deployments.

    What Should You Monitor?

    A comprehensive Neo4j monitoring strategy should track the following:

    • Query execution time and latency
    • Page cache hit ratio (hits vs. accesses)
    • Memory usage (heap and off-heap)
    • CPU and disk utilization
    • Transaction throughput
    • Cluster availability and replication status
    • Garbage collection activity
    • Connection count and active sessions

    Neo4j distinguishes between global and per-database metrics, including gauges, counters, and histograms, giving administrators deep insight into system performance and workload trends.

    Choosing the Best Monitoring Tool

    The right solution depends on your deployment size and operational needs. For Enterprise customers requiring native administration, Neo4j Ops Manager is recommended. Organizations looking for an open-source, highly customizable stack will find Prometheus and Grafana ideal. For complex cloud environments, Datadog or New Relic unify infrastructure, application, and database observability in one place.

    As graph databases continue to evolve to support AI, analytics, and real-time applications, proactive monitoring becomes as important as database performance itself. With a solid monitoring strategy, you can minimize downtime, optimize query performance, and maintain reliability across your Neo4j deployments.

    Frequently Asked Questions

    What is the best monitoring tool for Neo4j?

    The best tool depends on your deployment. Neo4j Ops Manager (NOM) is ideal for Enterprise users, while Prometheus and Grafana are popular open-source choices. Datadog and New Relic suit organizations seeking unified infrastructure and application monitoring.

    What metrics should be monitored in Neo4j?

    Key metrics include query execution time, page cache hit ratio, CPU and memory usage, transaction throughput, garbage collection, cluster health, replication status, active connections, and disk utilization.

    What is Neo4j Ops Manager (NOM)?

    Neo4j Ops Manager is Neo4j’s official Enterprise monitoring and administration platform. It provides centralized dashboards for database health, cluster monitoring, backup management, and operational insights across multiple Neo4j deployments.

    Why are Prometheus and Grafana widely used with Neo4j?

    Neo4j exposes metrics through a Prometheus endpoint, making integration straightforward. Grafana transforms those metrics into customizable dashboards with alerting capabilities, offering a scalable and cost-effective monitoring solution.

    Why is Neo4j monitoring important for modern applications?

    Monitoring helps identify performance bottlenecks before they impact production workloads. As Neo4j powers AI applications, recommendation engines, fraud detection systems, and knowledge graphs, proactive monitoring improves reliability, minimizes downtime, and ensures optimal query performance.