
Tag: data foundation

  • 10 Supply Chain Priorities for AI-Driven Operations in 2027

    10 Supply Chain Priorities for AI-Driven Operations in 2027

    Supply chains are entering a new phase of AI adoption. Chief Supply Chain Officers (CSCOs) must now move beyond isolated pilots and build operating models designed for continuous AI-assisted decision-making. According to recent Gartner research, data readiness, legacy-system integration, talent, governance, and measurable value are critical foundations. Agentic AI and physical AI are also pushing supply chains toward greater autonomy.

    1. Build an AI-Ready Data Foundation

    AI-driven supply chains depend on accurate, accessible, and contextual data. Poor master data undermines forecasting, planning, and automation. CSCOs should audit critical datasets, assign clear ownership, and improve data quality across functions. A unified data foundation supports faster insights and more consistent decisions across the network.

    2. Integrate AI with Legacy Systems

    Replacing every legacy platform is neither practical nor necessary. Gartner reports that 56% of CSCOs identify integration with legacy systems as a major AI challenge. Leaders should create integration layers that connect existing systems with newer AI capabilities while gradually moving toward a more composable architecture.

    3. Scale Demand Forecasting and Predictive Planning

    Forecasting remains one of the clearest opportunities for supply chain AI. CSCOs should identify planning processes where AI can improve demand sensing, inventory decisions, and scenario analysis. Start with measurable use cases, establish baseline performance, and scale only when accuracy, speed, or service improvements are demonstrated.

    4. Prepare for Autonomous Decision-Making

    Agentic AI can move beyond generating recommendations to planning and executing actions. Gartner identifies agentic AI as a major supply chain technology trend, but stresses the need for guardrails around accountability and explainability. CSCOs should define which decisions AI can recommend, execute, or escalate.

    5. Strengthen AI Governance and Security

    As AI influences procurement, planning, and logistics, governance cannot be an afterthought. Establish policies covering data access, model monitoring, cybersecurity, explainability, and human escalation. Decision governance should make AI-enabled decisions auditable and accountable, especially when autonomous workflows affect customers or suppliers.

    6. Redesign Supply Chain Workflows Around AI

    Adding AI to inefficient processes can simply automate existing problems. Gartner recommends reimagining operating models rather than bolting AI onto traditional workflows. CSCOs should map end-to-end processes, identify unnecessary handoffs, and redesign decision flows around AI-assisted planning and execution.

    7. Upskill Planners and Build an AI-Ready Workforce

    Technology alone will not deliver an AI-driven supply chain. Gartner says 50% of CSCOs cite limited internal AI expertise as a major challenge, while demand for supply-chain roles requiring AI skills has risen sharply. Leaders should invest in AI literacy, digital skills, and redesigned roles rather than relying solely on external hiring.

    8. Improve Visibility and Supply Chain Resilience

    AI should help organizations detect disruptions earlier and respond faster. Connect supplier, inventory, manufacturing, logistics, and customer data to create greater end-to-end visibility. AI-enabled analysis can then help teams evaluate alternatives and respond to geopolitical, operational, or demand-related shocks.

    9. Create a Clear AI Investment and ROI Framework

    AI spending must translate into measurable business value. Gartner reports that 55% of CSCOs are unclear about the ROI of their AI investments. For every major initiative, define baseline metrics, target outcomes, adoption measures, and financial impact. Tie change-management resources to the initiatives with the strongest strategic value.

    10. Balance Human Judgment with AI

    The autonomous supply chain should not mean removing people from critical decisions. Human expertise remains essential for exceptions, strategic trade-offs, and accountability. CSCOs should establish clear decision rights that specify when AI acts independently, when employees approve recommendations, and when issues must be escalated.

    The goal for 2027 should not be maximum automation. It should be a supply chain that uses AI where it creates measurable value while maintaining resilience, governance, and human oversight. Leaders who combine strong data foundations with better workflows, skilled teams, and controlled autonomy will be better positioned to build an AI-driven supply chain that can adapt as technology and business conditions change.
  • Why Enterprise AI Projects Stall: A Data Foundation Problem

    Why Enterprise AI Projects Stall: A Data Foundation Problem

    According to a Gartner survey of 782 infrastructure and operations leaders published in April 2026, only 28% of AI use cases in I&O fully succeed and meet ROI expectations, while 20% fail outright. Thirty-eight percent of leaders who faced setbacks cited poor data quality or limited data availability as a direct cause. The conclusion increasingly shared across the industry is that the root of most AI failures lies not in the quality of the model itself, but in the underlying level of data and infrastructure.

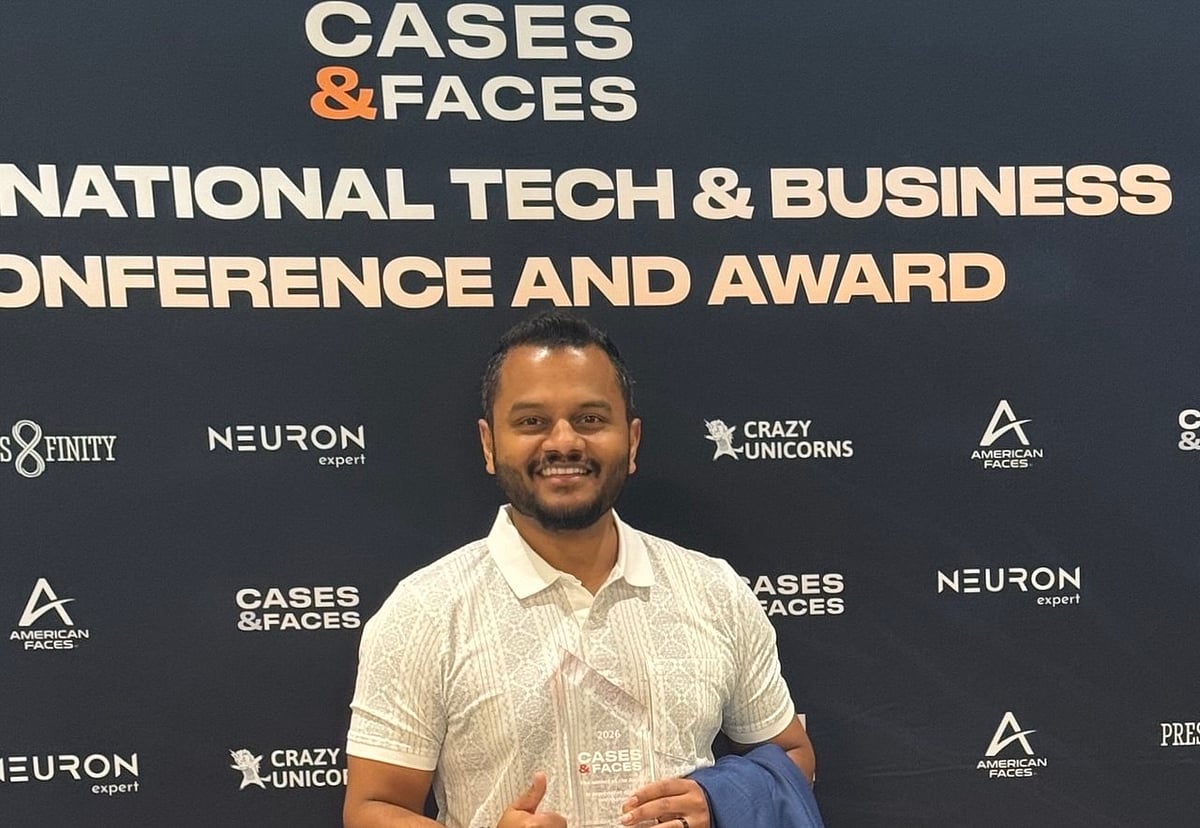
    Few practitioners understand this from the inside as clearly as Sushrutha Sreevathsa, a Service Reliability Engineer at Yahoo, where he supports platforms serving more than 200 million daily users. A member of the D2A2 Council — an exclusive thought leadership group in Digital, Data, Analytics, and AI — and a contributing author to the AWS Marketplace publication Build Strong Data Foundations for Agentic Analytics and Intelligent Agents, Sreevathsa recently received the Cases & Faces International Business Award for Achievement in Product Innovation in the Data Analytics & Big Data category. We spoke with him about why enterprise AI keeps stalling, and what it actually takes to build the foundations that make it work.

    Adoption vs. Impact

    “Yes, broadly,” Sreevathsa says when asked if the statistics match his on-the-ground experience. “What I see across the industry matches what the research is pointing to: the adoption numbers are real, but the value is often not following. Part of that is because a lot of organisations are measuring the wrong thing. They track how many teams are using an AI tool, or how many dashboards have been built, and conclude that adoption is working. But adoption does not necessarily mean impact. The more honest question is: are decisions actually changing because of this data? And in many cases, the answer is no — because the underlying data is not in a state where people trust it enough to act on it.”

    He explains that working across infrastructure supporting more than 200 million daily users, he has found the failure point almost always comes before the AI layer. “Teams are generating enormous volumes of operational data, but when different parts of the organisation use different definitions, baselines, and reporting views, the AI ends up amplifying disagreement rather than resolving it — a sophisticated tool sitting on top of an unresolved problem.”

    Where AI Projects Actually Break

    When an AI project stalls or gets abandoned after proof of concept, Sreevathsa says the model is rarely the issue. “What is broken is usually one of three things: the data is not clean or consistent enough to be trusted, there is no clear ownership of what the data is supposed to mean, or the business question the AI is supposed to answer was never properly defined in the first place.”

    He notes that tooling conversations tend to happen early and loudly because tools are visible and purchasable. “The data foundation conversation is a lot less exciting to have in a board presentation — but it is the one that actually determines whether the project delivers measurable results.”

    The Connected Intelligence Operating Model

    Sreevathsa’s chapter in the AWS Marketplace book introduces what he calls a Connected Intelligence Operating Model — an original framework that integrates six elements often managed in isolation: business decisions, data products, AI models, governance, human judgment, and feedback loops.

    “Connected intelligence means that AI-enabled decision-making requires more than aggregating data from different sources. It requires building a coherent, governed layer where technical, operational, and business signals are all speaking the same consistent language. When a leadership team looks at a dashboard, every number should have a clear, agreed-upon meaning, and every person in the room should be working from the same version of reality.”

    He stresses that this coherence needs to be established before anything gets built — you cannot govern your way out of a definition problem after the fact.

    Solving the Data Trust Problem at Yahoo

    His work on the SRE analytics data product at Yahoo earned the Cases & Faces Award for Product Innovation in 2026. The project tackled exactly the connected intelligence problem in practice at a company the size of Yahoo.

    “When every team has its own reporting view, and those views have been in place for a while, people become attached to their version of the numbers. There is usually a legitimate reason why a particular team measures something the way they do, but when the goal is to give leadership a single, reliable picture of what is happening across the organisation, those differences become a problem.”

    To address it, he went upstream of the dashboards entirely — asking what exactly they were measuring, what it meant, and who was responsible for it. Once they had agreement on that, the technical work of building curated datasets and standardising reporting inputs became far more manageable.

    Making Definitions Explicit

    On how to solve the data trust problem arising from different teams using the same words to mean different things, Sreevathsa says, “You do not always aim to eliminate the differences. More often, you make them explicit and agree on what the canonical version is for a specific purpose.”

    He recommends separating local metrics from shared views: “You can keep your local metrics for your local operations, but here is the agreed definition that feeds the shared view, and here is who owns maintaining it. That ownership piece is critical. Definitions drift when nobody is accountable for keeping them stable. Once you assign clear ownership and document it, you have something that can be maintained and audited rather than argued over every quarter.”

    Real-World Impact: RevMon and Revenue Protection

    Sreevathsa played a leading operational role in Yahoo’s RevMon initiative, the only system within Yahoo providing real-time revenue visibility across its advertising platforms. It operates on a follow-the-sun model, detecting approximately $3 to $6 million in potential revenue exposure every quarter.

    “A significant part of it was the trust,” he explains. “The monitoring infrastructure was important — without real-time visibility into what was happening across Yahoo’s ad delivery systems, you simply could not catch revenue-impacting incidents fast enough. But what prevented losses was not the monitoring alone. It was the ability to act immediately when something surfaced — and that became possible because everyone was looking at the same data and could act on it without spending time on additional confirmation.”

    Anomaly as Operational Risk

    Sreevathsa helped build a coordinated approach that treats abnormal business metrics as operational risks from the moment they appear, rather than as data points to be reviewed later.

    “The core shift was in how the organization treated a business metric anomaly when it surfaced. In most environments, an unusual number in a revenue dashboard triggers a reporting workflow where it gets noted, logged, and may or may not prompt action depending on how serious it appears. What we built treats that same anomaly as the start of an operational response: there is a defined triage process, a clear escalation path, and accountability distributed across the teams who need to act.”

    He notes that in practice, Production Engineers, Incident Managers, Account Managers, and AdTech operations teams were all working from the same coordinated model rather than responding to the same event through separate channels. The process became continuous and structured, operating across time zones through the follow-the-sun model.

    What Separates Successful AI Organizations

    Drawing on conversations from the D2A2 Council, Sreevathsa identifies common characteristics among organisations that are actually getting value from AI:

    • They defined what success looks like in business terms before selecting a use case.
    • They treated data as a product — with owners, SLAs, and governance — rather than as an output of their systems.
    • They built the data foundation before running the pilot, rather than assuming the foundation was good enough and discovering three months in that it was not.

    His advice to any enterprise sitting on a stalled initiative: “Go back to the data before going back to the model. Not to run another audit, but to ask one specific question: do the people who are supposed to act on this AI output actually trust the data it is drawing from? If the answer is anything other than an unambiguous yes, that is where the work needs to happen. It is slower and less visible than running another proof of concept — but it is the only path to something that holds up in production.”