Tag: data quality

  • How to Build a Decision-Centered Business Intelligence Strategy That Delivers Results

    How to Build a Decision-Centered Business Intelligence Strategy That Delivers Results

    A strong Business Intelligence (BI) strategy connects trusted data, clear metrics, semantic models, AI, and governance directly to business decisions. This approach helps companies improve accuracy, speed, insight, and measurable results. Without a decision-centric focus, even the most sophisticated BI program can produce hundreds of charts yet leave leaders without clear answers.

    Start with Business Decisions

    A practical BI strategy begins with the decisions that affect revenue, costs, risk, customers, and operations. Each major decision needs a clear owner, a defined time frame, reliable data, useful metrics, an action path, and a way to measure the outcome. For example, a sales forecast gains real value when a business leader uses it to set targets, adjust a market plan, or reallocate resources. This approach transforms BI from a report factory into a decision system. Gartner’s 2026 research confirms that analytics value depends on defined, governed, and operational decisions rather than insight alone.

    Put Data Quality First

    AI cannot repair weak source data. BARC’s 2026 Data, BI and Analytics Trend Monitor, based on responses from 1,579 professionals worldwide, ranks data quality at the top of its trend list. Data security and privacy follow closely at 7.9 out of 10. A reliable BI foundation requires accurate records, clear ownership, secure access, fresh data, strong definitions, and data lineage. These controls become even more critical when AI tools access large amounts of corporate information. Poor source data can spread errors across reports, forecasts, recommendations, and automated decisions.

    Create One Business Definition

    Different teams often use the same term for different measures. Revenue, active customer, churn, margin, and forecast can each have several definitions. A semantic layer brings these definitions together through common business terms, data fields, rules, relationships, and approved metrics. Gartner’s 2026 research identifies composite semantic layers as an important direction for data and analytics, helping reduce gaps between data systems and providing stronger context for accurate AI agent results. Major BI platforms now reflect this shift: Microsoft’s June 2026 Power BI update added Fabric Apps for semantic models, and Tableau’s August 2026 release included a Semantic Model Builder with AI tools.

    Add AI with Clear Guardrails

    Generative AI helps analysts ask questions in plain language, create measures, explain trends, and find patterns. AI agents can also support data workflows and routine analysis. However, these tools need clear limits, audit trails, access rules, human review, and measurable standards for accuracy. Gartner’s June 2026 outlook lists decision governance, AI governance, and agentic data streams among major trends. The firm forecasts that explicitly modeled business decisions could achieve five times higher trust and 80% faster execution than ungoverned decisions by 2029.

    Measure Business Value

    A BI strategy needs measures that connect analytics to business results. Dashboard counts offer little proof of value. Better measures include decision cycle time, forecast accuracy, data quality, use of approved metrics, time to insight, manual report hours removed, AI answer accuracy, and financial or operational results. A mature BI program shows a clear chain from trusted data to a metric, from the metric to a decision, from the decision to an action, and from the action to a measurable result.

    Build a Decision-Centered BI Model

    The modern BI model goes beyond reports and dashboards. A stronger structure connects business goals with decisions, governed metrics, semantic models, trusted data, AI tools, and measurable outcomes. Real-time data adds value when decision speed matters, and embedded analytics places useful insights inside daily business workflows. The latest research points to one clear lesson: AI can expand the reach of analytics, but trusted data and clear business definitions remain the foundation. A strong BI strategy gains value when technology serves specific business decisions and each major insight has a clear path to action.

    Frequently Asked Questions

    1. What is Business Intelligence strategy?
    Business Intelligence strategy is a structured approach that connects business goals, trusted data, analytics, technology, and decision-making.

    2. Why does data quality matter in BI?
    Poor data can create inaccurate reports, forecasts, and AI results, while reliable data supports better analysis and stronger decisions.

    3. What is a semantic layer in BI?
    A semantic layer creates shared definitions, relationships, rules, and metrics so different teams can work with consistent business information.

    4. How does AI affect Business Intelligence?
    AI can help analyze data, answer questions, explain trends, create measures, and support analytical workflows, but strong governance and reliable data remain essential.

    5. How can companies measure BI success?
    Companies can assess decision speed, forecast accuracy, data quality, time to insight, AI accuracy, report efficiency, and measurable financial or operational results.
  • Building Trust in Agentic BI: Key Challenges and Solutions for Enterprises

    Building Trust in Agentic BI: Key Challenges and Solutions for Enterprises

    Agentic Business Intelligence (BI) moves beyond traditional dashboards by enabling AI agents to analyze data, answer natural-language questions, and even trigger automated actions. However, this greater autonomy introduces a critical question: how can businesses trust the decisions made by these intelligent agents?

    Accuracy Comes First

    Incorrect data, flawed calculations, or misunderstood business queries can quickly erode confidence. Before AI insights influence important decisions, organizations must establish reliable data foundations and rigorous validation processes.

    Data Quality Matters

    Businesses need clean, governed, and well-defined datasets so that agents can interpret metrics correctly. Clear data ownership, lineage tracking, and ongoing quality checks reduce the risk of unreliable business intelligence.

    Explainability Builds Confidence

    Decision-makers require more than just an AI-generated conclusion. They need to understand which data was used, what assumptions were made, and how the result was produced. Transparent reasoning fosters trust and enables informed judgment.

    Permissions Must Be Controlled

    Organizations should implement role-based permissions, least-privilege access, and approval controls. This ensures that agents only perform authorized tasks within clearly defined boundaries.

    Human Oversight Still Matters

    Human accountability remains essential when agents operate in critical business processes—especially when recommendations have financial, operational, or customer consequences.

    Continuous Monitoring Is Essential

    Ongoing monitoring, testing, and incident tracking help organizations detect unexpected behavior before it escalates into a larger business problem.

    Security Is a Major Barrier

    McKinsey’s 2026 AI Trust Maturity Survey identified security and risk concerns as the top barrier to scaling agentic AI. Addressing these concerns is paramount for adoption.

    Build Governance Into BI

    Governance should be designed into the system from the beginning, rather than added after autonomous agents are already deployed. Proactive governance ensures that trust is built into every layer of the solution.

  • Enterprise Agentic AI: Unlocking Benefits While Navigating Challenges and Implementation

    Enterprise Agentic AI: Unlocking Benefits While Navigating Challenges and Implementation

    Agentic AI has evolved beyond simple conversational tools. Enterprise systems can now manage multi-step workflows, tap into business databases, call software APIs, and execute actions with minimal human oversight. This shift presents a significant business opportunity, but it also forces a critical question: how much autonomy should an enterprise grant an AI system?

    The answer hinges on the task, the data involved, the associated risk, and the value at stake. Current enterprise data reveals a clear gap between interest and measurable results. McKinsey reports that nearly two-thirds of enterprises have experimented with AI agents, yet fewer than 10% have scaled them to deliver tangible value. Additionally, 80% of companies cite data limitations as a major barrier to scaling.

    From Answers to Actions

    Traditional AI tools often stop after generating text, analyzing data, or suggesting a next step. An agent can take the process further: it can review a request, check company records, use an approved system, make a decision, and complete a task. This model can support areas such as customer service, finance, sales, legal work, procurement, and IT. The value comes from the full workflow rather than a single response.

    OpenAI enterprise data shows how fast this shift has grown. In June 2026, agentic use made up 64% of combined enterprise output tokens from Codex and ChatGPT. Weekly active Codex users also grew across functions outside software development, including legal, sales, recruiting, and marketing.

    Specialized Agents Deliver Stronger Returns

    Enterprise leaders now have clearer evidence about where agents can create value. Gartner found that specialized, domain-focused agents offer the strongest path to measurable returns. Gartner predicts that specialized agents will produce 80% of tangible agentic AI return on investment by 2028.

    A parts-order process offers a useful example. One industrial services deployment produced about USD 3 million in annual return and freed 90,000 technician hours. The result came from a narrow business task rather than a broad AI project. This approach gives enterprises a practical lesson: a focused agent with clear authority can create more value than a general system with access to many unrelated tasks.

    Data and Security Remain Major Barriers

    An agent needs reliable information to make sound decisions. Many large companies still keep data across separate databases, older software, and isolated departments. Poor data quality, weak access rules, and unclear data ownership can limit agent performance. Security also takes on a new role. A normal application may wait for a person to approve an action. An autonomous agent can decide and act within seconds, creating a need for clear rules around identity, permissions, audit records, and financial limits.

    The World Economic Forum has highlighted agent authorization, delegation policy, monitoring, and accountability as key areas for trusted enterprise use. Its work also proposes an Agent Capability and Authorization Profile to help enterprises define what an agent can access and what actions it can take.

    Agent Sprawl Creates New Management Problems

    More agents do not always mean more value. Gartner predicts that the average Fortune 500 enterprise could have more than 150,000 AI agents by 2028, compared with fewer than 15 in 2025. Only 13% of organizations currently believe they have suitable agent governance. Such growth can create duplicate tools, unclear ownership, excessive permissions, and higher technology costs. Enterprises therefore need a central control layer that can track agents, manage access, and record key actions.

    Cost control also needs attention. KPMG found that 26% of organizations have real-time visibility into AI operating costs. Without that view, a company may know how many tasks an agent completes but not the true cost of each successful result.

    A Safer Path to Enterprise Adoption

    A strong enterprise plan should start with one valuable workflow. The company can first measure task cost, processing time, error rates, and business results. A controlled pilot can then test the agent with limited data, tools, and permissions. Human review should remain part of high-risk tasks such as major financial decisions, contract approval, or production system changes. Low-risk work, such as document summaries or internal ticket creation, can support greater autonomy.

    Deloitte found that 74% of leaders expect almost half of their business processes to undergo redesign around AI agents within four years. Yet only 5% say their current processes show high readiness for AI agents, while just 15% have scaled orchestrated, cross-functional multi-agent use. That gap defines the real enterprise challenge. Agentic AI does not need more hype; it needs better process design, stronger data, clear authority, and measurable business value. The companies that connect those pieces can turn AI agents from experimental software into a controlled digital workforce.

    Frequently Asked Questions

    What is Agentic AI for enterprises?

    Agentic AI refers to AI systems that can handle multi-step tasks, use business tools, and take actions with limited human input.

    What benefits can Agentic AI offer businesses?

    Agentic AI can improve productivity, reduce process costs, speed up decisions, and support tasks across areas such as sales, finance, legal work, customer service, and IT.

    What are the main challenges with enterprise AI agents?

    Key challenges include poor data quality, security risks, unclear permissions, reliability concerns, high costs, and weak governance.

    Should enterprises give AI agents full autonomy?

    Full autonomy may suit low-risk tasks, while high-risk activities should retain human review and strict approval controls.

    How should a company start with Agentic AI?

    A company should select one valuable workflow, set clear goals, establish a baseline, limit agent permissions, and measure results before wider deployment.

  • Key Big Data Integration Strategies for Modern Data Teams

    Key Big Data Integration Strategies for Modern Data Teams

    Define Clear Data Goals

    Start every integration project with well-defined objectives. Clear goals help teams prioritize data sources, streamline workflows, and consistently measure successful outcomes.

    Ensure High Data Quality

    Clean, accurate, and complete data prevents errors downstream. Regular validation and deduplication improve analytics, reporting, and decision-making across business operations.

    Standardize Data Formats

    Use consistent formats for dates, names, and values. Standardization reduces conflicts and simplifies integration across multiple systems and platforms.

    Automate Data Pipelines

    Automated workflows reduce manual effort, minimize mistakes, and ensure timely data movement between applications, databases, warehouses, and cloud environments.

    Prioritize Data Security

    Protect sensitive information using encryption, access controls, and monitoring. Strong security safeguards customer trust while meeting compliance and regulatory requirements.

    Monitor Integration Performance

    Track pipeline health, latency, and failures continuously. Performance monitoring helps teams identify bottlenecks early and maintain reliable data operations.

    Use Scalable Integration Tools

    Choose platforms that handle growing datasets efficiently. Scalable tools support expanding business needs without sacrificing speed, reliability, or performance over time.

    Maintain Strong Documentation

    Document data sources, mappings, and workflows clearly. Comprehensive documentation improves collaboration, troubleshooting, onboarding, and long-term maintenance across data teams.

    Review and Improve Regularly

    Evaluate integration processes frequently using feedback and metrics. Continuous improvement ensures better efficiency, accuracy, scalability, and long-term business value for organizations.

  • Baris Ozcan: The Data Guardian Powering Enterprise Digital Transformation

    Baris Ozcan: The Data Guardian Powering Enterprise Digital Transformation

    As 59% of companies now run on SAP S/4HANA—a 13-point jump in a single year—the race to migrate from legacy systems before support ends in 2027 is accelerating. Yet many projects face delays and budget overruns, with data quality emerging as a critical underestimated challenge. A 2026 report by Precisely and ASUG highlights that demand for experienced SAP S/4HANA specialists could outpace supply threefold by 2027.

    German SAP consultant Baris Ozcan, with 18 years of experience, works at the heart of this invisible layer of digital transformation. He resolves data errors that can disrupt risk models, reporting, and operations within hours, rebuilding and stabilizing SAP systems that large enterprises depend on.

    When Data Models Become Mission-Critical Infrastructure

    In large companies, SAP BW systems process everything from financial reporting to logistics and risk calculations. When these systems fail, business operations can slow within hours. At a leading European automotive financial services company in Braunschweig, Ozcan oversees systems running around 2,000 automated process chains and 300 daily data loads connected to leasing, credit scoring, and regulatory reporting. His role is to find broken chains, restore data flow, and keep reporting stable under constant operational load.

    At Wieland Electric, he managed the SAP BW environment during a transition to S/4HANA—a project that went beyond technical migration to reassess data movement, reporting functions, and analytics evolution. “A migration to S/4HANA is not just about moving data,” Ozcan explains. “It is an opportunity to rethink how reporting, analytics, and business processes should work together. The real challenge is ensuring existing operations continue while preparing for the next stage.”

    Why Old Systems Are Difficult to Replace

    Many companies in Germany, Austria, and Switzerland still rely on older SAP systems that are hard to modernize. The shortage of specialists with hands-on experience in complex transitions compounds the problem. On a project for Messe Berlin, Ozcan helped transform event reporting and CRM data into a structured analytics setup, enabling real-time tracking of visitors, sales, and service operations—replacing previously static data.

    “A similar transformation occurred for KJO, an Aramco-related oil and gas operation, where I developed a reporting system linking supply chain data to the SAP analytical platform, switching from Excel to a centralized system with real-time KPIs,” Ozcan notes.

    The Invisible Layer of Digital Transformation

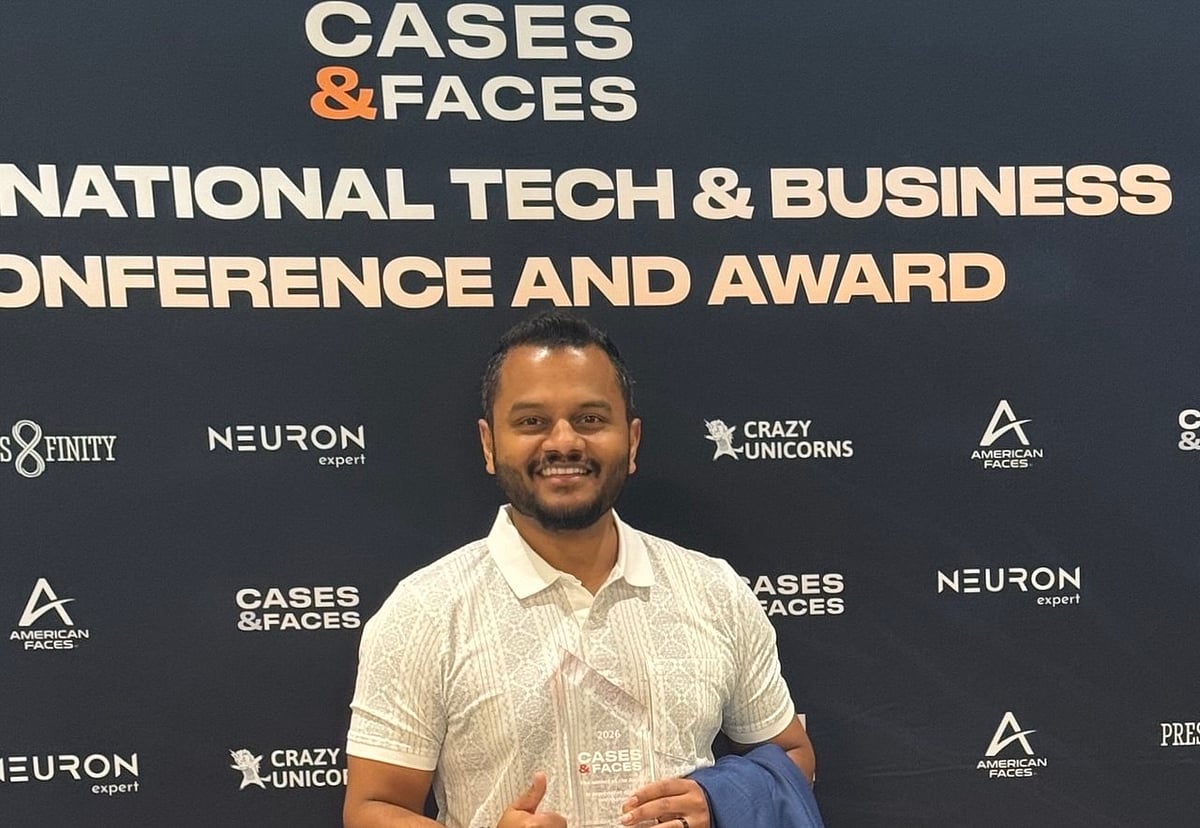
    While digital transformation is often associated with AI and user services, the foundational layer—data infrastructure—remains hidden but essential. Ozcan’s work across automotive, energy, logistics, and public sectors ensures data is structured, accurate, and decision-ready. His expertise is recognized through peer review and architectural evaluations. In 2026, he won the Cases & Faces award as “Innovator of the Year” in Digital Transformation.

    At KJO, he also created training and documentation to explain reporting setups and data flows, sharing knowledge that helps organizations build resilient systems. As companies modernize, specialists like Ozcan remain the unseen foundation of the digital economy, ensuring data reliability, consistency, and value.

  • Top 5 AI Pitfalls Businesses Must Sidestep in 2026

    Top 5 AI Pitfalls Businesses Must Sidestep in 2026

    Smart AI Adoption

    Artificial intelligence is becoming a key part of business operations in 2026. It helps companies automate tasks, improve customer experiences, and make faster decisions. However, AI delivers the best results only when it is used wisely. Avoiding these common mistakes can save time, reduce costs, and improve long-term business success.

    1. Using AI Without Clear Business Goals

    Many businesses rush to adopt AI because it is popular, not because it solves a real business problem. This often leads to wasted investments and disappointing outcomes. Start with a clear objective, identify the challenge you want to solve, and measure success using meaningful business results instead of hype.

    2. Ignoring Data Quality

    AI is only as good as the data it receives. Poor-quality, outdated, or incomplete data can produce inaccurate recommendations and unreliable predictions. Businesses should regularly clean, organize, and verify their data while maintaining consistent standards. Good data is the foundation of every successful AI strategy.

    3. Replacing People Instead of Supporting Them

    AI should enhance employees’ work rather than replace them entirely. Human judgment, creativity, emotional intelligence, and problem-solving skills remain essential in many business situations. Companies achieve the best outcomes when AI handles repetitive tasks, allowing employees to focus on innovation, customer relationships, and strategic decision-making.

    4. Forgetting Privacy and Security

    As AI systems process large amounts of business and customer data, security becomes more important than ever. Weak safeguards can lead to data leaks, legal issues, and loss of customer trust. Businesses should implement strong cybersecurity practices, limit data access, conduct regular audits, and follow all applicable privacy regulations.

    5. Skipping Employee Training

    Introducing AI without preparing employees often leads to confusion, low adoption, and misuse of the technology. Staff should receive practical training on how AI tools work, their limitations, and the best ways to use them responsibly. Continuous learning helps employees stay confident as AI continues to evolve.

    Bonus: Expecting Instant Results

    Many companies expect AI to transform their business overnight, but real success takes time. AI models require testing, fine-tuning, and regular improvements before delivering consistent value. Businesses that stay patient, monitor performance, and refine their AI strategy continuously are more likely to achieve sustainable growth and long-term competitive advantage.

    This article was originally published on Analytics Insight and has been adapted for our readers.

  • Data Engineering Cheat Sheet 2026: Essential Skills, Tools, and Architecture Trends

    Data Engineering Cheat Sheet 2026: Essential Skills, Tools, and Architecture Trends

    Data engineering is the foundation of every modern data system. Every website visit, online purchase, mobile app session, payment, and business transaction creates new information. That information has little value unless it is collected, cleaned, stored, and prepared for analysis. This is exactly where data engineering plays a major role.

    The need for skilled data engineers has grown rapidly because companies depend on data for daily decisions, automation, customer service, and artificial intelligence (AI). According to IDC, the world is expected to create more than 394 zettabytes of data by 2028, a huge jump from previous years. This massive growth has pushed businesses to build stronger and smarter data platforms that can support analytics and AI at a much larger scale.

    Data engineering is no longer limited to moving data from one place to another. It focuses on speed, quality, security, and reliability so that every team can trust the information they use.

    How a Data Engineering Process Works

    The data engineering process is structured straightforwardly. The process begins with the steps where data gets collected from external sources such as websites, mobile applications, sensors, software of the company, or databases.

    After data information has been collected, a series of preparation processes are conducted. The next stage of the process is the preparation of the data, where incorrect data is deleted, missing values are repaired, and data is formatted in a valuable way. After that, the collected data is checked for quality compliance.

    Finally, the collected data is ready for use in the generation of reports, machine learning models, dashboards, and other business applications. Each step has its specific role. Any issue at any step may lead to the failure of the reports, predictions, or AI models.

    Skills that Matter Most

    Recognized as one of the most sought-after profiles within the IT industry, data engineers require a combination of technical skills and hands-on problem-solving capability. Indeed, almost every database makes use of SQL.

    Knowledge of cloud technologies has become more critical than ever as many businesses today maintain their data in the cloud rather than in-house. Experience in counteracting bottlenecks and making quick fixes has been a plus in providing better and faster systems.

    As per the 2026 hiring trends, it is evident that employers favor hiring professionals who possess knowledge in traditional data engineering methods and also have working knowledge about AI.

    Modern Data Storage

    Data storage has changed a lot during the last few years. Data warehouses such as Snowflake, Google BigQuery, Amazon Redshift, and Azure Synapse Analytics remain popular because they support fast business reporting.

    Many organizations also use data lakes like Amazon S3, Azure Data Lake Storage, and Google Cloud Storage to keep large amounts of raw information at a lower cost.

    A newer approach called the lakehouse has become one of the biggest trends. Platforms such as Databricks, Apache Iceberg, Delta Lake, and Apache Hudi combine the strengths of both data lakes and data warehouses. This design gives businesses better flexibility without sacrificing performance.

    Batch Processing and Real-Time Data

    Not every business needs data at the same speed. Some reports only require updates once a day. This method is called batch processing. It suits financial reports, historical analysis, and large scheduled jobs because it costs less and stays simple to manage.

    Other businesses cannot wait for scheduled updates. Online payments, fraud detection, recommendation systems, and live dashboards need information within seconds. This approach is known as real-time processing.

    Many companies now use both methods together. Real-time systems handle urgent tasks, while batch systems process large historical datasets.

    What Makes a Strong Data Pipeline

    A reliable data pipeline contains several connected parts. Data first enters the system through source applications. After collection, it passes through processing layers that clean and organize the information.

    The pipeline also includes monitoring tools that detect failures before they become major problems. Security controls protect sensitive information, while backup systems reduce the risk of data loss. Together, these components help the entire system stay stable even as data volumes continue to grow.

    Why Data Quality Matters

    Good decisions depend on good data. Even small mistakes can produce incorrect reports or poor AI predictions.

    Modern platforms check for duplicate records, missing values, invalid formats, unexpected schema changes, incomplete information, and inconsistent records. Freshness also matters because outdated data can lead to wrong business decisions.

    Automated quality checks have become a standard feature in enterprise data platforms because manual reviews cannot keep pace with today’s data volumes.

    Cloud Platforms Continue to Lead

    Cloud technology has become the preferred choice for new data projects. Amazon Web Services, Microsoft Azure, and Google Cloud Platform continue to dominate this market. These platforms offer storage, processing power, data warehouses, monitoring services, and workflow management without the need for expensive physical servers.

    Companies also benefit from automatic scaling, which allows systems to handle larger workloads whenever demand increases. This flexibility has made cloud infrastructure the standard choice for businesses of every size.

    Popular Open-Source Technologies

    The role of open-source apps is notable today in the field of data engineering. Apache Spark brings a solution for the processing of huge data by distributing tasks across numerous machines. Apache Kafka has made it possible to achieve speed in data transmission between applications, and Apache Airflow provides solutions for planning and organizing complex operations.

    Other common technologies are Apache Flink, dbt, Apache Iceberg, Delta Lake, and Great Expectations. Apache Spark remains one of the most popular distributed analytics engines in the world.

    Data Models that Organize Information

    A good data model makes information easier to understand and analyze. The Star Schema works well for business reports because it keeps queries simple and delivers faster results. The Snowflake Schema reduces duplicate information through normalization, which saves storage space.

    Large enterprises often choose the Data Vault model because it keeps historical records, supports business growth, and adapts more easily when new data sources appear. The best model depends on business goals rather than company size alone.

    Security Cannot be Ignored

    Every data platform must protect valuable information. Encryption keeps data safe during storage and transfer. Identity management verifies who can access the system, while role-based permissions limit access to authorized users only.

    Many companies also use multi-factor authentication, audit logs, data masking, regular backups, and compliance checks to strengthen security. As AI becomes more common, strong governance and data protection have become basic business requirements rather than optional features.

    Better Performance Saves Time and Money

    Fast systems reduce costs and improve productivity. Engineers improve performance through partitioning, compression, efficient file formats, incremental updates, query optimization, metadata indexing, automatic resource scaling, and parallel execution. These methods reduce processing time and help businesses complete large workloads with fewer computing resources.

    Metrics Every Team Should Watch

    Successful data teams measure system performance every day. Important metrics include pipeline success rate, failure rate, processing latency, throughput, storage use, query response time, data freshness, infrastructure cost, resource utilization, and overall service availability. These numbers help teams detect problems early, improve efficiency, and maintain reliable operations.

    Biggest Data Engineering Trends in 2026

    Several trends continue to reshape the industry. AI now assists pipeline development and reduces repetitive work. Agentic automation handles routine engineering tasks with minimal human effort. Lakehouse architecture has become the preferred storage approach for many organizations.

    Metadata-driven pipelines, data contracts, unified governance, streaming analytics, intelligent cost optimization, and closer integration between machine learning and data engineering have also become common across modern enterprises.

    These advances allow companies to build faster, more reliable, and more intelligent data systems than ever before.

    Final Thoughts

    Data engineering has become one of the main components of modern technology. The effectiveness of different dashboards, analytical tools, AI systems, and business reports depends on well-organized data.

    The significance of reliable data solutions will acquire new meaning as the amount of data created worldwide may reach 394 zettabytes by 2028. It is expected that organizations that concentrate on robust security systems, high data quality, contemporary cloud solutions, and scalable architecture will be much more ready for the future.

  • Why Enterprise AI Projects Stall: A Data Foundation Problem

    Why Enterprise AI Projects Stall: A Data Foundation Problem

    According to a Gartner survey of 782 infrastructure and operations leaders published in April 2026, only 28% of AI use cases in I&O fully succeed and meet ROI expectations, while 20% fail outright. Thirty-eight percent of leaders who faced setbacks cited poor data quality or limited data availability as a direct cause. The conclusion increasingly shared across the industry is that the root of most AI failures lies not in the quality of the model itself, but in the underlying level of data and infrastructure.

    Few practitioners understand this from the inside as clearly as Sushrutha Sreevathsa, a Service Reliability Engineer at Yahoo, where he supports platforms serving more than 200 million daily users. A member of the D2A2 Council — an exclusive thought leadership group in Digital, Data, Analytics, and AI — and a contributing author to the AWS Marketplace publication Build Strong Data Foundations for Agentic Analytics and Intelligent Agents, Sreevathsa recently received the Cases & Faces International Business Award for Achievement in Product Innovation in the Data Analytics & Big Data category. We spoke with him about why enterprise AI keeps stalling, and what it actually takes to build the foundations that make it work.

    Adoption vs. Impact

    “Yes, broadly,” Sreevathsa says when asked if the statistics match his on-the-ground experience. “What I see across the industry matches what the research is pointing to: the adoption numbers are real, but the value is often not following. Part of that is because a lot of organisations are measuring the wrong thing. They track how many teams are using an AI tool, or how many dashboards have been built, and conclude that adoption is working. But adoption does not necessarily mean impact. The more honest question is: are decisions actually changing because of this data? And in many cases, the answer is no — because the underlying data is not in a state where people trust it enough to act on it.”

    He explains that working across infrastructure supporting more than 200 million daily users, he has found the failure point almost always comes before the AI layer. “Teams are generating enormous volumes of operational data, but when different parts of the organisation use different definitions, baselines, and reporting views, the AI ends up amplifying disagreement rather than resolving it — a sophisticated tool sitting on top of an unresolved problem.”

    Where AI Projects Actually Break

    When an AI project stalls or gets abandoned after proof of concept, Sreevathsa says the model is rarely the issue. “What is broken is usually one of three things: the data is not clean or consistent enough to be trusted, there is no clear ownership of what the data is supposed to mean, or the business question the AI is supposed to answer was never properly defined in the first place.”

    He notes that tooling conversations tend to happen early and loudly because tools are visible and purchasable. “The data foundation conversation is a lot less exciting to have in a board presentation — but it is the one that actually determines whether the project delivers measurable results.”

    The Connected Intelligence Operating Model

    Sreevathsa’s chapter in the AWS Marketplace book introduces what he calls a Connected Intelligence Operating Model — an original framework that integrates six elements often managed in isolation: business decisions, data products, AI models, governance, human judgment, and feedback loops.

    “Connected intelligence means that AI-enabled decision-making requires more than aggregating data from different sources. It requires building a coherent, governed layer where technical, operational, and business signals are all speaking the same consistent language. When a leadership team looks at a dashboard, every number should have a clear, agreed-upon meaning, and every person in the room should be working from the same version of reality.”

    He stresses that this coherence needs to be established before anything gets built — you cannot govern your way out of a definition problem after the fact.

    Solving the Data Trust Problem at Yahoo

    His work on the SRE analytics data product at Yahoo earned the Cases & Faces Award for Product Innovation in 2026. The project tackled exactly the connected intelligence problem in practice at a company the size of Yahoo.

    “When every team has its own reporting view, and those views have been in place for a while, people become attached to their version of the numbers. There is usually a legitimate reason why a particular team measures something the way they do, but when the goal is to give leadership a single, reliable picture of what is happening across the organisation, those differences become a problem.”

    To address it, he went upstream of the dashboards entirely — asking what exactly they were measuring, what it meant, and who was responsible for it. Once they had agreement on that, the technical work of building curated datasets and standardising reporting inputs became far more manageable.

    Making Definitions Explicit

    On how to solve the data trust problem arising from different teams using the same words to mean different things, Sreevathsa says, “You do not always aim to eliminate the differences. More often, you make them explicit and agree on what the canonical version is for a specific purpose.”

    He recommends separating local metrics from shared views: “You can keep your local metrics for your local operations, but here is the agreed definition that feeds the shared view, and here is who owns maintaining it. That ownership piece is critical. Definitions drift when nobody is accountable for keeping them stable. Once you assign clear ownership and document it, you have something that can be maintained and audited rather than argued over every quarter.”

    Real-World Impact: RevMon and Revenue Protection

    Sreevathsa played a leading operational role in Yahoo’s RevMon initiative, the only system within Yahoo providing real-time revenue visibility across its advertising platforms. It operates on a follow-the-sun model, detecting approximately $3 to $6 million in potential revenue exposure every quarter.

    “A significant part of it was the trust,” he explains. “The monitoring infrastructure was important — without real-time visibility into what was happening across Yahoo’s ad delivery systems, you simply could not catch revenue-impacting incidents fast enough. But what prevented losses was not the monitoring alone. It was the ability to act immediately when something surfaced — and that became possible because everyone was looking at the same data and could act on it without spending time on additional confirmation.”

    Anomaly as Operational Risk

    Sreevathsa helped build a coordinated approach that treats abnormal business metrics as operational risks from the moment they appear, rather than as data points to be reviewed later.

    “The core shift was in how the organization treated a business metric anomaly when it surfaced. In most environments, an unusual number in a revenue dashboard triggers a reporting workflow where it gets noted, logged, and may or may not prompt action depending on how serious it appears. What we built treats that same anomaly as the start of an operational response: there is a defined triage process, a clear escalation path, and accountability distributed across the teams who need to act.”

    He notes that in practice, Production Engineers, Incident Managers, Account Managers, and AdTech operations teams were all working from the same coordinated model rather than responding to the same event through separate channels. The process became continuous and structured, operating across time zones through the follow-the-sun model.

    What Separates Successful AI Organizations

    Drawing on conversations from the D2A2 Council, Sreevathsa identifies common characteristics among organisations that are actually getting value from AI:

    • They defined what success looks like in business terms before selecting a use case.
    • They treated data as a product — with owners, SLAs, and governance — rather than as an output of their systems.
    • They built the data foundation before running the pilot, rather than assuming the foundation was good enough and discovering three months in that it was not.

    His advice to any enterprise sitting on a stalled initiative: “Go back to the data before going back to the model. Not to run another audit, but to ask one specific question: do the people who are supposed to act on this AI output actually trust the data it is drawing from? If the answer is anything other than an unambiguous yes, that is where the work needs to happen. It is slower and less visible than running another proof of concept — but it is the only path to something that holds up in production.”

  • How Big Data Consulting Maximizes AI ROI Through Superior Data Quality

    How Big Data Consulting Maximizes AI ROI Through Superior Data Quality

    AI systems create value only when they can work with reliable business data. A predictive model trained on incomplete transaction records, a chatbot connected to outdated knowledge bases, or an AI agent using inconsistent customer data will usually produce limited results, regardless of how advanced the underlying model is.

    This is where big data consulting becomes critical for AI ROI. It connects data engineering, governance, integration, analytics, and business measurement into one implementation strategy.

    AI performance in enterprise environments depends heavily on the supporting data infrastructure. Production systems usually require stable ingestion pipelines, storage layers, governance controls, transformation workflows, and monitoring systems to operate reliably at scale.

    Why Does AI ROI Depend on Data Quality More Than on the Model Itself?

    Model performance alone rarely determines whether AI generates measurable ROI. In production environments, data quality often becomes the larger operational constraint.

    AI systems in enterprise environments continuously interact with business data across cloud platforms, operational applications, APIs, and storage environments. When this data lacks consistency, freshness, or governance, maintaining reliable AI performance becomes significantly more difficult.

    Poor Data Quality Creates Compounding Operational Problems

    AI workflows in enterprise environments commonly interact with multiple operational systems at once, from customer platforms and ERP environments to analytics pipelines and cloud storage layers. Weak governance or inconsistent data across these systems can significantly reduce operational reliability.

    Multiple industry studies, including research from Gartner and IBM, have shown that poor data quality contributes directly to rising operational costs, delayed decisions, increased compliance risk, and additional manual processing across organizations.

    Clean Data Usually Improves ROI Faster Than Model Upgrades

    In many projects, improving data consistency produces larger business gains than replacing the model itself.

    For example, a support automation system connected to fragmented CRM records may initially classify only 45–50% of tickets correctly. After customer records, ticket histories, and operational metadata are standardized through data analytics consulting, routing accuracy may improve significantly without modifying the underlying model itself.

    This is one reason why data analytics consulting services increasingly focus on data readiness assessments before expanding enterprise AI deployments.

    What Data Quality Issues Usually Prevent Companies from Getting ROI from AI?

    AI systems may struggle to generate reliable outputs when business data remains inconsistent across operational environments. Common data challenges include:

    • Data silos between departments
    • Legacy databases with inconsistent schemas
    • Poorly documented datasets
    • Duplicate customer information
    • Delayed analytics updates
    • Weak lineage tracking
    • Incomplete labeling structures
    • Limited monitoring visibility

    Many data analytics companies focus on resolving these issues before expanding AI deployments.

    How Should Businesses Prioritize Data Integration Before Scaling AI Initiatives?

    AI systems usually perform more reliably when core business data is integrated before automation expands across departments.

    1. Start with High-Impact Operational Systems

    AI systems often depend most on a small group of core operational platforms, including CRMs, ERPs, analytics systems, and transactional databases. Integrating these environments first can generate measurable ROI faster than rebuilding the entire data ecosystem at once.

    2. Stabilize Pipelines Before Expanding Automation

    Stable AI deployment usually requires lineage tracking, monitoring, schema validation, access controls, and synchronization reliability before automation layers expand across departments.

    What Metrics Should Be Used to Measure AI ROI in Data-Driven Projects?

    Many organizations initially evaluate AI through model performance alone. However, production AI systems are more commonly measured through business outcomes such as reduced operational overhead, faster execution, improved forecasting, and workflow efficiency gains.

    Operational Metrics Often Matter More Than Model Accuracy

    In production environments, businesses commonly evaluate AI initiatives using metrics such as:

    • Reduction in manual processing time
    • Faster reporting or decision cycles
    • Lower operational costs
    • Forecasting accuracy improvements
    • Workflow automation rates
    • Reduced support escalation volumes
    • Increased data accessibility across teams

    For example, an AI workflow that reduces manual invoice processing time by 40% may generate more measurable ROI than a slightly more accurate model operating inside an unstable workflow.

    Infrastructure Stability Also Affects ROI

    Data analytics services increasingly track operational infrastructure metrics alongside business KPIs, including:

    • Pipeline reliability
    • API uptime
    • Synchronization latency
    • Query performance
    • Data freshness
    • Monitoring coverage

    These metrics help companies evaluate whether AI systems can scale reliably without increasing operational overhead.

    How Do Big Data Consulting Companies Help Reduce Risk in AI Investments?

    As AI systems become more integrated with operational infrastructure, the financial and operational risks associated with poor data governance continue increasing.

    Data consulting services often help organizations reduce risk by:

    • Improving integration reliability
    • Standardizing governance policies
    • Expanding observability across pipelines
    • Monitoring synchronization quality
    • Reducing data inconsistency across systems
    • Establishing rollout and validation frameworks

    This helps businesses scale AI initiatives with greater operational stability and lower long-term maintenance overhead.

    What Is the Best Way to Align Data Modernization with Revenue, Efficiency, and Growth Goals?

    Effective data modernization typically starts with business operations rather than infrastructure selection alone. Many organizations first target workflows where poor visibility, fragmented systems, or delayed reporting create clear operational costs.

    These areas commonly include:

    • Forecasting systems
    • Customer operations
    • Financial analytics
    • Inventory management
    • Executive reporting pipelines

    This phased approach often improves ROI predictability while reducing infrastructure complexity during AI expansion.

    The Operational Side of AI ROI

    Enterprise AI is increasingly becoming an infrastructure challenge rather than only a modeling challenge. Reliable AI execution depends heavily on connected data systems capable of supporting ingestion, governance, transformation, monitoring, and operational synchronization at scale.

    For many organizations, this makes data strategy consulting a core part of long-term AI planning. Stronger data environments often lead to more stable automation, faster decision-making, improved forecasting, and more predictable business outcomes.

  • 10 Data Labeling Jobs That Power Modern AI: Roles, Skills, and Impact

    10 Data Labeling Jobs That Power Modern AI: Roles, Skills, and Impact

    Even though artificial intelligence may appear completely automated, human data labelers work behind the scenes to make computers smarter. These professionals train AI through data classification, annotation, and evaluation, teaching algorithms to recognize patterns, languages, images, and responses that drive future system performance.

    10 Data Labeling Jobs Driving the AI Revolution

    The rise of AI has diversified data labeling into specialized careers. Below are the ten most prominent data labeling roles supporting modern AI systems.

    1. Image Annotation Specialist

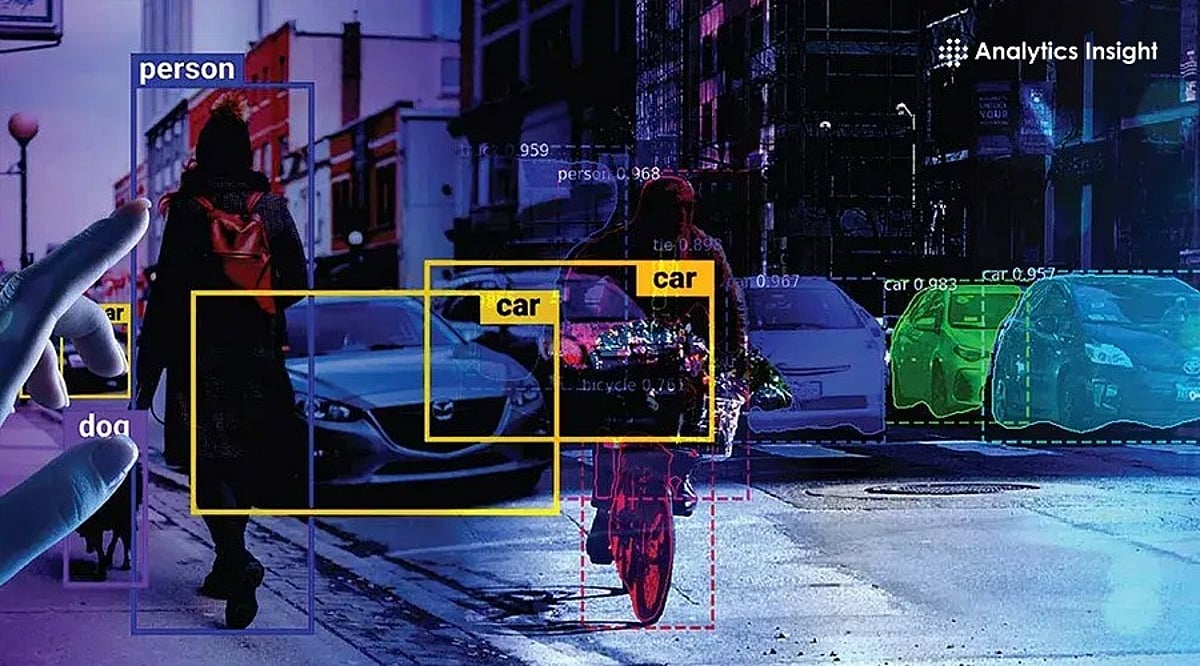
    Image annotators label objects within images using bounding boxes for cars, people, animals, and road signs. This work enables computers to identify visual elements and is critical for facial recognition, medical imaging, and autonomous driving.

    2. Video Annotation Professional

    While image annotation handles static images, video annotation tracks dynamic objects. Video annotators help computers understand motion, making them essential for autonomous driving, surveillance, and sports analytics.

    3. Text Classification Analyst

    These analysts categorize text into predefined classes—for example, distinguishing spam from legitimate emails, sorting customer reviews by topic, or grouping news articles by subject matter.

    4. Sentiment Analysis Annotator

    Businesses rely on sentiment analysis to gauge customer feelings. Annotators review text and label it as positive, negative, or neutral, enabling companies to understand public opinion at scale.

    5. Audio Transcription Specialist

    Voice‑powered AI requires vast amounts of annotated audio data. Audio transcription specialists convert spoken language into written text, capturing not only words but also speaker identity, accent, emotional tone, pauses, and background noise.

    6. AI Response Evaluator

    With generative AI on the rise, AI response evaluators assess chatbot outputs for quality, detect errors, and select the best responses to improve model performance.

    7. Content Moderation Reviewer

    These reviewers examine text, images, videos, and comments to identify harmful or rule‑breaking content. They apply labels according to platform guidelines so that automated systems can later detect unacceptable material.

    8. Data Quality Reviewer

    Annotation projects depend on quality control. Data quality reviewers verify completed annotations for accuracy and consistency, ensuring reliable training data.

    9. Domain Expert Annotator

    As AI expands into specialized fields, companies hire doctors, lawyers, engineers, financial analysts, and scientists to annotate data requiring deep subject‑matter expertise.

    10. Reinforcement Learning Trainer

    This emerging role involves crafting prompts, testing model responses, analyzing logic, and providing feedback. Such iterative human input significantly improves AI model accuracy over time.

    Required Skills for Data Labeling Jobs

    Entry‑level labeling roles may require minimal experience, but most positions demand attention to detail, consistency, and strong analytical abilities. Advanced roles often call for industry‑specific expertise or familiarity with AI workflows. Communication, critical thinking, and the ability to follow detailed guidelines are increasingly valuable as projects grow more complex.

    Why Data Labelers Are Essential to AI

    AI models require high‑quality training data to perform effectively. Human judgment provides algorithms with knowledge about objects, language structures, and correct responses. Every recommendation engine, virtual assistant, chatbot, and computer vision system rests on this human foundation. As AI evolves, data labelers move beyond simple tagging to analyze reasoning, evaluate model outputs, and apply their own expertise. Whenever a virtual assistant answers accurately or a self‑driving car identifies a pedestrian, a team of data labelers likely made it possible.