Tag: LLM

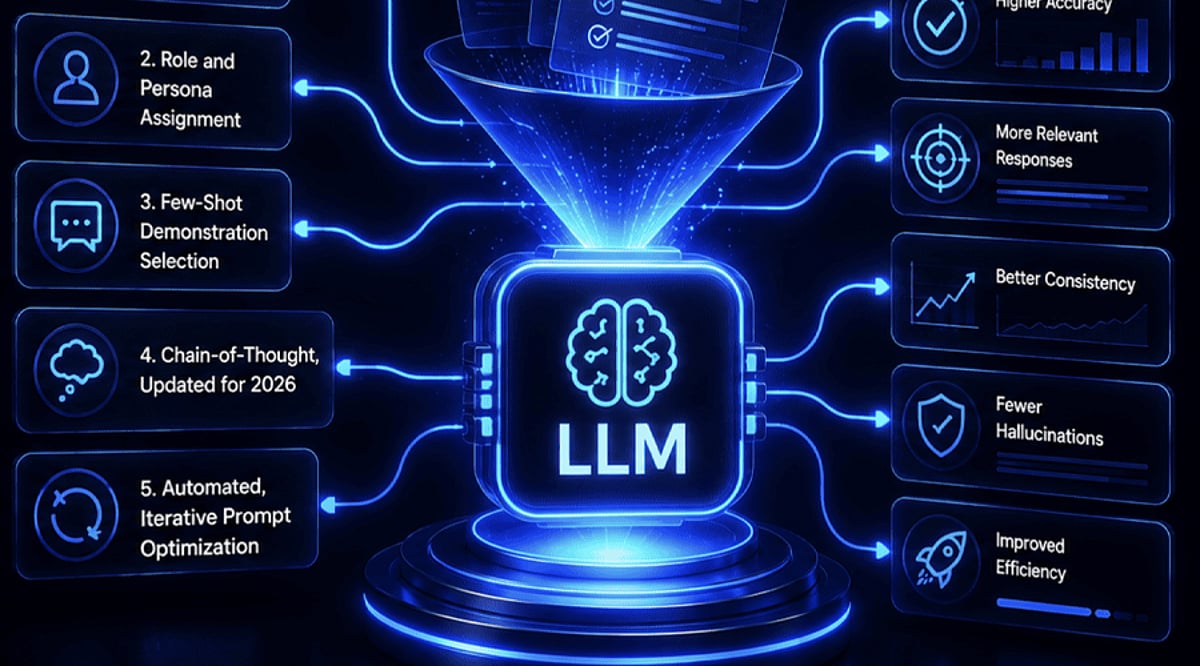
  • How to Optimize Prompts for Better, More Reliable LLM Output

    How to Optimize Prompts for Better, More Reliable LLM Output

    Large language models can produce impressive drafts, but the quality of the result depends heavily on the quality of the request. Prompt optimization is less about finding a magic phrase and more about removing ambiguity, giving the model the right boundaries, and refining the instruction until the output is useful.

    The techniques below can be used individually, but they work best together. They apply to content creation, research, coding, data processing, and any workflow where consistency matters.

    1. State the objective with precision

    Tell the model exactly what it should produce. Include the subject, format, tone, audience, and intended outcome. A vague request often leads to a broad response because the model has to fill in missing details.

    For example, instead of asking for an article about artificial intelligence, specify the length, structure, writing style, target reader, and any facts that must remain unchanged. Precise instructions reduce back-and-forth and make the first draft more usable.

    2. Supply relevant context without clutter

    Give the model enough background to understand the task. Useful context can include prior decisions, source material, definitions, examples, or specific requirements. For professional content, mention the audience and purpose.

    At the same time, avoid adding unrelated information. Too much context can make the prompt harder to follow and distract the model from the central task.

    3. Define constraints that shape the response

    Constraints make output easier to review and reuse. Specify word counts, formatting rules, the number of sections, writing style, prohibited elements, or information that should not change.

    For instance, asking for seven points with exactly 30 words each gives clearer boundaries than asking for seven important points. Consistent constraints also improve results when the same prompt is used repeatedly.

    4. Use examples to anchor style and structure

    When a desired style is hard to describe, show an example. A sample headline, paragraph, formatting pattern, or answer can help the model identify the pattern and apply it to new material.

    Examples are especially helpful for repetitive editorial, marketing, coding, and data-processing tasks where consistent output matters.

    5. Assign a role that fits the task

    Giving the model a relevant role can establish the perspective and expertise needed for an assignment. Instead of asking for a general analysis, you might ask it to act as a technology journalist, research assistant, editor, or coding reviewer.

    The role should directly relate to the task. Pair it with clear instructions about the expected output, audience, and limitations.

    6. Specify the output structure up front

    Tell the model how the final response should be organized before it starts generating. Tables, bullet points, headings, numbered sections, or predefined fields can make complex information easier to review.

    Structured output is particularly useful when content will be published, transferred into documents, compared across datasets, or processed by another system. A consistent format can also reduce editing time.

    7. Refine prompts through iteration

    A strong prompt does not always produce the ideal response on the first attempt. Review the output, identify what needs improvement, and adjust the instruction accordingly.

    You can ask the model to shorten sections, remove repetition, clarify explanations, or follow a specific structure. Iterative prompting turns the first response into a working draft rather than treating it as the final result.

    Putting the techniques into practice

    Effective prompt optimization combines clear objectives, focused context, useful constraints, examples, roles, output structure, and iteration. Start with a precise request, review the result critically, and refine the prompt until the output meets the standard required for the task.

  • Why Enterprise AI Chat Interfaces Fail in Production and How to Fix Them

    Why Enterprise AI Chat Interfaces Fail in Production and How to Fix Them

    Enterprise teams build AI chat interfaces, showcase smooth demos, and watch them break in production. The root cause often lies not in the model but in the frontend architecture. Connecting raw token streams directly to React components causes slow renders, lag, and broken state. This article explores why this happens and presents a robust solution.

    The Core Problem: Streams vs. UI Rendering

    AI chat operates differently from standard interfaces. Responses arrive as continuous event streams while users cancel requests, switch chats, or trigger tools simultaneously. The common approach of reading a POST response stream inside a React component—whether manually or with hooks like Vercel’s useChat—creates three critical couplings:

    • Schedule coupling: The component controls when the UI updates, but it shouldn’t.
    • Concurrency coupling: The component manages which stream may write, but this logic belongs elsewhere.
    • Protocol coupling: The component interprets raw bytes, but this is not its responsibility.

    How These Couplings Fail

    These couplings manifest in three main failure modes:

    1. Interaction Latency That Scales with Session Length

    As the transcript grows, each update takes more work to render. Once a task exceeds 50 ms, it blocks user input. When this delay pushes the interface beyond the 200 ms threshold for a good Interaction to Next Paint (INP), typing feels sluggish. Because the problem appears gradually, teams often blame the model instead of the architecture.

    2. Concurrency Races on Stop, Regenerate, and Switch

    When the current response lives in effect closures and isLoading booleans, there’s no central mechanism to decide which stream can update state. Switching conversations mid-stream can cause late events to update the wrong conversation. Open WebUI documents this: “Chat B’s content disappears—replaced by a loading state meant for Chat A.”

    3. Protocol Flattening

    AI providers send typed event streams, not plain text. For example, Anthropic’s protocol interleaves text, thinking, and tool-call deltas, with tool arguments arriving as partial JSON. Flattening these events into string concatenation loses meaning, leading to incomplete tool arguments, missed mid-stream errors, or truncated output stored as final content—corrupting the context for the next turn.

    The Correction: Ingest, Log, Project

    The solution introduces a boundary with three components, none of which import React:

    • Stream Ingestor: Handles the connection and provider events, turns them into typed application events, validates order, and assigns a run ID. Starting, stopping, or switching conversations creates a new ID, and late events are dropped. AbortController lives here, separating cancellation from the component lifecycle.
    • Conversation Log: The single source of truth. It records events in order and marks a response complete only when the provider sends its final message event (e.g., message_stop). A dropped connection cannot look like a completed answer. The log also serves as a test case and debugging trace.
    • Projection Scheduler: Converts the log into the state React needs to display. Using useSyncExternalStore, it updates the UI on a controlled schedule (e.g., frame budget or ~50 ms interval) instead of on every token. Per-message views remain referentially stable, so memoized components skip unchanged work.
    provider SSE / fetch stream
            |
            v
    Typed protocol events
            |
            v
    +-----------------------------+
    | Conversation runtime (no React) |
    | - Stream Ingestor: parse, validate, epoch-guard |
    | - Conversation Log: append-only, replayable |
    | - Projection Scheduler: frame-budget flush |
    +-----------------------------+
            |
            v
    useSyncExternalStore commit
            |
            v
    React component tree
    

    Trade-offs and When to Use This Approach

    The UI trails the stream by one flush interval, and the architecture requires more code than a simple hook. For short prototype sessions without tool calls, it’s probably unnecessary. The event log also needs periodic compaction. However, the payoff is that interaction cost stops growing with conversation length.

    Real-World Numbers

    In a benchmark comparing three versions of the same React chat harness, the naive architecture showed a p95 heartbeat-task lateness of 20.9 ms at 12 messages—acceptable at demo scale. But at 48 messages, each UI update took three times longer, frame rate dropped, and user interactions waited 61 ms before handlers ran. The naive version attempted 100 UI updates per second but managed only 38, saturating the main thread. The projection variant committed 5× less often and spent 12× less main-thread time, at identical perceived text speed.

    Conclusion

    Treat an LLM conversation as distributed-systems data: an ordered, typed, cancellable event log. The frontend should control when the UI updates. Review streaming state architecture like an API contract: Who controls the update schedule? Who decides which stream can write? Which events mark a response as complete? Measure interactivity at realistic conversation lengths, not demo lengths. A chat interface that feels responsive at message ten should not degrade by message fifty.

    References:

    • WHATWG. HTML Living Standard, §9.2 Server-sent events.
    • React Team. React v18.0 — automatic batching.
    • Google web.dev. Interaction to Next Paint (INP); Optimize long tasks.
    • Vercel. AI SDK UI: Chatbot—per-chunk renders and the throttle option.
    • Anthropic. Streaming Messages—event types and ordering.
    • Brysbaert, M. (2019). How many words do we read per minute? Journal of Memory and Language, 109.
    • Artificial Analysis. LLM output speed comparisons.
    • Open WebUI. Discussion #21462: chat switching causes race conditions.
  • New Open-Source Tool Makes Enterprise LLM Decisions Verifiable — Kirill Pechurin’s structured-eval

    New Open-Source Tool Makes Enterprise LLM Decisions Verifiable — Kirill Pechurin’s structured-eval

    Gartner recently warned that ungoverned decisions using LLMs will cause financial or reputational loss for enterprises. The fix, Gartner said, is to redesign analytic workflows around a required evaluation stage — a step most AI pipelines skip. Another Gartner prediction estimates that by 2027, 40% of enterprises will demote or decommission autonomous AI agents, with governance gaps surfacing only after a production incident. Strip away the framing, and both predictions describe that AI systems are already making structured, machine-actionable decisions inside enterprises.

    Kirill Pechurin, a senior software engineer at Arctera, has built a way to check whether any of those decisions is correct — the kind of check a pipeline can run before the output reaches the system that acts on it. He built and open-sourced structured-eval, a free tool under the Apache-2.0 license, specifically designed to catch structured LLM outputs that parse correctly but contain wrong values. He also led the development of an LLM-based system for procurement, delivery, and equipment-accounting automation, including a spec-reconciliation tool that cut manual work by roughly 30% and exposed the problem this article addresses.

    Where Hallucination Benchmarks Stop Mattering

    Most conversations about AI reliability center on hallucination rates in open-domain question answering — a chatbot inventing a citation or a search summary getting a fact wrong. Those numbers have improved. But those benchmarks test a model on clean questions and expect an answer in plain sentences, not what most business systems actually ask. In production, a model’s output is often a structured record — a JSON entry written straight into a database, a compliance check, or a purchase order — without a human looking at it first.

    “A mistake doesn’t look like ‘the model said something false’ in a way a reader could notice anymore. It’s now one buried detail, nested deep inside an otherwise correct-looking record, that doesn’t match reality. No one skimming a chat transcript would catch it. But the system downstream will still act on it.” — Kirill Pechurin

    That’s a significant blind spot. A model can pass every open-domain hallucination benchmark and still ship a record with a wrong quantity, a fabricated part number, or fields that contradict each other. Nothing in the pipeline checks individual fields against a source of truth — only whether the output parsed as valid JSON.

    The Procurement Tool That Never Throws an Error

    Kirill ran into this gap in back-office automation at Arctera. His procurement tools included a component that automatically reconciled technical specifications against vendors’ commercial proposals, and another that parsed vendor-supplied equipment specifications into structured records. The system cut manual operations by roughly 30% in a high-frequency decision workflow. But that also matches the risk Gartner warns about: an LLM’s structured output feeding directly into a real business decision, with no human necessarily reading the raw model response before it’s acted on.

    “A reconciliation error doesn’t throw an exception. The tool just quietly matches a spec to the wrong vendor line, and by the time anyone notices, the equipment’s already been ordered.” — Kirill Pechurin

    In such workflows, asking whether the output looks plausible is the wrong question. Asking whether a specific field matches the source document is the right one — and almost nobody had built the tooling to ask it systematically.

    Grading Structured Output Like an Auditor

    Building the procurement system left Kirill with an unsolved problem: the evaluation layer was missing. He built one and released it under an Apache-2.0 license. The result, structured-eval, is a software tool specifically designed to assess the quality of structured JSON or YAML LLM outputs. Instead of stopping at whether the output parsed into valid JSON, it:

    • Compares values field by field at any level of nesting
    • Checks outputs against a source document to catch fabricated or unsupported values
    • Enforces logical consistency across fields through a rules layer built for the purpose
    • Supports running evaluations across a full dataset rather than one output at a time
    • Tests whether a model gives a stable answer when the same prompt is run repeatedly

    “Running the same prompt twice and getting two different structured outputs is routine. Most evaluation tooling doesn’t even ask that question.” — Kirill Pechurin

    The framework is designed to sit alongside existing LLM-evaluation tools such as deepeval and LangSmith instead of replacing them. Pechurin frames the underlying idea: “There’s no such thing as one hallucination score. A quantity field and a description field fail in completely different ways, so each field gets scored with whatever comparison actually fits it, then those get combined.”

    A quantity field might need exact or near-exact numeric matching; a description field might tolerate paraphrase and reward it with a token-level similarity score; a status field might need strict enumeration matching with zero tolerance. Letting each field carry its own comparison method, then combining those into a composite score, is much closer to how a human reviewer actually audits a structured record than a single blended accuracy number ever is.

    What the Fix Actually Buys You

    That kind of infrastructure is the practical answer to the industry pattern. It’s cheaper to build field-level verification into a pipeline once than to discover, after a procurement error or a compliance gap, that nobody was checking. Organizations less likely to face after-the-fact governance failures — decommissioning agents after the damage is already done — are those treating structured-output verification as a first-class engineering problem rather than an afterthought.

    This isn’t the first time reliability work of this kind produced a large, measurable result. Earlier in his career at Consul Group, Kirill redesigned how a 1-million-plus-document Elasticsearch index handled updates, cutting query latency from 5,000 milliseconds to 500 milliseconds — a tenfold improvement. It’s a different problem than structured-output verification, but the same idea: not to assume a system behaves correctly at scale, but to measure it and rebuild the part that doesn’t.

    An LLM can be reliable in general and still be the wrong tool for a procurement pipeline if nobody checks whether its specific fields match the specific documents it was given. Kirill Pechurin built structured-eval to close this gap, giving enterprises a concrete way to check AI-driven procurement, finance, and compliance decisions before they ship.

  • 10 Best GenAI and Agentic AI Certifications to Future-Proof Your Career in 2026

    10 Best GenAI and Agentic AI Certifications to Future-Proof Your Career in 2026

    The AI job market is shifting toward professionals who can build, deploy, and manage intelligent systems instead of simply using AI tools. GenAI and Agentic AI courses provide structured learning with hands-on projects and industry-recognized credentials. The best programs can strengthen both technical expertise and long-term career prospects.

    Overview

    GenAI and Agentic AI courses develop practical skills in large language models (LLMs), AI agent frameworks, RAG, Model Context Protocol (MCP), AI governance, and autonomous AI system design for real-world applications. These programs cater to different experience levels, from beginners learning generative AI fundamentals to professionals building production-ready AI agents, enterprise workflows, and intelligent automation systems.

    University-backed and industry-recognized courses combine hands-on projects, technical expertise, and system-level thinking to prepare learners for AI engineering, product management, software development, and enterprise AI leadership roles.

    Prompt engineering got people through the door of Generative AI. Now the demand is shifting toward something bigger: professionals who can build, deploy, and govern autonomous AI systems that actually solve business problems. Certification programs are moving with that shift, leaving prompt basics behind and teaching production-ready AI skills instead.

    Generative AI courses teach people to use large language models to create content and applications. Agentic AI courses go further. They teach people to build systems that plan, use tools, maintain context, and finish tasks with little human input. That is why courses covering architecture, evaluation, and governance now carry more weight than courses built around prompting alone.

    How We Ranked the Best GenAI and Agentic AI Courses in 2026

    These ten are ranked by curriculum depth, verified hands-on project work, institutional accountability, and how directly the skills map to a real job function, from the complete beginner through the production engineer. That range is deliberate. A ‘top 10’ list that only serves engineers offers little to a product manager or executive searching for the same term.

    Top 10 GenAI and Agentic AI Courses at a Glance

    1. Learnbay – Generative AI & Agentic AI Master Program

    Most AI courses just teach tools or prompt writing. Learnbay takes a different path, helping learners apply AI directly in their existing fields. The Generative AI & Agentic AI Master Program mixes live classes, real projects, and guidance from actual industry practice. Topics covered include Generative AI, Agentic AI, RAG, LangChain, LangGraph, CrewAI, MCP, vector databases, LLMOps, AI deployment, automation, and responsible AI use. The focus stays on real work, not sample projects. Through AI Co-Lab and startup-style challenges, plus the Build Your Own Project (BYOP) program with a mentor guiding each step, learners build a portfolio worth showing employers. The projects are tailored to different fields too, including banking, healthcare, manufacturing, retail, telecom, and consulting. Classes run live on weekends, which works well for people balancing a full-time job. A three-year access period is also included, so the material stays available for future review. Career Services Pro adds further support with resume building, LinkedIn profile help, mock interviews, and placement assistance.

    2. Building AI Agents and Agentic Workflows (IBM)

    A three-course specialization that moves from LangGraph fundamentals to CrewAI multi-agent orchestration to AG2 and BeeAI, inside guided labs using real large language models such as GPT and IBM Granite. It works as a reasonable second step after a GenAI foundations course, though it remains a framework survey in nature. Learners wanting deep architecture or governance content will outgrow it fast.

    3. Full Stack Agentic AI Specialization (Coursera)

    This program moves past framework tours into ownership: RAG pipelines, the Model Context Protocol, vector databases, and backend orchestration. It suits engineers who want the whole stack under one roof rather than a single layer. The tradeoff is breadth over depth. Covering the full stack means less specialization in any one area than Cornell’s architecture-focused track offers.

    4. Master Agentic AI: Core Principles and Real-World Applications (Coursera)

    Built for people who already build ML models and need to operate agent systems at production scale: reward-signal design, CI/CD pipelines for retraining, drift detection, and threat modeling for agent security. The honest limitation is the prerequisite. Real ML fluency is assumed already. This program suits practitioners moving beyond prompting, not those starting from it.

    5. Applied Agentic AI Certificate (University of San Francisco)

    An intensive, in-person program with labs and a hackathon, built for people who need to understand agentic AI without writing code. It fills a genuine gap, since most agentic programs assume an engineering background. The cost is depth: graduates leave with strategic fluency, not implementation skill.

    6. Agentic AI Certificate Program (Johns Hopkins)

    A twelve-week, university-backed program covering Python, LLMs, RAG, and agent construction through applied projects, with weekly live sessions from faculty and industry experts. It sits between USF’s no-code approach and Coursera’s engineering-heavy tracks, a reasonable middle path for professionals wanting some hands-on coding without a pure software-engineering prerequisite.

    7. Agentic AI Architecture (eCornell)

    Four short courses over two months, focused not on building agents step by step but on designing the systems around them: LLM reliability, RAG, multi-agent workflows, and governance frameworks for responsible deployment. It suits architects, tech leads, and PMs who own decisions rather than code. Engineers wanting deep framework practice will find it thinner on implementation than IBM’s specialization.

    8. Generative and Agentic AI Certification (BITS Pilani Digital)

    A roughly 30-week program covering LLM applications, agentic systems, RAG, and deployment, built for technology professionals moving from experimenting with AI to architecting it. The length is the differentiator, for better and worse. It offers more depth than any other program on this list but demands a real-time commitment, closer to a part-time postgraduate course than a certification sprint.

    9. Agentic and Generative AI Course (IISc CCE with TalentSprint)

    An advanced program carrying IISc’s research credibility, relevant in India and among engineers who value an academic institution behind the certificate. It overlaps closely in content with BITS Pilani’s track, so the deciding factor usually comes down to institutional preference and location rather than curriculum difference.

    10. GitHub Certified: Agentic AI Developer (Microsoft)

    Four courses at 15 to 16 hours each, built for developers already working inside GitHub workflows and the software development lifecycle. It teaches agentic development inside tools people already use daily, which shortens the learning curve for that specific audience and narrows relevance for anyone outside it.

    How to Choose the Right GenAI and Agentic AI Certification

    Complete beginners fit best with Generative AI for Everyone before attempting anything agentic; every program past that point assumes basic LLM familiarity. Developers wanting hands-on framework practice suit IBM’s specialization or Coursera’s Full Stack track. Architects and technical leads gain more from Cornell’s system-design focus than from a coding-heavy specialization they will not use directly. Professionals wanting depth and university credibility should weigh BITS Pilani or IISc against the time commitment involved. Non-technical leaders get the most direct value from USF’s applied, no-code format.

    Final Thoughts

    The strongest certification is rarely the longest or the most recognizable name. It is the one that closes an actual skill gap. Whether that means understanding what generative AI even is, building production-ready agents, or governing how autonomous systems get deployed at scale.

    FAQs

    1. What is the difference between Generative AI and Agentic AI? Generative AI creates content such as text, images, code, and audio from user prompts, while Agentic AI enables systems to reason, plan, use tools, and complete multi-step tasks with minimal human intervention.
    2. Which GenAI and Agentic AI certification is best for beginners? Beginners should start with foundational Generative AI courses that teach LLMs, prompt engineering, and AI applications before advancing to Agentic AI courses focused on autonomous agents and workflow automation.
    3. Are GenAI and Agentic AI courses worth pursuing in 2026? Yes. As businesses increasingly adopt AI-powered workflows and intelligent agents, courses with hands-on projects and practical AI skills can improve employability and support long-term career growth.
    4. What skills should a good GenAI and Agentic AI certification include? A strong certification should cover prompt engineering, large language models (LLMs), retrieval-augmented generation (RAG), AI agent frameworks, workflow automation, AI governance, model evaluation, and real-world project development.
    5. How do I choose the right GenAI and Agentic AI course? Select a course based on your experience level, career goals, curriculum, hands-on learning opportunities, industry recognition, and whether it covers practical applications such as AI agent development, deployment, and enterprise AI solutions.

  • Why Financial Institutions Need Zero-Hallucination AI: Rethinking Data Architecture Before LLM Adoption

    Why Financial Institutions Need Zero-Hallucination AI: Rethinking Data Architecture Before LLM Adoption

    As financial institutions rush to deploy large language models, experts warn that unreliable data foundations—not model capability—remain the biggest barrier to trustworthy AI. Industry specialist Amit Sharma argues that zero-hallucination AI begins with resilient architecture, governed data pipelines, and real-time retrieval systems rather than larger models alone.

    The Hallucination Problem in Finance

    The financial sector’s growing interest in large language models has created new opportunities in automation, customer service, fraud detection, and operational intelligence. However, a central challenge continues to slow enterprise adoption: hallucination, the tendency of AI systems to generate inaccurate or fabricated responses. In highly regulated environments, where decisions must be precise, explainable, and traceable, even minor inaccuracies can carry serious financial and compliance consequences. As a result, many industry observers now argue that the path to zero-hallucination AI begins not with the model itself, but with a complete rethink of enterprise data architecture.

    Expertise in Mission-Critical Systems

    Among professionals working at the intersection of financial infrastructure and AI, Amit Sharma has emerged as a notable voice on this issue. With more than 17 years of experience in mission-critical data architecture, Sharma has built high-availability systems for major financial institutions and has developed expertise in both legacy database resilience and modern generative AI frameworks. His postgraduate certification in Artificial Intelligence and Machine Learning from the University of Texas at Austin further strengthened his focus on practical business applications of LLMs. His early work with advanced vector databases has also placed him among professionals exploring how traditional transactional systems can be combined with semantic AI search.

    Bringing AI to Governed Data

    According to Sharma, many institutions risk pursuing AI adoption while overlooking the weaknesses of fragmented data environments. He contends that moving sensitive information into disconnected AI silos often increases latency, raises governance concerns, and creates operational inefficiencies. Instead, he advocates bringing AI capabilities directly to governed enterprise data systems. This approach enables models to retrieve verified, real-time information from trusted sources rather than generating answers from incomplete memory.

    Retrieval-Augmented Generation as a Solution

    To address hallucination risk, Sharma has worked on Retrieval-Augmented Generation (RAG) frameworks designed to anchor LLM outputs in structured and unstructured enterprise data. By ensuring that responses are tied to a “single version of truth,” such systems can improve factual reliability while maintaining auditability. Furthermore, he has contributed to infrastructure strategies that separate AI inference workloads from core transactional systems, allowing financial platforms to preserve speed and stability while still benefiting from intelligent automation.

    Measurable Impact of Architecture-Led Strategies

    The measurable impact of such architecture-led strategies has been significant. Systems aligned with maximum availability principles have reportedly achieved 99.999% uptime standards, a critical benchmark for institutions where downtime can be costly. Meanwhile, the integration of vector search and optimized retrieval methods has reduced information lookup times by as much as 50 percent compared with conventional keyword approaches. At the same time, predictive autoscaling models have demonstrated the potential to lower long-term infrastructure costs by reducing unnecessary overprovisioning.

    Future Trends in Financial AI

    Nevertheless, Sharma believes the conversation around enterprise AI must move beyond productivity gains alone. He points to three trends likely to shape the next phase of financial transformation: autonomous self-optimizing infrastructure, convergence of transactional and vector data in a single query environment, and quantum-resistant encryption to secure sensitive records against future threats. Consequently, he argues that resilience, governance, and trust should become the primary design principles of any AI deployment.

    As financial institutions continue experimenting with generative AI, the industry’s next competitive advantage may depend less on who adopts LLMs first and more on who builds the strongest data foundations beneath them. Zero-hallucination AI, in that sense, is not simply a model challenge—it is an architecture challenge.

  • Revolutionizing Retail: How AI, Cloud, and Self-Healing Systems Are Reshaping the Industry

    Revolutionizing Retail: How AI, Cloud, and Self-Healing Systems Are Reshaping the Industry

    In an era where retail technology is evolving at breakneck speed, senior software engineer and architect Arundhati Kumar offers a deep dive into the innovations driving the future of omnichannel commerce. With over 15 years of experience building high-performance distributed systems across healthcare, banking, and now global retail, Kumar shares insights on how AI, cloud computing, and self-healing infrastructure are transforming the way retailers operate at scale.

    The Challenges of Engineering at Massive Scale

    When you’re supporting thousands of physical stores with diverse hardware—from legacy cash registers to modern mobile checkout apps—the biggest challenge is ensuring speed and reliability across unpredictable network conditions. Kumar explains that her team had to build custom adapter layers to standardize conflicting data payloads, and engineer systems that can instantly drop into offline mode, saving transactions locally and syncing back to the cloud once connectivity is restored—without losing a single cent of revenue.

    Checkout Doctor: A Self-Healing Solution

    Inspired by store associates struggling with checkout glitches, Kumar designed Checkout Doctor, an automated real-time diagnostic assistant. Instead of waiting for centralized IT support, the system analyzes local device logs, isolates issues like a scale malfunction or peripheral disconnect, and triggers alerts directly on the associate’s mobile device. This shifts the support model from reactive to proactive, keeping lines moving and reducing customer frustration.

    How AI Is Changing Site Reliability Engineering

    Large language models (LLMs) are revolutionizing incident detection by reducing the time engineers spend digging through disparate dashboards and logs. Kumar notes that feeding real-time error logs and alerts into an LLM provides on-call engineers with a plain-English summary of the problem, along with context from past incidents. This acts as an intelligent co-pilot, dramatically cutting the time to understand and resolve critical outages.

    The Measurable Value of AI in Operations

    Rather than fully automated fixes, Kumar believes the greatest value of AI today lies in extreme noise reduction and early triage. In massive enterprise setups, a single microservice failure can trigger cascading alerts. AI correlates telemetry spikes, filters out background noise, and points engineers directly to the root cause. Additionally, machine learning models can flag anomalies—like a spike in database latency—long before a threshold is breached, enabling preemptive patching.

    Lessons from Migrating to Cloud-Native Architecture

    Leading a migration from legacy relational systems to Azure Cosmos DB, Kumar learned that you can’t simply replicate old database patterns. Her team had to completely rethink data organization, grouping by store numbers and register lanes as partition keys, and accepting some data duplication. This trade-off slashed expensive cross-partition queries, kept cloud costs low, and ensured maximum availability during peak shopping seasons.

    Event-Driven Architecture for Real-Time Decisions

    Event-driven architecture replaces batch processing by treating every register action—a barcode scan, a voided item, a payment—as an instant event broadcast via websocket servers. This gives business leaders a live view of store performance and enables automated decisions, such as sending an alert to a nearby associate when an unusual pattern is detected during a live checkout session. It catches faults and errors before the customer leaves the lane.

    Combating Retail Shrink with Intelligent Automation

    Retail shrink is a multi-billion-dollar problem, but Kumar’s approach prevents losses at the checkout lane by linking real-time register logs with overhead camera feeds. If a missed scan or barcode mismatch is detected, the system pauses the session mid-transaction with a friendly nudge to rescan. If the issue persists, a silent notification goes to an associate’s mobile device, protecting the bottom line while keeping the experience seamless.

    Emerging Trends: Autonomous Infrastructure

    Looking ahead, Kumar is most excited about autonomous, self-healing infrastructure and edge-computed intelligence. Instead of using AI reactively to summarize logs after an outage, future systems will run predictive models directly on local edge hardware—like thousands of retail registers. These models will monitor health and transaction patterns, fixing anomalies autonomously (e.g., routing around a slowing database) long before a human engineer is alerted. This marks the end of the traditional on-call nightmare, turning software into something that actively looks after itself.

    Advice for Enterprise AI Implementation

    Kumar offers two key pieces of advice for leaders: First, build systems that survive locally without relying on the cloud. Local hardware must be smart enough to run in offline mode, catch errors, and make decisions on the spot. Second, treat AI as an intelligent co-pilot, not a replacement. Use a tiered intervention model: let the system handle noise reduction and simple self-healing, but when complex failures occur, use AI to arm engineers with a plain-English context summary rather than letting the machine guess blindly. Build guardrails that empower teams, not black boxes.

    As retail continues to evolve, the integration of AI, cloud, and self-healing systems is not just a trend—it’s a necessity. Kumar’s insights provide a roadmap for building resilient, customer-friendly technology that can handle the demands of modern commerce.

  • How Retrieval-Augmented Generation (RAG) Boosts AI Agent Accuracy and Reliability

    How Retrieval-Augmented Generation (RAG) Boosts AI Agent Accuracy and Reliability

    Retrieval-Augmented Generation (RAG) helps AI agents deliver accurate, up-to-date, and reliable responses by combining language models with external knowledge sources, making AI more useful for businesses and everyday applications.

    What Is Retrieval-Augmented Generation and Why It Matters

    Retrieval-Augmented Generation is an AI method that employs two distinct processes to produce written content. The first process finds useful information by searching documents, databases, web pages, or company records; the second process creates a full response using the information obtained from the first process. This combines two systems, providing the AI agent with knowledge that exists outside the language model. RAG allows AI systems to generate responses based on real documents instead of guessing.

    Key Benefits of RAG

    Better Accuracy

    Traditional AI models may answer questions with outdated or incomplete information because they cannot check new sources. RAG solves this issue by searching trusted documents before it creates a response, producing answers that are more correct and useful.

    Fewer Wrong Answers (Hallucinations)

    AI models sometimes create information that sounds correct but has no factual support—a problem known as hallucination. RAG greatly lowers this risk because the AI checks reliable information before responding, making AI agents far more dependable.

    Access to the Latest Information

    Knowledge changes daily with new laws, research, policies, and product updates. RAG removes the limitation of relying only on static training data by searching for current information whenever a question is asked, without requiring another training cycle.

    Better Use of Company Knowledge

    Organizations store vast amounts of information in reports, manuals, emails, and databases. RAG helps AI agents find the correct information from these resources within seconds, saving time, improving productivity, and enabling better decisions.

    Stronger Problem Solving

    Modern RAG systems search several sources before preparing a response, giving AI agents a broader understanding of complex questions. This leads to more complete answers based on multiple trusted sources.

    Lower Costs for Businesses

    Training a large language model requires powerful computers, expert teams, and a large budget. RAG offers a more affordable solution: companies only need to update their knowledge base instead of retraining the entire model, reducing costs while improving performance.

    Real-World Uses of RAG

    Many industries already depend on RAG-powered AI agents. Hospitals use these systems to find the latest medical guidelines. Financial institutions search market reports and compliance documents. Software companies help developers find technical documentation. Customer support teams search product manuals before answering questions. Legal professionals review contracts, regulations, and court cases much faster than traditional methods.

    Latest Industry Developments

    Industry reports from late 2025 show that AI agents have moved beyond testing into real business use. Google Cloud reported that 52% of companies using generative AI already operate AI agents in production, with 88% achieving positive returns on investment. Agentic RAG has played a major role in this success by improving accuracy, reliability, and response quality. Research in 2026 shows major progress in RAG technology, including better time-based knowledge management, improved document search, and support for structured database retrieval. Large technology companies have expanded enterprise AI platforms with stronger retrieval tools that connect AI agents directly to company knowledge bases.

    Challenges of RAG

    The quality of the final answer depends on the quality of retrieved information. Poor documents or weak search methods can still produce incomplete answers. Organizations need clean, accurate, and well-organized knowledge bases to maintain reliable results.

    Retrieval-Augmented Generation has changed how AI agents work. Instead of depending only on old training data, these systems search trusted sources before answering questions, leading to better accuracy, fewer mistakes, access to current information, lower costs, and stronger decision-making. Continuous research and new enterprise tools will make RAG even more powerful, helping AI agents become smarter, faster, and more dependable across many industries.

  • Why Data-Driven Enterprises Must Refine AI-Generated Language for Human Impact

    Why Data-Driven Enterprises Must Refine AI-Generated Language for Human Impact

    The integration of Large Language Models into enterprise infrastructure has fundamentally transformed data processing, automated reporting, and corporate communications. In today’s data-driven ecosystem, organizations are leveraging these sophisticated models to make sense of massive amounts of unstructured data and translate it into actionable insights at unprecedented speeds. From real-time financial analytics dashboards to comprehensive predictive market reports, artificial intelligence is changing the speed of information distribution at its core.

    As the initial novelty of rapid text generation wears off, data scientists and Chief Data Officers (CDOs) are facing a major qualitative hurdle. The output of language models is mathematically efficient, unfiltered, and unedited, but it often lacks the contextual nuance, empathetic tone, and rhythmic variance of natural human thought. To ensure that automated reports and executive briefings actually resonate with their intended human audiences, technology leaders are realizing that it is no longer sufficient to simply generate text at scale. Instead, they must actively deploy secondary Natural Language Processing (NLP) frameworks to humanize AI outputs, effectively bridging the critical gap between statistical probability and genuine human cognition.

    At its core, this qualitative issue stems from the fundamental architecture of generative models. LLMs operate on a predictive, probabilistic basis, calculating and selecting the next most likely token based on massive training datasets. From a data science perspective, this results in highly uniform, low-entropy output. In enterprise applications like automated data storytelling, business intelligence reporting, and client-facing analytics, this rigid syntactical structure becomes highly problematic.

    When text lacks the “burstiness”—the natural variation in sentence length, structural pauses, and conversational cadence—that characterizes authentic human writing, it inevitably triggers cognitive fatigue in the reader. The underlying data and analytical insights might be perfectly accurate, but the delivery mechanism is fundamentally flawed. This algorithmic predictability not only diminishes reader engagement but also raises valid concerns about the homogenization of corporate intelligence. When every enterprise utilizes similar foundational models, the unique brand voice and authoritative edge of the company are quickly lost in a sea of synthetic uniformity.

    In response to this influx of synthetic text, the broader technology industry has witnessed a rapid proliferation of digital auditing and verification tools. Today, it has become standard compliance protocol for enterprise governance teams, academic research institutions, and digital publishers to process incoming documents through a specialized AI checker to evaluate the origin of the content. These diagnostic algorithms are engineered to analyze the perplexity and structural predictability of a given text, searching for the unmistakable mathematical watermark of a machine.

    While these auditing tools are essential for maintaining data integrity, mitigating algorithmic bias, and ensuring transparency, they ultimately represent an incomplete solution. They serve merely as a diagnostic boundary rather than a developmental bridge. Knowing that an automated earnings report or a market analysis draft sounds robotic does not solve the underlying communication deficit. Furthermore, highly technical writing, such as data science whitepapers, often triggers false positives in these systems due to their naturally rigid structures. The enterprise challenge, therefore, is not merely to detect machine-generated text, but to actively refine it into a format that is virtually indistinguishable from expert human analysis.

    To address this critical limitation, the focus within the enterprise AI sector has shifted toward sophisticated structural refinement. The goal is to move far beyond the superficial replacement of vocabulary—a hallmark of early-generation text spinners that often destroyed contextual accuracy—and focus instead on the deep semantic restructuring of the text. By algorithmically introducing the natural cognitive friction, pacing variations, and empathetic tone found in genuine human communication, these advanced systems can effectively recalibrate synthetic drafts. This critical transformation ensures that the final narrative accurately conveys the underlying data without alienating the human reader on the receiving end.

    This necessary paradigm shift is giving birth to an entirely new layer of mission-critical enterprise software. Platforms designed for advanced linguistic recalibration are quickly becoming integral parts of the modern data pipeline. These tools serve as an invisible editorial and polish layer that lets organizations harness the immense computational scale and speed of generative AI while fiercely protecting the authentic, authoritative voice of their brand.

    With artificial intelligence becoming increasingly involved in every aspect of business intelligence, data analytics, and corporate activity, the biggest competitive advantage will not be solely in speed of generation. It will be the exclusive property of enterprises that master the integration of advanced refinement technologies, keeping their automated insights deeply, engagingly, and persuasively human.

  • From IIT to AI Search: The Unconventional Rise of Perplexity’s Aravind Srinivas

    From IIT to AI Search: The Unconventional Rise of Perplexity’s Aravind Srinivas

    In early 2025, Perplexity entered India through a major partnership with Bharti Airtel, giving millions of users access to Perplexity Pro almost overnight. On the surface, it looked like another telecom-AI announcement. Inside the technology industry, however, the deal carried a different meaning.

    A startup founded in 2022 was now entering India at a massive scale while positioning itself as an alternative to Google’s dominance in online search. Leading that company was Aravind Srinivas, a Chennai-born engineer who joined IIT Madras in electrical engineering and was unable to transfer into computer science after narrowly missing the required GPA cutoff.

    Perplexity’s rise has been unusually fast, even by Silicon Valley standards. According to reports citing investor discussions, the company reached multi-billion-dollar valuations within roughly two years of launch as investors rushed toward generative AI startups. At the same time, the company has faced growing scrutiny over attribution, scraping practices, and the legal boundaries surrounding AI-generated information products.

    What makes Aravind Srinivas’s story compelling is how imperfect and unpredictable it feels. His journey has been shaped by ambition, self-doubt, deep focus on research, strong product instinct, and constant public scrutiny, rather than a smooth path to success. Srinivas grew up in Chennai in a family where academic achievement was highly valued.

    In a conversation on the Lex Fridman Podcast, he spoke about the culture surrounding IIT admissions and the pressure attached to engineering entrance exams in India. By the time he entered the country’s competitive coaching ecosystem, academic performance had already become central to his life. That unexpected shift changed the direction of his learning.

    Instead of depending entirely on departmental coursework, he began teaching himself programming outside the classroom. He learned Python independently, enrolled in machine learning coursework available outside his department, and became involved in AI research under Professor Balaraman Ravindran.

    While still an undergraduate, Srinivas contributed to research connected to major AI conferences, including NeurIPS, AAAI, and ICLR. The experience exposed him early to deep learning research during a period when modern AI systems were still largely confined to academic labs rather than mainstream products. By the end of his undergraduate years, Srinivas had already moved across mathematics, coding, AI research, and systems thinking. The combination would later become central to his work in AI.

    He started pursuing his PhD in computer science at the University of California in 2017, where he worked on machine learning systems, generative models, and transformer-related research. Between 2019 and 2021, he interned at OpenAI, DeepMind, and Google Brain during the period just before large language models entered mainstream public attention. Those experiences became some of the most defining moments of his career.

    In podcast interviews, Srinivas said that when he entered environments filled with highly skilled engineers and researchers, he realized that he needed to improve his programming skills and ability to solve problems from the basics. He described the experience as motivating rather than discouraging.

    Instead of retreating from the field, he immersed himself more deeply in large language models and scaling systems research. The tone of those interviews felt very different from the polished image often associated with Silicon Valley founders. In those interviews, Srinivas spoke less about confidence and more about aggressively closing gaps in his own knowledge.

    In 2022, Aravind Srinivas co-founded Perplexity with Denis Yarats and Johnny Ho. Computer scientist Andy Konwinski also became an early supporter and close collaborator. The timing was important. Interest in generative AI was growing quickly, but internet search still mostly worked the same way it had for years, with users typing keywords and receiving pages of links.

    Perplexity tried to simplify that experience. Rather than functioning as a traditional search engine, the company positioned itself as an answer engine that used large language models (LLMs) to generate conversational responses while retrieving information from live web sources.

    Citations became an important part of Perplexity’s identity since many AI products were already facing criticism for hallucinations, where systems generate false or unsupported information. To separate itself from competitors, Perplexity designed its interface to display source links alongside AI-generated answers.

    Perplexity grew quickly as millions of users started using it for research, summaries, coding help, and everyday questions. Its partnership with Bharti Airtel later showed that the company’s strategy was not only focused on improving research quality but also on reaching more users through wider accessibility, especially in markets where smartphone usage was growing faster than traditional desktop search habits.

    But Perplexity’s rapid rise also brought intense criticism. In 2024, Forbes and WIRED reported that Perplexity had plagiarized paywalled content without giving enough credit to the original publishers. The Verge separately reported concerns around scraping practices that appeared to bypass publisher-set restrictions such as robots.txt preferences.

    Some publishers responded with legal threats, arguing that AI-generated summaries could reduce the value of original journalism. The issue soon grew into a larger debate about copyright, fair compensation, and the future of online publishing in the AI era.

    In posts published on X during mid-2024, Srinivas acknowledged shortcomings in Perplexity’s early attribution systems and said the company was working on improving citation visibility and publisher relationships.

    At the same time, he defended AI-powered search as an inevitable shift in how people would consume information online. That tension now sits at the center of Perplexity’s identity. The company is simultaneously viewed as one of the most promising consumer AI startups and one of the clearest examples of the unresolved conflicts shaping the modern AI industry.

    Aravind Srinivas’s rise from IIT classrooms to the center of Silicon Valley’s AI race does not offer a simple formula for success. His journey shows that the AI industry now values people who can quickly combine research, engineering, and product thinking, even without following a traditional career path.

  • Two LLMs Team Up to Help Robots Interpret Vague Instructions and Prioritize What Matters

    Two LLMs Team Up to Help Robots Interpret Vague Instructions and Prioritize What Matters

    Researchers at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) have developed a new method that uses two large language models (LLMs) to help robots understand ambiguous instructions and focus on key details. The approach, called Masked Inverse Reinforcement Learning (Masked IRL), reduces the amount of demonstration data needed to teach a robot by nearly five times, while improving the robot’s ability to infer unspoken user preferences.

    Traditional robot training often requires either extensive physical demonstrations or detailed written instructions. Masked IRL automates the process: first, one LLM clarifies ambiguous prompts (e.g., turning “stay close” into “stay close to the surface of the table”) by comparing a user’s demonstration trajectory to the shortest possible path. Then a second LLM evaluates the environment and “masks” irrelevant details – such as a person leaning on a table – while highlighting critical ones like obstacles to avoid. The robot then uses these prioritized details to generate a safe motion plan.

    In experiments, the system correctly identified unstated user preferences up to 15 percent more often than comparable baselines. Real-world tests showed a robotic arm successfully moving a coffee mug around a laptop, wiping a table while “staying close” to it, and handing a user a bag of chips while “staying away” from both the person and the table – all after fewer than 50 kinesthetic demonstrations.

    The team plans to enhance Masked IRL with camera input, allowing robots to visually focus on relevant objects in dynamic environments. The work was supported by the Tata Group via the MIT Generative AI Impact Consortium Award and the Department of Defense, and will be presented at the 2026 IEEE International Conference on Robotics and Automation.