Tag: observability

  • CTO’s Roadmap for AI Agent Infrastructure: From Copilots to Autonomous Systems

    CTO’s Roadmap for AI Agent Infrastructure: From Copilots to Autonomous Systems

    Overview

    AI agents require infrastructure beyond traditional model APIs and chatbot frameworks. Identity, sandboxing, observability, data access, and tool controls become essential as autonomy grows. CTOs can scale agent deployments more safely by combining automation with strong governance.

    The Shift from Copilots to Autonomous Agents

    AI agents are moving from workplace assistants into operational systems. This shift changes what enterprises need from their technology infrastructure. A copilot usually waits for a user instruction. An autonomous agent can plan tasks, call tools, and act independently. This difference has major infrastructure implications. CTOs now need more than model access and application APIs. They need secure runtimes, reliable data, strong identity, observability, and control. The architecture must also support changing models and agent behavior.

    Start with a Clear Agent Architecture

    The first step is separating the agent into distinct layers. The model handles reasoning and generates the next action. An orchestration layer manages prompts, workflows, tools, and handoffs. Data services provide business context, retrieval, memory, and application information. The runtime executes agent tasks and manages their state. A governance layer controls permissions, policies, security, and human approvals. This structure makes systems easier to manage and upgrade. Microsoft Foundry now brings models, agents, tools, security, and governance together.

    Build a Runtime for Real Agent Work

    Agents need an environment for more than text generation. They may inspect files, run code, use APIs, and modify business data. This makes runtime isolation especially important. A poorly contained agent can turn a simple error into an operational incident. OpenAI’s Agents SDK now includes sandbox execution for controlled agent workflows. Its updated architecture supports long-running tasks across files and tools. CTOs should define resource limits before deploying autonomous systems. These limits can cover network access, execution time, spending, and tool permissions. High-risk actions should also require explicit approval to keep automation from becoming uncontrolled.

    Treat Identity and Access as Core Infrastructure

    An agent should never receive broad access by default. Its permissions should match the task it is performing. Use separate identities for agents, tools, and workloads. Apply role-based access controls and short-lived credentials where possible. Tool access deserves the same discipline. An agent should not call payment, database, or administrative systems without strict controls. Microsoft’s current agent platform supports Entra identity and role-based access control. It also supports network isolation and policy controls for enterprise deployments. This model creates clearer boundaries between an agent and corporate systems.

    Make Observability Part of the Agent Stack

    Traditional application monitoring is not enough for autonomous systems. Teams need to understand what the agent did and why. This requires tracing model calls, tool usage, latency, failures, and costs. It also requires evaluating task quality and safety over time. Microsoft Foundry supports agent tracing, evaluations, and production monitoring. Its telemetry can include tool calls, inputs, outputs, latency, and token usage. OpenAI’s Agents SDK also includes tracing and observability capabilities. CTOs should treat these signals like application performance data. Agent quality can drift after model, prompt, or tool changes.

    Design for Data, Memory, and Tool Integration

    Agents become useful when they can access relevant enterprise context, which may come from documents, databases, APIs, or business applications. Retrieval systems need strong permissions and reliable source data. Memory also needs clear rules around storage, retention, and user access. Tool integration should use stable interfaces and explicit contracts. Model Context Protocol is gaining attention for connecting agents with external tools. Infrastructure teams should avoid building every integration from scratch. Shared tool registries can simplify authentication, versioning, and governance. Microsoft’s Agent Service supports shared toolboxes and managed MCP endpoints.

    Put Governance Around Autonomous Actions

    Greater autonomy creates greater responsibility for enterprise leaders. Agents can make mistakes faster when they operate without constant human input. Guardrails should therefore cover inputs, tool calls, outputs, and sensitive actions. OpenAI recommends layered guardrails with authentication and authorization controls. Keep human intervention available for high-risk operations. Examples include large refunds, financial transfers, account changes, or destructive actions. CTOs should also define clear ownership for every deployed agent. Someone must be accountable for its performance, security, and business impact.

    Moving from Copilots to Autonomous Systems

    The infrastructure shift is gradual, not a single technology upgrade. Organizations can start with copilots and expand autonomy as controls mature. Early systems may only suggest actions. Later versions can execute approved workflows with limited supervision. Fully autonomous systems require stronger safeguards and deeper operational visibility. They also demand better testing before reaching production. For CTOs, the goal is not maximum autonomy. The goal is useful autonomy that remains observable, secure, and controllable. This principle can shape the architecture long before agents become business-critical.
  • Ashutosh Kulkarni: Elastic CEO Driving Enterprise AI and Cybersecurity Innovation

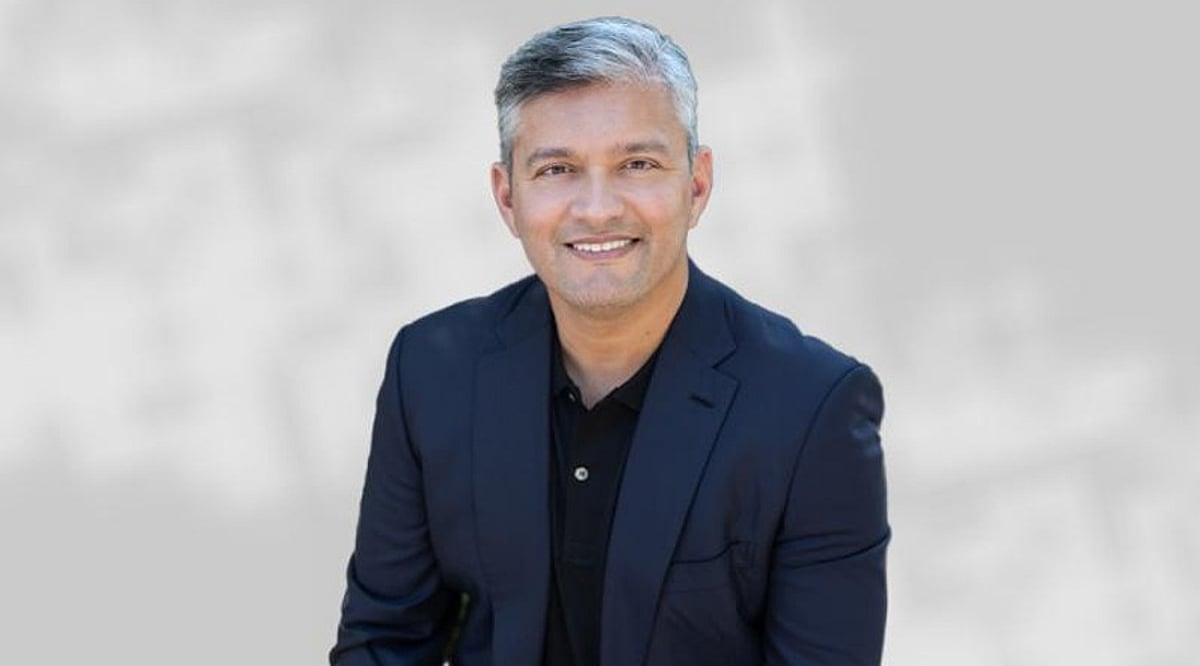
    Ashutosh Kulkarni: Elastic CEO Driving Enterprise AI and Cybersecurity Innovation

    Ashutosh Kulkarni is a seasoned technology executive and strategic business leader, best known as the Chief Executive Officer of Elastic. He has made significant contributions to artificial intelligence, enterprise search, cybersecurity, and cloud technologies. Prior to becoming CEO, Kulkarni held senior management roles at McAfee, Akamai Technologies, Informatica, and Sun Microsystems.

    Early Life and Education

    Kulkarni developed an early passion for engineering and technological innovation. He earned a Bachelor of Engineering degree from the University of Mumbai and a Master of Science in Computer Engineering from The University of Texas at Austin. He also holds an MBA in Marketing & Finance from the University of California, Berkeley.

    Professional Career

    Ashutosh Kulkarni began his career at Sun Microsystems before moving to Informatica, where he spent a decade leading cloud product initiatives. He then joined Akamai Technologies and later McAfee, holding various leadership roles. In 2021, he became Elastic’s Chief Product Officer, and in 2022, he was appointed CEO.

    Business Intervention in AI

    Under Kulkarni’s leadership, Elastic is advancing enterprise AI through an intelligent ecosystem that combines generative AI, agentic capabilities, AI-powered search, observability, performance monitoring, and cybersecurity to deliver scalable, secure, and high-performance digital experiences.

    AI Ecosystem

    Elastic’s unified AI ecosystem leverages Elasticsearch with leading AI platforms to provide vector search, RAG, safe deployment, and cloud-native capabilities, enabling businesses to build efficient and intelligent AI applications.

    Agentic Observability

    Agentic AI improves observability through log analysis, event detection, and natural language investigations. AI-driven insights accelerate root cause analysis, helping teams detect and resolve issues faster.

    AI Performance Monitoring

    AI enhances observability with distributed tracing, automated diagnostics, and AI-based troubleshooting, aiding in problem detection and improving application reliability.

    Agentic Security

    AI-powered security systems strengthen cyber defense through intelligent threat detection, automated investigations, explainable AI reasoning, and rapid incident response, improving visibility and minimizing response times.

    AI-Powered XDR Platform

    The AI-based XDR platform integrates automation, continuous monitoring, and intelligent threat analysis to effectively detect, investigate, and mitigate cyber threats.

    AI Infrastructure Intelligence

    AI-driven infrastructure observability provides anomaly detection, predictive insights, automated remediation, and natural language processing, speeding root cause analysis and increasing system resilience while reducing downtime.

    Business Achievements

    Ashutosh Kulkarni has expanded Elastic’s capabilities in AI, enterprise search, observability, and cybersecurity through innovative products and acquisitions. He has built strategic relationships with top technology companies such as OpenAI and NVIDIA. His leadership has driven consistent revenue growth and widespread enterprise adoption of Elastic’s software.

    Controversies

    As of now, there are no known controversies surrounding Ashutosh Kulkarni. He is widely respected for his expertise in enterprise AI, cloud computing, search technology, and observability. His leadership and technical skills have earned him an excellent reputation in the technology sector.

  • How Advanced Anomaly Detection Prevents Unplanned Outages Before They Happen

    How Advanced Anomaly Detection Prevents Unplanned Outages Before They Happen

    Across large energy operations, there is a gap — a space where the calmness of the control room contrasts sharply with thousands of sensors located throughout a vast, distributed network. All of those sensors have normal readings. Every sensor’s threshold is safe within its allowed range. No failure has occurred. No alarm has been triggered. And yet amidst that sea of normal data, small disturbances are developing. Those disturbances will eventually exceed some pre-determined value, light up the dashboard, and then the problem begins.

    That interval — between the time an issue first develops and when a system finally recognizes it exists — is where most unplanned outages occur. Traditional monitoring was developed to ask one simple question: has a particular value exceeded a given threshold? This type of monitoring uses pre-defined thresholds and static rules. It does its job. But it identifies neither slow degradation, nor anomalous correlations, nor faint indications that a system is deteriorating slowly before any individual measure indicates otherwise.

    For most of her career, Jasvitha Buggana has operated in the blind spot of traditional monitoring. She has advocated that the true effort related to reliability is not detecting failures but identifying small deviations before they develop into full-blown issues.

    Jasvitha Buggana is an engineer working at the intersection of operational systems and data analytics. She holds degrees in computer science from India and completed a master’s degree in business analytics in the United States. These two educational backgrounds influence how she interprets a failing system. Instead of asking if a given component is either up or down — purely through an infrastructure lens — she asks what a sequence of readings imply about customer experience, efficiency, and risk. In her opinion, anomaly detection is rapidly transforming from a technical capability into a strategic business discipline.

    The types of problems that affect businesses most often do not declare themselves. Systems can appear healthy on the surface while problems develop underneath. Devices continue to send reports but the cadence of the message changes slightly. A data feed continues to flow but quality decreases in ways no individual alert was designed to identify. Identifying these problems requires analyzing weak signals embedded in extremely high volumes of data, and doing it effectively involves using technical analysis conjointly with understanding how a business operates.

    One of the challenges associated with designing an effective analytical framework for anomaly detection is that each environment behaves differently. What would be considered normal for one distributed system could be indicative of a potential problem for another. Ms. Buggana develops analytical frameworks that distinguish ordinary operating behavior from actual departures from the norm. She is also transparent that this cannot be accomplished via a fixed rule book. To be effective, anomaly detection requires significant familiarity with both the data and the contextual information that generated it. An analytical framework that performs exceptionally well in one environment may perform poorly in another unless it has been fine-tuned to recognize routine behavior for that specific environment.

    Some of the solution lies in improving observability. Improved observability enables teams to obtain a clear picture of how signals interact and influence one another, rather than being presented with a wall of isolated metrics. When teams can visualize how one degrading feed influences downstream slowdowns, they investigate faster and spend less time chasing root causes. Much of this load can be carried by automation. Automation continuously monitors, freeing human operators from eyeballing dashboards for subtle changes and presenting them only with patterns worth their attention.

    Ms. Buggana cites confidence as the payoff. Many operations teams work within a reactive loop. Each fire breaker brings new challenges; each new challenge brings new fires to put out. Ms. Buggana’s work has focused on removing teams from this type of loop by applying analytical thinking to reliability issues so that emerging risks become visible early enough for action to take place. Ms. Buggana has provided bridge functionality between technical operations and analytics for large-scale initiatives related to operational data, system reliability, and performance optimization.

    Ms. Buggana frames the impact less as fewer failures and more as greater confidence. When teams trust their data and can see risks forming, they make decisions from positions of strength rather than scrambling after the fact. Investigation time drops. Problems caused by poor data quality and disruptions caused by connectivity issues are identified earlier. Reporting becomes more reliable and the operation feels less fragile.

    Ms. Buggana anticipates the tools will continue to improve. As machine learning advances, anomaly detection will provide more predictive capabilities, more context, and require less human intervention. However, Ms. Buggana is cautious not to hand over responsibility entirely to machines. She argues that the greatest value comes from pairing advanced analytics with human judgment, domain knowledge, and a culture that rewards taking action before disruption arrives.

    Ms. Buggana’s larger bet is about where advantage will come from next year. “The organizations that are successful next year will not necessarily be those with the largest datasets,” she stated. “They will be those which can convert data into foresight.”

  • AI Startup MyDecisive Raises $12M Seed Funding and Unveils Open-Source Observability Platform SmartHub

    AI Startup MyDecisive Raises $12M Seed Funding and Unveils Open-Source Observability Platform SmartHub

    AI DevOps startup MyDecisive has emerged from stealth with $12 million in seed funding and the launch of SmartHub, an open-source observability platform designed to help enterprises manage telemetry data more efficiently while reducing cloud costs.

    Founded by enterprise software veteran Ari Zilka, MyDecisive is taking a different approach in the crowded observability market. Instead of forwarding every log, metric, and trace to external monitoring platforms, SmartHub processes data closer to where applications run. This allows engineering teams to filter, secure, and route telemetry before it leaves their infrastructure.

    Open-Source Platform Targets Rising Observability Costs

    SmartHub is built on Kubernetes, OpenTelemetry, and Prometheus. It supports log processing, trace sampling, runtime controls, and automated workflows that help teams monitor applications without moving unnecessary data across cloud environments. As AI workloads grow, enterprises are generating more telemetry than ever. MyDecisive argues that processing data at the edge reduces storage requirements, lowers cloud spending, and speeds up operational decisions. The platform is fully open-source, allowing developers to deploy and customize it without being locked into a proprietary ecosystem.

    Octant Adds Enterprise Capabilities

    Alongside SmartHub, MyDecisive introduced Octant, its commercial platform for enterprise customers. Octant adds governance, security, automated runbooks, anomaly detection, and cloud auto-scaling on top of the open-source foundation. The company claims the combined platform can cut production operating costs by up to 90% and can be deployed within a day—estimates that have not been independently verified.

    Fresh Capital to Support Expansion

    Copper Sky Capital led the $12 million seed round. The funding will be used to expand product development and grow the company’s enterprise business. Zilka, who previously founded Terracotta and served as CTO at Hortonworks, emphasized that enterprises need platforms that can process operational data where it is created rather than sending everything to centralized observability tools.

    MyDecisive says its platform is already being used across sectors including financial services, healthcare, retail, and telecommunications. As enterprises expand AI deployments, the startup is positioning SmartHub as an open-source alternative for organizations looking to improve observability while keeping infrastructure costs under control.

  • Why Buying the Best AI Model Isn’t Enough Without Engineering Discipline

    Why Buying the Best AI Model Isn’t Enough Without Engineering Discipline

    McKinsey’s State of AI survey found that while 88% of organizations use AI, only 6% qualify as high performers, where AI actually delivers bottom-line impact. The bottleneck isn’t the model. It is the engineering discipline that moves a system from demo to deployment, and nowhere is that gap more visible than in payments, where a confident wrong answer costs real money.

    To understand what that discipline looks like in practice, we turned to Ankit Rawat, a senior software engineer at Meta Platforms in Seattle, currently leading observability and performance work for WhatsApp Business Payment flows. A Computer Science graduate of Rajiv Gandhi Technological University, Bhopal, Rawat did not arrive at this role through a shortcut. Over twelve years, at Yodlee, Snapdeal, Amazon, Wayfair, and now Meta, he has built, debugged, and scaled payment systems where failure was never abstract. In this article, he discusses what it takes to get enterprise AI to production, how engineering disciplines built across commercial environments directly apply to it, and what engineers need to understand before they ship.

    The problem most teams don’t build for

    That understanding begins with a problem most organisations have the opportunity to solve early, but rarely do. A single digital payment passes through authentication layers, fraud detection, bank APIs, settlement engines, and often several third-party providers. What distinguishes the teams that succeed is a different capability: they can also tell you where users abandon a flow, which steps in a transaction sequence are slow under load, and why one bank’s definition of a “completed” payment doesn’t match another’s.

    “Every component in a payment pipeline has its own idea of what success looks like,” Rawat explains. “A fraud engine might flag a legitimate transaction as risky, and the bank API returns a timeout that the settlement layer reads as a failure. You only find these mismatches if you trace the full journey, not just the individual services.”

    Building that kind of infrastructure is exactly the work Rawat has spent his career doing. At Meta, the observability initiative he designed and implemented now directly impacts over 100 teams. It started as a collaboration between four groups: the billing engineering team, the payments product team, a data science unit focused on user behavior, and a growth analytics squad tracking conversion funnels. Rather than measuring whether servers were “up” in the traditional sense, Rawat’s approach traces real user journeys step by step. Data scientists and product stakeholders suddenly could see patterns that no standard dashboard captured. One of those patterns revealed that Instagram’s payment surface, previously unmonitored at the product level, was generating significant abandoned transactions, a finding that directly informed what became a multi-year payments program for the platform.

    Seeing the problem before the customer does

    If failures are often invisible, the obvious response is to build better ways of watching. Yet traditional monitoring, “Is the server up? Are response times normal?” misses most of what goes wrong in a payment flow. A server can be perfectly healthy while users give up at a confusing authentication step or a misconfigured timeout.

    At Meta, where Rawat arrived in October 2023, he designed a cross-functional observability initiative spanning four teams: billing engineering, payments product, a data science unit focused on user behavior, and a growth analytics squad tracking conversion funnels, around a fundamentally different approach. Rather than measuring infrastructure health, it tracks real user journeys step by step: where people abandon a flow, which steps are inefficient, and where time disappears unexpectedly. Data scientists and product stakeholders suddenly had visibility into patterns that traditional dashboards never captured. One revealed that Instagram’s payment surface, previously unmonitored at the product level, was generating significant abandoned transactions, and the initiative eventually grew into a multi-year program reaching well beyond its original scope.

    “Best practices for product-level observability are highly organization-specific and not well documented publicly,” Rawat explains. “We had limited external references, so we defined our own approach and aligned stakeholders. Getting from four teams to a hundred meant making the tooling extensible enough that other groups could plug in their own journeys without rebuilding the whole framework.”

    The parts of payment infrastructure nobody celebrates

    While everyone benchmarks processing speed and tracks uptime, the failures that actually cost money tend to hide in places nobody thinks to look. At Meta, Rawat designed a log optimization solution that reduced network data packet size by roughly 20% while preserving data integrity – saving terabytes of storage every day. Without that kind of efficiency, the cost of observing payment systems at scale becomes prohibitive, and teams lose the very visibility they need to catch problems early.

    A separate cross-team initiative he led tackled billing and payment error rates directly. Working with three or more partner teams, Rawat’s effort cut failure rates by approximately 60% across multiple products supporting around $20 million in annual business value.

    “What surprised people was that we didn’t need to rearchitect anything,” Rawat says. “Most of the improvement came from finally being able to see where errors actually originated. Once you separate infrastructure noise from real user-side failures and build feedback loops tight enough to validate fixes in days, the error rate drops fast. The hardest part is getting three teams with different priorities to agree on a shared definition of what ‘fixed’ means.”

    What India’s AI moment actually requires

    India is building the payment infrastructure that will test these principles on a national scale. On March 2, India and Israel signed a memorandum of understanding to link India’s UPI (Unified Payments Interface) with Israel’s MASAV system, as reported by Electronic Payments International – making Israel the eighth country to adopt India’s real-time payment protocol. UPI already surpassed Visa in daily transaction volume in 2025 and now handles over 700 million transactions a day. Every new country added to the network introduces new settlement protocols, new regulatory requirements, and new categories of failure that domestic testing never anticipates.

    “Getting a system to work in a demo is the easy part. The real challenge begins when it goes live, when real users depend on it, and a single bad answer, a single failed transaction, is unacceptable. You have to know, before it ships, every way it can break,” Rawat says. “India has the scale and the ambition. What it needs are engineers who understand from experience where these systems break, not because they read about it, but because they shipped something that failed and learned from it.”

    For India’s payments infrastructure to function at the scale it is being designed for, it must be underpinned by engineers who understand from experience where these systems need to be strengthened – engineers who learned by shipping and were held accountable for the outcomes.

  • Top 5 AI Agent Performance Issues and Engineering Solutions for Production Systems

    Top 5 AI Agent Performance Issues and Engineering Solutions for Production Systems

    Many AI agent failures stem from system design rather than limitations of the underlying model. Runaway loops, context drift, and poor tool orchestration can reduce accuracy while increasing costs. Practical engineering safeguards help prevent these issues and create more dependable production systems.

    Overview

    • Most agent failures trace back to five root causes: runaway loops, tool misuse, memory rot, weak grounding, and uncoordinated multi-agent handoffs.
    • Each failure carries an operational signal worth tracking, such as tool-call fidelity, handoff latency, or hallucination rate, before damage compounds.
    • Fixing agents is a systems engineering problem rather than a prompting problem, and continuous evaluation has become standard practice across mature 2026 production stacks.

    The biggest risk to an AI agent is not a weak model. It is a system that looks reliable until real users, live data, and unpredictable situations expose its flaws. Most production failures come from engineering choices, not model capability. How an agent plans work, selects tools, manages context, and coordinates with other agents determines whether it performs reliably or fails under production pressure. Performance goes beyond accuracy. It includes latency, cost, task completion, and reliability. This is why engineering teams now rely on observability, catching regressions before they ever disrupt production.

    Runaway Loops and Unbounded Execution

    Repeated tool calls, where an AI agent uses external tools such as APIs or databases to complete a task, rarely signal a weak model. They usually point to missing execution constraints in the orchestration layer. Without a hard stop condition, an agent has no built-in reason to quit even after progress has clearly stalled, and every extra loop burns tokens and time.

    The fix starts with runtime limits: a maximum number of steps, a cap on tool calls, and a token budget set per task. Pairing these limits with a simple progress check that compares the latest output with the previous step helps detect stalled runs early. If no new information is produced, the run aborts instead of continuing. Deduplicating repeated tool arguments closes the most common variant of this failure, where an agent quietly retries the same query with identical inputs.

    Tool Misuse and Weak Orchestration

    Agents given too many tools tend to pick the wrong one, pass malformed arguments, or invoke a tool call that does not match anything registered in the system. Many engineering teams track tool-call fidelity, the ratio of attempted calls to clean, error-free results, as an operational signal. A sustained decline typically indicates a mismatch between the agent’s understanding of a tool and the tool’s actual schema.

    The exact threshold worth flagging varies by team and workload. Restriction and validation solve most of this: give the agent the smallest tool set the task actually needs, validate every argument against a predefined schema before execution, and route simple requests away from the agent entirely when a direct API call would do the job faster.

    Memory Rot and Context Drift

    Long-running agents do not simply forget details. Their working memory can actively corrupt itself over time. Engineers sometimes call this memory rot: small errors in an agent’s own reasoning trace accumulate across a long task, and each step continues to look locally coherent even as the overall state drifts from what is actually true. Multi-agent chains make this worse, since one agent can pass its already-degraded context downstream, and the next agent builds on that flawed foundation with full confidence.

    Treating context as a working surface rather than a permanent record fixes this at the root: summarize aggressively once a thread grows long, keep a single source of truth for any fact that matters, and separate durable memory from disposable conversation history.

    Weak Grounding and Unmeasured Hallucinations

    An ungrounded agent answers with confidence even when it is wrong, and this often surfaces only after a bad output has already triggered a downstream action. Grounding reduces this risk through retrieval from live or verified data, citations for high-risk claims, and human review before high-impact actions are executed.

    Mature engineering teams run golden-set evaluations after prompt, workflow, or model updates and monitor hallucination rates through automated pipelines instead of assuming quality holds steady between releases. Expanding an adversarial test set over time catches regressions before users ever notice them.

    Multi-Agent Coordination and Prompt Injection

    Multi-agent workflows raise a new challenge: coordination now rivals reasoning in importance. One common failure is the infinite handoff loop, where Agent A passes a task to B, B forwards it to C, and C sends it back to A, with no single agent owning the outcome. Every transfer raises the risk of context degradation and slows completion.

    Clear task ownership and well-defined handoff rules prevent these failures. Multi-agent systems also face prompt injection risks, where malicious instructions hidden in documents, emails, or tool outputs can alter an agent’s behavior. Marking external content untrusted by default, separating read and write permissions, and requiring approval for sensitive actions help contain these attacks.

    Tracking the right operational metrics helps teams verify that these engineering improvements continue to work as production workloads evolve.

    Final Thoughts

    An AI agent succeeds or fails less on model capability and more on system design. Production-ready agents carry clear guardrails, measurable performance, and well-defined ownership from the start. Engineering discipline, backed by steady monitoring and evaluation, is what lets these agents run reliably at scale.

    Frequently Asked Questions

    1. What are the most common AI agent performance problems?

    The most common AI agent performance problems include runaway execution loops, tool misuse, context drift, weak grounding, prompt injection, and poor coordination between multiple agents. These issues can reduce reliability, increase costs, and affect task completion in production environments.

    2. Why do AI agents fail in production even when they work in testing?

    AI agents often perform well in controlled environments but encounter unpredictable inputs, live data, and complex workflows in production. Weak orchestration, missing guardrails, poor context management, and inadequate monitoring are common causes of production failures.

    3. How can engineering teams improve AI agent reliability?

    Engineering teams can improve reliability by setting runtime limits, validating tool calls, maintaining accurate context, grounding outputs in trusted data, assigning clear task ownership, and continuously monitoring performance through operational metrics and evaluations.

    4. Which metrics should be tracked to evaluate AI agent performance?

    Important AI agent evaluation metrics include task completion rate, tool-call fidelity, latency, token consumption, hallucination rate, handoff latency, and security-related indicators. Monitoring these metrics helps identify performance regressions before they affect production systems.

    5. Why is observability important for AI agents?

    Observability provides visibility into how AI agents execute tasks by tracking execution traces, tool usage, latency, token consumption, and system behavior. It helps engineering teams detect failures early, troubleshoot issues faster, and maintain reliable performance as workloads evolve.

  • Why Observability and Reliability Are Critical for Enterprise Generative AI Systems

    Why Observability and Reliability Are Critical for Enterprise Generative AI Systems

    Traditional monitoring can confirm that servers are healthy yet still leave engineers blind to why an AI agent made a wrong decision. Ayush Jain, a software engineer who has built large-scale search, machine learning, and distributed systems, explains why observability and evaluation are becoming the foundation of trustworthy AI at enterprise scale.

    An AI agent finishes its task. Every API call returns cleanly, logs are green, dashboards show no errors—yet the answer is wrong. Nobody can explain why. This gap between a system that looks healthy and one that actually performs correctly is the problem Jain has spent his career addressing. He belongs to a group of engineers building the unglamorous layer beneath enterprise AI: the pipelines, traces, and telemetry that let teams see what autonomous systems are really doing.

    “Traditional monitoring can confirm that infrastructure is healthy,” Jain says, “but it often fails to explain why an AI system made a particular decision or produced an unexpected outcome.”

    For two decades, deterministic software left clear fingerprints when it broke: error logs, exceptions, failed health checks. Agentic systems do not work that way. They reason in probabilities, select their own tools, pull in outside context, and plan across multiple steps. These agents introduce entirely new failure modes. “An agent may successfully execute API calls while still producing incorrect outcomes due to flawed reasoning, poor tool selection, or incomplete context,” Jain adds. The pipes all work, but the judgment does not. Standard monitoring stacks, built to watch the pipes, never notice the failure.

    Jain learned this lesson at scales where small problems become expensive. At Bloomberg, he contributed to search and ranking systems supporting hundreds of thousands of user interactions across more than one hundred million documents. A search result that drifts a few points in relevance does not throw an exception, but at that volume it quietly degrades the experience for thousands. To catch such drift, he helped build observability pipelines that processed millions of telemetry events per day—turning raw system exhaust into real-time signals about search quality, user behavior, performance, and anomalies. The goal was not just to confirm machines were up, but to close the distance between an idea that worked in an experiment and a system that held up in production.

    At Microsoft, Jain has focused on AI agent platform infrastructure. The central challenge: failures are now behavioral rather than infrastructural. An agent that calls every API correctly can still choose the wrong tool, reason poorly, or act on incomplete context. So the platform must watch behavior, not just uptime. The systems he worked on capture execution traces, monitor how workflows resolve, collect telemetry about agent conduct, and let teams run the same task across different configurations to see which performs best. This is the difference between knowing a process finished and knowing it finished for the right reasons.

    Jain sees the industry shifting from optimizing model performance to optimizing whole AI systems. “I believe the industry is shifting from optimizing model performance to optimizing AI systems,” he says. For years the scoreboard was the model—a higher benchmark, a better accuracy number. But a benchmark is a single moment, while an agent makes sequences of decisions across tools and steps. Accuracy and precision stop describing what matters. “Agent behavior must be evaluated continuously rather than treated as a one-time model validation exercise,” Jain emphasizes. The metrics that count look less like test scores and more like operations reports: task completion, reasoning quality, tool effectiveness, cost, safety, and alignment with business intent.

    He draws an analogy with cloud computing and Site Reliability Engineering (SRE). “Enterprise AI is entering a phase similar to what cloud computing experienced during the rise of Site Reliability Engineering,” Jain explains. Cloud services eventually stopped being judged solely on speed and started being judged on uptime and latency that everyone could see. AI will follow the same arc, with a new vocabulary of behavioral measures: hallucination rates, reasoning consistency, retrieval effectiveness, policy adherence, and workflow completion. “I believe AI Reliability Engineering will become a foundational discipline,” he says. Companies that build it into their platforms early will hold a real advantage over those that bolt it on after something breaks.

    The attention has long gone to models and clever outputs. But Jain argues the durable problem sits one layer down: in whether anyone can explain, measure, and trust what the system did. “The challenge is no longer simply generating intelligent outputs—it is creating systems that make those outputs explainable, measurable, and trustworthy at scale.” He expects the next generation of enterprise platforms to make observability and evaluation first-class architectural components rather than afterthoughts, with online evaluation, execution traces, and feedback loops catching trouble before users do.

    His conclusion is plain: “Making AI systems measurable, explainable, and reliable is essential for successful enterprise adoption at scale.” The companies treating that as the real engineering challenge are the ones whose AI will still be trusted a year after the demo. The rest are flying on green dashboards, learning the hard way that healthy is not the same as right.