Across large energy operations, there is a gap — a space where the calmness of the control room contrasts sharply with thousands of sensors located throughout a vast, distributed network. All of those sensors have normal readings. Every sensor’s threshold is safe within its allowed range. No failure has occurred. No alarm has been triggered. And yet amidst that sea of normal data, small disturbances are developing. Those disturbances will eventually exceed some pre-determined value, light up the dashboard, and then the problem begins.
That interval — between the time an issue first develops and when a system finally recognizes it exists — is where most unplanned outages occur. Traditional monitoring was developed to ask one simple question: has a particular value exceeded a given threshold? This type of monitoring uses pre-defined thresholds and static rules. It does its job. But it identifies neither slow degradation, nor anomalous correlations, nor faint indications that a system is deteriorating slowly before any individual measure indicates otherwise.
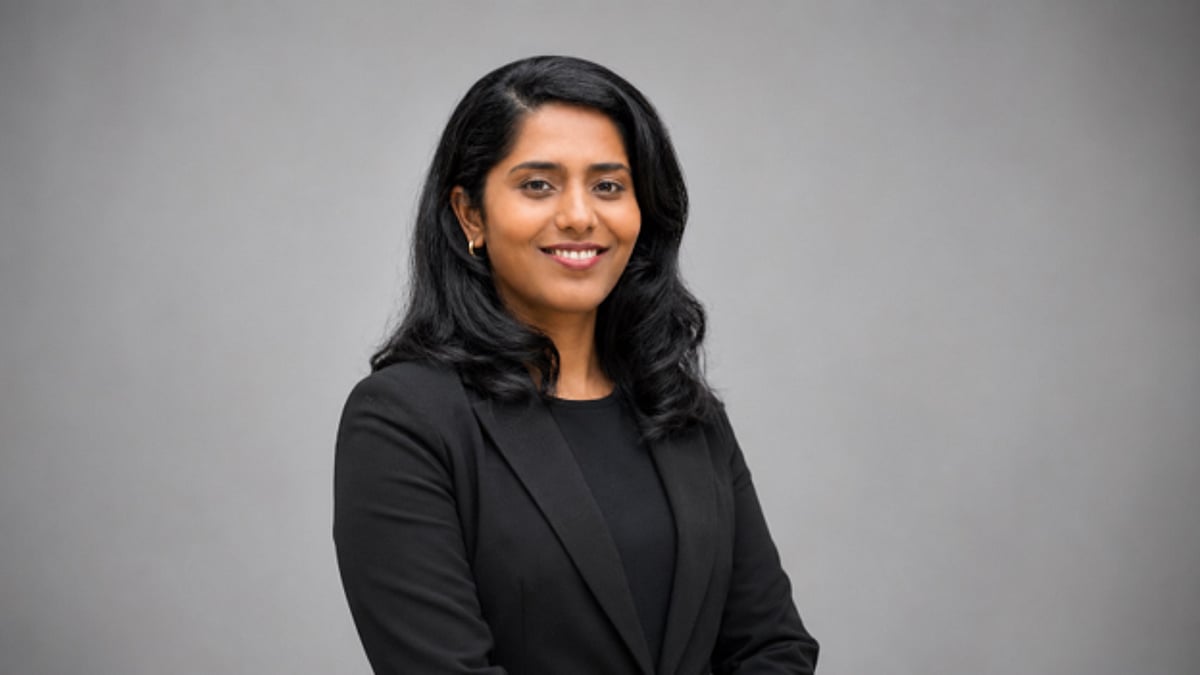
For most of her career, Jasvitha Buggana has operated in the blind spot of traditional monitoring. She has advocated that the true effort related to reliability is not detecting failures but identifying small deviations before they develop into full-blown issues.
Jasvitha Buggana is an engineer working at the intersection of operational systems and data analytics. She holds degrees in computer science from India and completed a master’s degree in business analytics in the United States. These two educational backgrounds influence how she interprets a failing system. Instead of asking if a given component is either up or down — purely through an infrastructure lens — she asks what a sequence of readings imply about customer experience, efficiency, and risk. In her opinion, anomaly detection is rapidly transforming from a technical capability into a strategic business discipline.
The types of problems that affect businesses most often do not declare themselves. Systems can appear healthy on the surface while problems develop underneath. Devices continue to send reports but the cadence of the message changes slightly. A data feed continues to flow but quality decreases in ways no individual alert was designed to identify. Identifying these problems requires analyzing weak signals embedded in extremely high volumes of data, and doing it effectively involves using technical analysis conjointly with understanding how a business operates.
One of the challenges associated with designing an effective analytical framework for anomaly detection is that each environment behaves differently. What would be considered normal for one distributed system could be indicative of a potential problem for another. Ms. Buggana develops analytical frameworks that distinguish ordinary operating behavior from actual departures from the norm. She is also transparent that this cannot be accomplished via a fixed rule book. To be effective, anomaly detection requires significant familiarity with both the data and the contextual information that generated it. An analytical framework that performs exceptionally well in one environment may perform poorly in another unless it has been fine-tuned to recognize routine behavior for that specific environment.
Some of the solution lies in improving observability. Improved observability enables teams to obtain a clear picture of how signals interact and influence one another, rather than being presented with a wall of isolated metrics. When teams can visualize how one degrading feed influences downstream slowdowns, they investigate faster and spend less time chasing root causes. Much of this load can be carried by automation. Automation continuously monitors, freeing human operators from eyeballing dashboards for subtle changes and presenting them only with patterns worth their attention.
Ms. Buggana cites confidence as the payoff. Many operations teams work within a reactive loop. Each fire breaker brings new challenges; each new challenge brings new fires to put out. Ms. Buggana’s work has focused on removing teams from this type of loop by applying analytical thinking to reliability issues so that emerging risks become visible early enough for action to take place. Ms. Buggana has provided bridge functionality between technical operations and analytics for large-scale initiatives related to operational data, system reliability, and performance optimization.
Ms. Buggana frames the impact less as fewer failures and more as greater confidence. When teams trust their data and can see risks forming, they make decisions from positions of strength rather than scrambling after the fact. Investigation time drops. Problems caused by poor data quality and disruptions caused by connectivity issues are identified earlier. Reporting becomes more reliable and the operation feels less fragile.
Ms. Buggana anticipates the tools will continue to improve. As machine learning advances, anomaly detection will provide more predictive capabilities, more context, and require less human intervention. However, Ms. Buggana is cautious not to hand over responsibility entirely to machines. She argues that the greatest value comes from pairing advanced analytics with human judgment, domain knowledge, and a culture that rewards taking action before disruption arrives.
Ms. Buggana’s larger bet is about where advantage will come from next year. “The organizations that are successful next year will not necessarily be those with the largest datasets,” she stated. “They will be those which can convert data into foresight.”