Category: AI Strategy

  • Google’s AI Leadership Reshuffle: Key Changes and Strategic Focus

    Google’s AI Leadership Reshuffle: Key Changes and Strategic Focus

    Google’s AI Leadership Reshuffle: Key Changes and Strategic Focus

    Google has recently undergone a significant overhaul of its artificial intelligence leadership structure, signaling a strategic pivot to accelerate innovation and sharpen its competitive edge in the rapidly evolving AI landscape. This restructuring aims to streamline decision-making, foster collaboration, and place AI at the core of the company’s future roadmap.

    Leadership Reshuffle and Centralized Teams

    In a move to break down silos and enhance coordination, Google has reorganized its AI leadership, assigning key executives broader responsibilities. The company has also centralized its major AI teams under a unified leadership framework. This consolidation is designed to improve collaboration on flagship AI products and reduce operational redundancies, enabling faster progress from research to deployment.

    Emphasis on Gemini AI Model

    Central to this strategic shift is a renewed focus on the Gemini AI model. The leadership changes place Gemini at the heart of Google’s product strategy, underscoring its importance as a foundational technology for future innovations. By prioritizing Gemini, Google aims to deliver more advanced and integrated AI capabilities across its ecosystem.

    Faster Product Delivery and Enhanced Competition

    The restructuring is intended to accelerate the entire AI lifecycle—from research and development to product release. This agility is crucial as Google contends with formidable rivals such as OpenAI, Microsoft, Anthropic, and Meta in the generative AI space. By streamlining operations, Google seeks to bring new AI features to market more efficiently and maintain its competitive stance.

    Expanded Executive Roles and Product Integration

    Senior AI leaders have been given expanded mandates, overseeing research, infrastructure, product integration, and commercialization under a more coordinated strategy. This holistic approach supports deeper integration of AI across Google’s diverse platforms, including Search, Workspace, Android, Cloud, and developer tools, ensuring that AI capabilities are woven seamlessly into user experiences.

    Infrastructure Investment and Long-Term Vision

    Underpinning these changes is a continued commitment to substantial investment in AI infrastructure, custom chips, and computing resources. This investment is critical for supporting larger, more capable AI models and services. The leadership overhaul reflects Google’s long-term vision of making AI the foundation of its products, services, and overall business growth strategy.

    In summary, Google’s AI leadership overhaul represents a decisive move to consolidate its position as a leader in artificial intelligence, focusing on centralized management, product-centric innovation, and robust infrastructure to drive future success.

  • India’s AI Ambitions Get a Boost: PM Modi Inaugurates Param Pragya Supercomputer at IIT Delhi

    India’s AI Ambitions Get a Boost: PM Modi Inaugurates Param Pragya Supercomputer at IIT Delhi

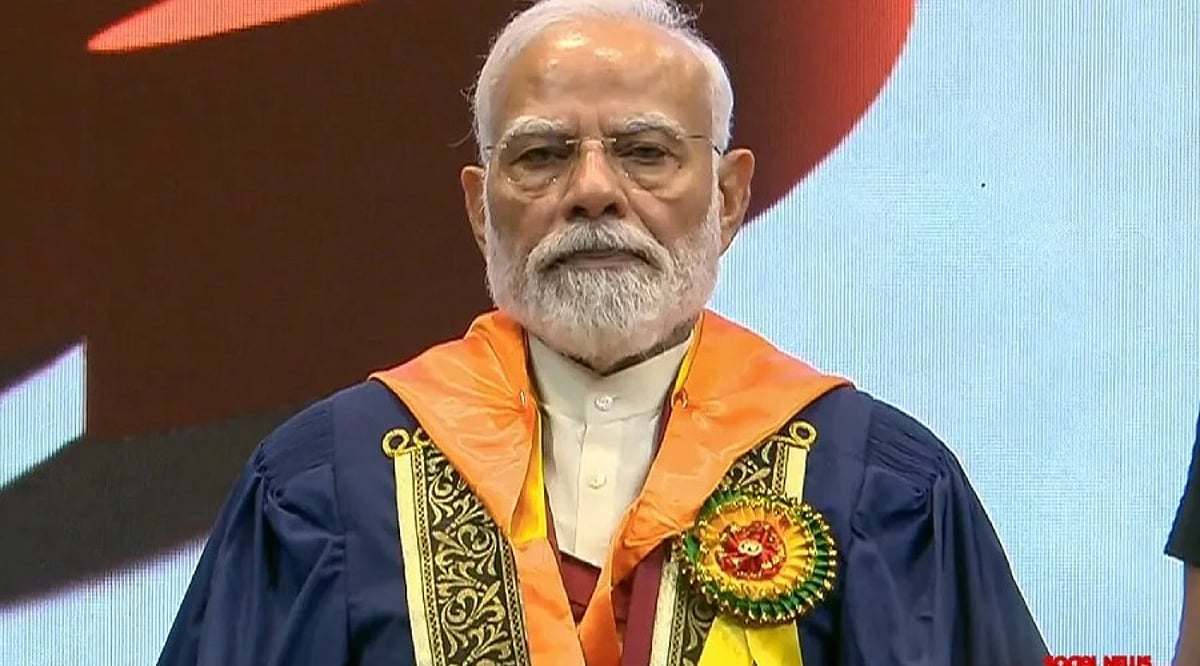
    Indian Prime Minister Narendra Modi inaugurated the ‘Param Pragya’ AI supercomputer at IIT Delhi during the institute’s 57th convocation ceremony, underscoring the government’s commitment to advancing national AI capabilities.

    The event, held at IIT Delhi’s Sonipat campus, saw PM Modi also present prestigious medals to graduating students, including the President’s Gold Medal and the Director’s Gold Medal. Harish Salve, Chairperson of IIT Delhi’s Board of Governors, and Institute Director Prof. Rangan Banerjee felicitated the Prime Minister and Union Minister Prahlad Joshi.

    PM Modi on Technology and Youth

    Addressing the graduating students, PM Modi described the convocation as marking the start of a new journey for the country’s talented youth. He noted that the world is advancing rapidly and technology is driving a shift in the global balance of power. “Unicorns, digital payments, and the fintech revolution have provided a platform for millions of the country’s youth to do something significant,” he said.

    Param Pragya: A Leap for AI Research

    The newly inaugurated Param Pragya facility is an AI-powered high-performance supercomputing center designed to strengthen IIT Delhi’s research in artificial intelligence, advanced computing, data science, and interdisciplinary fields. The launch comes at a time when AI and high-performance computing are becoming critical for innovation and technological development.

    Higher Education Expansion

    Union Minister Prahlad Joshi highlighted that enrollment in higher education has crossed 45 million students. Since 2014, the number of universities has increased by nearly 70 percent, with over 650 new universities, 14,000 new colleges, and 4,000 new Industrial Training Institutes established. He also noted that women now account for nearly 44 percent of enrollment in STEM disciplines, one of the highest proportions globally.

  • Rippling Unveils AI Spend Console to Tame Million-Dollar Token Costs

    Rippling Unveils AI Spend Console to Tame Million-Dollar Token Costs

    Rippling, the HR software company, has launched AI Spend Console after its internal AI token costs soared into the millions. The new tool provides granular visibility into AI spending by employee, team, and role, linking token usage to measurable work output such as code reviews and pull requests.

    The product emerged from a wake-up call in March when Rippling’s finance team discovered that AI tokens could consume 40% of its R&D headcount budget. Monthly spending had grown by 80%, pushing the projected annual cost to nearly 90% of that payroll budget. Chief Product Officer Matt MacInnis said executives were “incredulous” when they saw the figures.

    Upon investigation, Rippling found that 10–15% of workers accounted for about 60% of total AI spending. One engineer alone used $50,000 worth of AI tokens in a single month. Employees frequently selected expensive frontier models for routine tasks.

    Rather than cutting access, management initiated an urgent cost review. Rippling negotiated spending caps with providers including Cursor, OpenAI, and Anthropic, and built an AI gateway that routes each request to the most cost-effective model based on task complexity and cost.

    The changes reduced token spending from 40% of Rippling’s R&D headcount budget to about 15%. Usage remained near peak levels: 605 billion tokens in April and 600 billion in July, yet July’s bill was only 37% of April’s cost. CEO Parker Conrad noted that GLM 5.2 cost 85% less while delivering nearly comparable results for their tasks.

    AI Spend Console combines prompt volume, model costs, and work data in a single dashboard. For engineers, it compares spending with code output, pull requests, and review results. Managers can identify employees whose costly AI work frequently requires revision. Rippling also appointed “AI captains”—power users who help colleagues apply AI to suitable tasks.

    The console is included with Rippling’s HR subscriptions, though customers pay additional usage-based AI fees. It can also be purchased separately and connected to another HR system, tracking spending at individual, team, and role levels within the same workforce data structure.

  • Why Speed to Lead Is the Decisive Factor in B2B Sales Success

    Why Speed to Lead Is the Decisive Factor in B2B Sales Success

    The finish line is where most marketing campaigns falter. Modern sales setups excel at gathering data from website forms, but struggle to act on that information quickly enough. As a result, leads go cold and buyers move on to a competitor who simply answered first.

    Enter automation. Modern AI software can hook directly into your current database and turn those quiet customer records into immediate outreach the moment a form drops. By letting real-time voice AI handle the manual labor, businesses can reach out within the two-minute window where 90%+ of conversions happen.

    How the Automation Actually Works

    Most tools in this category can only do one of two things well: hold a conversation, or integrate with a calendar. Few do both at once, and fewer still do it across every channel a buyer might actually use.

    Multi-Channel Communication

    Rather than treating voice, SMS, email, and WhatsApp as separate systems that each require their own setup, advanced platforms run all four from a single context. A prospect who starts on WhatsApp and later calls in doesn’t have to repeat themselves; the system already has the thread. This matters more than it sounds: most inbound automation tools handle one channel well and treat the rest as an afterthought.

    Conversational Voice Engine

    The built-in voice agent departs from typical robodialers by actively listening, answering open-ended technical questions, and managing live inbound and outbound dialogue naturally. It also features an authentic, pleasant vocal tone—something that should not be overlooked.

    Live Booking Sync

    It interfaces directly with platforms like Calendly, Cal.com, or Chili Piper to evaluate real-time internal availability mid-conversation. That way, a confirmed calendar invitation drops straight into the client’s inbox the moment the call ends.

    Smart Multi-Language Support

    The system automatically identifies the origin location of incoming traffic to communicate natively, ensuring text or voice outreach sounds natural. Local idioms, appropriate regional greetings, and specific dialects adjust automatically.

    Built-in E-Commerce Hooks

    Outreach tools also link with Shopify and CheckoutChamp to track vital user milestones and events, enabling instant follow-ups on abandoned checkouts or post-purchase upsells. The system flags dropped carts within minutes to pitch tailored discounts before a shopper walks away entirely.

    The Actual Impact on Business Revenue

    According to the MarketsandMarkets AI SDR market report, the global market for these automation tools is projected to scale dramatically, rising from USD 4.12 billion in 2025 to USD 15.01 billion by 2030 at a compound annual growth rate of 29.5%. Inbound sales channels currently command the largest share, proving that modern enterprises are actively deploying automated infrastructure to stop high-volume digital traffic from bottlenecking in a stagnant inbox.

    Here’s how moving the early-stage follow-up grind to a background system fixes the everyday leaks that cost companies money:

    • Handle Sudden Lead Spikes: The system processes all inquiries with the exact same speed, keeping your queue clear during busy promotional weeks or major launch seasons.
    • Reach Buyers at the Right Moment: Response times drop to under two minutes, which blocks competitors from stepping in.
    • Save Employee Hours: Human sales teams stop losing hours to basic data collection and endless scheduling emails.
    • Protect Lost Sales: The software works as a 24/7 safety net, automatically reaching out to recover abandoned shopping carts, handle declined credit cards, or talk to users who want to cancel.
    • Keep Outreach Quality Steady: The system never gets tired or distracted. Every single inbound lead gets the exact same level of thorough research and persistent follow-up.

    Speed Is Everything

    AI software automation removes this specific delay by calling, texting, or emailing new contacts within those critical minutes to get a meeting on the calendar. And it is minutes we’re talking about here. Looking at 1.2 million sales leads across 40+ B2B and B2C companies, Harvard Business Review cites 60 minutes as the cutoff point: leads acted on within that time frame are 7x more likely to qualify.

    Manual workflows leave the door wide open for delayed responses and missed opportunities. A permanent background layer eliminates the inbox bottleneck, keeps data fluid, and ensures human closers spend their time strictly with serious buyers.

  • Why Background Removal and Upscaling Outperform Image Generation in Commercial Workflows

    Why Background Removal and Upscaling Outperform Image Generation in Commercial Workflows

    In most large-scale commercial workflows, the bulk of compute time is spent on unglamorous tasks: separating subjects from backgrounds, removing unwanted objects, upscaling low-resolution files, and compositing subjects into new scenes. These operations run millions of times daily behind product listings, marketplace tiles, and ad creative. They don’t make for flashy keynote slides, but they form the backbone of reliable image processing at scale.

    The Edge Case Is the Edge

    Cutting a subject from a photo sounds trivial until you hit the boundary. Alpha matting must decide not only which pixels belong to the subject, but what fraction of each boundary pixel belongs there. A pixel at the rim of a wine glass contains both glass and wall. The hardest categories are predictable: hair, fur, chain-link mesh, tulle, backlit subjects, transparent objects, motion blur, and items whose colors blend into the background. A model that handles a matte-finish shoe perfectly may fail on a tulle skirt, and a pipeline that assumes uniform quality across a catalog will ship those failures silently.

    Narrow Models Beat Broad Ones

    Task-specific models consistently outperform general-purpose ones in this domain, and the reason has nothing to do with parameter count. Ask a text-to-image system to remove a background, and it often re-renders the subject instead. The output looks plausible, but the product in that image is no longer the original product. Generative systems optimize for plausibility—an image that a human accepts as coherent. Commercial image editing demands fidelity: preserving every stitch, every specific shade, pixel for pixel, while everything around it changes. These are different objectives, and a model tuned for one is a liability at the other.

    The practical solution is an ensemble pipeline: a segmentation model produces the matte, an inpainting model handles removal, a super-resolution model handles upscaling, and the generative model is confined to the region where invention is actually desired.

    Measurement Is Thin in Image Pipelines

    Most teams running image operations at volume lack a proper evaluation set. They have a handful of test images chosen for their difficulty, plus a subjective sense that quality is acceptable. When a provider updates a model without announcement, they discover the change through customer complaints. The remedy is already prescribed by frameworks like the NIST AI Risk Management Framework (v1.0, January 2023): a frozen benchmark set that includes hard categories, a quality metric that correlates with human rejection, and a regression check that fires when a model version changes.

    The Consumer End Collapsed the Stack

    Platforms like Pixelcut combine matting, object removal, upscaling, and background removal into a single app. The same consolidation has happened across the consumer market; what used to require five separate tools and compositing knowledge is now a sequence of taps on a phone. But the abstraction hides important details: a user cannot tell whether a poor result came from matting failure, aggressive compression, or a request routed to a different model due to capacity constraints. That opacity is harmless for social media posts but consequential for merchants whose listing images constitute their entire sales pitch.

    Batch Is the Real Requirement

    Single-image quality is a showroom metric. Volume workflows care about throughput that holds across hundreds of images without per-item babysitting, deterministic output so reruns reproduce results, per-image failure handling to flag hard mattes rather than ship bad cutouts, and a stable version contract so catalog appearance doesn’t change overnight. The last property is the one most commonly discovered by accident.

    Fidelity, Plausibility, and the Returns Desk

    An edited product image functions as an advertising claim. Invented texture, nudged colors, or generated reflections that imply a finish the item doesn’t have each become a representation a customer can act on. Returns and chargebacks are where the cost eventually lands. Whether a model hallucinates detail is both a technical question and a compliance question.

    Where the Next Gains Come From

    Not from bigger models. The gains available in this layer are mostly systems work: routing each image to the cheapest model capable of handling it, caching aggressively because catalogs are repetitive, moving inference on-device where latency and unit cost matter more than peak quality, and attaching provenance metadata so downstream systems know what was altered and how. Provenance is shifting fastest from nice-to-have toward procurement requirement as platforms push disclosure obligations upstream.

    Why the Unfashionable Layer Wins

    The demo-friendly part of computer vision is generation, where competition is fiercest and differentiation shortest-lived. The durable positions are being built in the parts nobody screenshots: reliable mattes on difficult materials, batch behavior that surprises no one, and evaluation good enough to catch regressions before a customer does. Measurable, unglamorous, and considerably harder to copy than a prompt.

  • Suno’s New Copyright Measures: A Smart Move or Legal Damage Control?

    Suno’s New Copyright Measures: A Smart Move or Legal Damage Control?

    On August 6, 2026, Suno, the AI music generation platform valued at $5.4 billion following its June 2026 Series D, announced a set of new measures aimed at addressing copyright concerns. The company revealed plans to implement audio watermarking and fingerprinting technology, update its community guidelines, and introduce a new download policy to prevent the mass distribution of AI-generated songs on streaming services. This move comes as Suno faces multiple copyright lawsuits from major labels and artist bodies, including a recent ruling in Munich where the company was found liable for infringing German song copyrights.

    CEO Mikey Shulman outlined four operating principles in a blog post titled “How We’re Building the Future of Music Responsibly”: that great music is made by people, technology unlocks new creative possibilities, AI should encourage originality rather than imitation, and that more people making music should strengthen the wider ecosystem. The concrete changes include the rollout of watermarking and fingerprinting to identify Suno-generated tracks on streaming platforms, updated community guidelines with tiered enforcement (warnings, suspensions, bans, and referrals to authorities), and a download policy designed to prevent mass distribution of AI-generated songs on streaming services. The company also announced a partnership with lyrics provider Musixmatch to integrate its Sentinel copyright detection system.

    However, many questions remain unanswered. Suno has not confirmed which specific watermarking technology it will use, whether it will adopt an existing system like Google’s SynthID or build its own, and has not provided a specific rollout timeline beyond “coming weeks.” The company’s approach to transparency is also ambiguous: Shulman explained that the new tools give artists and platforms the choice to disclose AI origins but do not mandate it. Critics from the music industry note that these measures fail to address the core question of whether Suno’s training datasets included copyrighted material without authorization, which is the central allegation in the ongoing RIAA lawsuit.

    The situation has been further complicated by a hack of Suno’s source code in July, which reportedly revealed that the AI was trained by scraping music and lyrics from platforms such as YouTube Music and Genius. The music industry, including major labels like Sony and Universal, has been pursuing legal action against Suno for mass copyright infringement since 2024. Many experts believe that while Suno’s new transparency tools are a step in the right direction for industry cooperation, they are insufficient to satisfy the music industry’s demand for answers regarding training data.

  • SAP Halts Hiring and Travel as AI Costs Surge, Prioritizes AI Investments

    SAP Halts Hiring and Travel as AI Costs Surge, Prioritizes AI Investments

    SAP has paused most hiring and internal business travel worldwide as it grapples with rising costs associated with artificial intelligence. The German software giant implemented the measures in July 2026 to control spending while channeling funds into AI products, tools, and acquisitions. According to a current SAP employee cited by 404 Media, the restrictions remain in place.

    The hiring pause does not cover every role. SAP is focusing recruitment on selected positions that support the company’s long-term AI strategy. AI-related jobs, customer travel, development trips, and essential AI training are exempt from the freeze. Internal business travel has stopped under the new spending rules, but customer meetings and trips tied to SAP’s AI development program can continue.

    “Be disciplined in how we spend,” the company told employees, as rising AI costs put more pressure on budgets. SAP noted that AI adoption has increased token usage and related costs across its operations, with more AI services running at scale across the company.

    The company also plans major spending on AI products, internal AI use, and acquisitions involving data and artificial intelligence. A SAP spokesperson said the measures will help direct money toward areas with stronger long-term value, allowing the company to invest in AI while reducing spending in less critical areas.

    The move highlights a growing challenge for technology companies investing heavily in AI. While AI can improve productivity, running large AI systems can also create significant costs. SAP’s decision underscores a clear shift in priorities: AI skills and projects remain vital, while other hiring and spending now face tighter controls.

  • Alibaba to Monetize Next Open-Source AI Model with Revenue-Sharing for Enterprise Users

    Alibaba to Monetize Next Open-Source AI Model with Revenue-Sharing for Enterprise Users

    Alibaba is preparing to introduce a new monetization strategy for its next-generation open-source AI model, marking a significant shift in how Chinese technology firms are commercializing artificial intelligence. According to a Reuters report, the company plans to require large commercial users of its upcoming Qwen3.8-Max model to share a portion of the revenue generated from AI-powered services built using the technology.

    The move signals a departure from Alibaba’s previous approach, under which businesses could deploy its open-source models in their own data centers without paying licensing fees. Instead, enterprises generating more than $20 million annually from applications based on the new model will reportedly be required to enter revenue-sharing agreements with Alibaba.

    New Licensing Strategy Targets Enterprise Customers

    The announced licensing system is nearly identical to the commercial system that the Chinese AI company, Moonshot AI, uses for its Kimi K3 model. Although small firms and developers are expected to continue using the model without any fees, large companies that generate significant revenue through their AI products will have to pay Alibaba. This approach demonstrates a wider trend of how AI developers seek viable sources of income as the expense of training and implementing foundation models keeps growing.

    Open-Source AI Enters Monetization Phase

    Alibaba unveiled Qwen3.8-Max earlier this week, describing it as its most capable AI model to date. Built with 2.4 trillion parameters using a mixture-of-experts architecture, the model is designed to deliver high performance while reducing computing costs by activating only a fraction of its parameters during inference. Despite maintaining an open-weight approach, the company now appears focused on converting enterprise adoption into long-term revenue, similar to the ‘freemium’ strategies increasingly seen across the global AI industry.

    AI Race Drives New Business Models

    Alibaba’s decision comes amid intensifying competition with OpenAI, Anthropic and a growing number of Chinese AI developers, including DeepSeek and Moonshot AI. As companies invest billions of dollars in model development and cloud infrastructure, many are moving beyond free distribution toward commercial licensing, premium cloud services and revenue-sharing agreements. If implemented, Alibaba’s new policy could reshape how open-source AI is commercialized, allowing developers continued access while ensuring the company captures value from businesses building large-scale commercial products on its technology.

  • From Data to Decisions: Claight CEO Vishal Ranjan on Unlocking Actionable Business Insights

    From Data to Decisions: Claight CEO Vishal Ranjan on Unlocking Actionable Business Insights

    In a recent episode of the Analytics Insight Podcast, host Priya Diyalani sat down with Vishal Ranjan, Founder and CEO of Claight, to explore why so many organizations remain data-rich yet insight-poor despite massive investments in AI, analytics, and digital transformation. The conversation cut through the hype to reveal the critical differences between raw data, information, intelligence, and actionable insights—and why dashboards alone rarely drive business success.

    The Data Paradox

    “Organizations today generate more data than ever before,” Ranjan noted. “Dashboards, reports, KPIs, AI tools, and analytics platforms have become standard. Yet many business leaders still struggle to answer simple questions: Why did sales decline? Where are we losing revenue? What action should we take next?”

    This paradox—being data-rich but insight-poor—is at the heart of Claight’s mission. Ranjan, whose background is in sales at a large FMCG company, experienced the problem firsthand. “I had access to huge volumes of market research, customer surveys, demand forecasts, and sales reports. The problem wasn’t lack of data. The challenge was understanding what to actually do with that information,” he explained.

    Bridging the Gap Between Data and Action

    Claight was founded to bridge the gap between data, intelligence, and decision-making. “Everyone could see that a market was expected to grow by 30 or 40 percent, but very few people could translate that into clear business actions,” Ranjan said. “We wanted to help businesses move beyond reports and actually use data to drive growth.”

    He outlined a clear hierarchy: Data tells you what happened. Intelligence explains why it happened. Insights tell you what action to take next. “Unfortunately, many organizations stop at the dashboard. They invest heavily in analytics but never transform that information into practical business decisions. That’s why executives often rely on instinct instead of data when making important decisions.”

    Real-World Example: From Raw Data to Actionable Insight

    Ranjan illustrated the concept with a client case. “One of our clients had years of procurement and import-export data. That was raw data. Once we cleaned and organized it into trends, it became information. Next, we analyzed why certain countries had become major suppliers while others had become expensive due to policy changes. That became intelligence. Finally, we recommended alternative sourcing countries that could reduce procurement costs. That recommendation became an actionable insight because it directly influenced business decisions.”

    The biggest value, he emphasized, isn’t in owning data—it’s in knowing what action that data should drive.

    Why Data Silos Persist Despite Digital Transformation

    When asked why data silos still exist after years of digital transformation, Ranjan pointed to organizational behavior rather than technology. “Sales teams have their own dashboards. Finance has its own systems. Procurement works independently. Operations manage completely different datasets. Each department is optimizing for its own goals, so while every team has accurate information, nobody has a complete business picture.”

    He argued that digital transformation successfully digitized departments, but the next challenge is connecting those departments to create one unified source of truth. “That’s more of a cultural transformation than a technical one.”

    Three Barriers to Turning Data into Business Value

    Ranjan summarized the biggest barriers with three words: Trust, Context, and Speed.

    • Trust: If leaders don’t trust the numbers, they won’t use them. One conflicting report is often enough to make executives rely on intuition.
    • Context: A dashboard may show sales dropped by 10%, but it rarely explains why or what should happen next. Without context, numbers create more questions than answers.
    • Speed: Markets move fast. If analysis takes six weeks, the business environment may have already changed. Data must be timely enough to support decisions before opportunities disappear.

    Measuring Data Investments the Right Way

    Many organizations measure the wrong metrics, Ranjan cautioned. “They count dashboard logins, platform usage, reports generated, data stored. None of those prove business success.” Instead, companies should ask: Are we making decisions faster? Are our forecasts becoming more accurate? Are we responding to market changes quicker than before? Are we improving revenue, profitability, or customer satisfaction?

    “When data directly improves business outcomes, it stops being an IT expense. It becomes a strategic business asset,” he concluded.

    For the full discussion, including more insights on how to build a data-driven culture, listeners can access the complete episode of the Analytics Insight Podcast.

  • New Open-Source Tool Makes Enterprise LLM Decisions Verifiable — Kirill Pechurin’s structured-eval

    New Open-Source Tool Makes Enterprise LLM Decisions Verifiable — Kirill Pechurin’s structured-eval

    Gartner recently warned that ungoverned decisions using LLMs will cause financial or reputational loss for enterprises. The fix, Gartner said, is to redesign analytic workflows around a required evaluation stage — a step most AI pipelines skip. Another Gartner prediction estimates that by 2027, 40% of enterprises will demote or decommission autonomous AI agents, with governance gaps surfacing only after a production incident. Strip away the framing, and both predictions describe that AI systems are already making structured, machine-actionable decisions inside enterprises.

    Kirill Pechurin, a senior software engineer at Arctera, has built a way to check whether any of those decisions is correct — the kind of check a pipeline can run before the output reaches the system that acts on it. He built and open-sourced structured-eval, a free tool under the Apache-2.0 license, specifically designed to catch structured LLM outputs that parse correctly but contain wrong values. He also led the development of an LLM-based system for procurement, delivery, and equipment-accounting automation, including a spec-reconciliation tool that cut manual work by roughly 30% and exposed the problem this article addresses.

    Where Hallucination Benchmarks Stop Mattering

    Most conversations about AI reliability center on hallucination rates in open-domain question answering — a chatbot inventing a citation or a search summary getting a fact wrong. Those numbers have improved. But those benchmarks test a model on clean questions and expect an answer in plain sentences, not what most business systems actually ask. In production, a model’s output is often a structured record — a JSON entry written straight into a database, a compliance check, or a purchase order — without a human looking at it first.

    “A mistake doesn’t look like ‘the model said something false’ in a way a reader could notice anymore. It’s now one buried detail, nested deep inside an otherwise correct-looking record, that doesn’t match reality. No one skimming a chat transcript would catch it. But the system downstream will still act on it.” — Kirill Pechurin

    That’s a significant blind spot. A model can pass every open-domain hallucination benchmark and still ship a record with a wrong quantity, a fabricated part number, or fields that contradict each other. Nothing in the pipeline checks individual fields against a source of truth — only whether the output parsed as valid JSON.

    The Procurement Tool That Never Throws an Error

    Kirill ran into this gap in back-office automation at Arctera. His procurement tools included a component that automatically reconciled technical specifications against vendors’ commercial proposals, and another that parsed vendor-supplied equipment specifications into structured records. The system cut manual operations by roughly 30% in a high-frequency decision workflow. But that also matches the risk Gartner warns about: an LLM’s structured output feeding directly into a real business decision, with no human necessarily reading the raw model response before it’s acted on.

    “A reconciliation error doesn’t throw an exception. The tool just quietly matches a spec to the wrong vendor line, and by the time anyone notices, the equipment’s already been ordered.” — Kirill Pechurin

    In such workflows, asking whether the output looks plausible is the wrong question. Asking whether a specific field matches the source document is the right one — and almost nobody had built the tooling to ask it systematically.

    Grading Structured Output Like an Auditor

    Building the procurement system left Kirill with an unsolved problem: the evaluation layer was missing. He built one and released it under an Apache-2.0 license. The result, structured-eval, is a software tool specifically designed to assess the quality of structured JSON or YAML LLM outputs. Instead of stopping at whether the output parsed into valid JSON, it:

    • Compares values field by field at any level of nesting
    • Checks outputs against a source document to catch fabricated or unsupported values
    • Enforces logical consistency across fields through a rules layer built for the purpose
    • Supports running evaluations across a full dataset rather than one output at a time
    • Tests whether a model gives a stable answer when the same prompt is run repeatedly

    “Running the same prompt twice and getting two different structured outputs is routine. Most evaluation tooling doesn’t even ask that question.” — Kirill Pechurin

    The framework is designed to sit alongside existing LLM-evaluation tools such as deepeval and LangSmith instead of replacing them. Pechurin frames the underlying idea: “There’s no such thing as one hallucination score. A quantity field and a description field fail in completely different ways, so each field gets scored with whatever comparison actually fits it, then those get combined.”

    A quantity field might need exact or near-exact numeric matching; a description field might tolerate paraphrase and reward it with a token-level similarity score; a status field might need strict enumeration matching with zero tolerance. Letting each field carry its own comparison method, then combining those into a composite score, is much closer to how a human reviewer actually audits a structured record than a single blended accuracy number ever is.

    What the Fix Actually Buys You

    That kind of infrastructure is the practical answer to the industry pattern. It’s cheaper to build field-level verification into a pipeline once than to discover, after a procurement error or a compliance gap, that nobody was checking. Organizations less likely to face after-the-fact governance failures — decommissioning agents after the damage is already done — are those treating structured-output verification as a first-class engineering problem rather than an afterthought.

    This isn’t the first time reliability work of this kind produced a large, measurable result. Earlier in his career at Consul Group, Kirill redesigned how a 1-million-plus-document Elasticsearch index handled updates, cutting query latency from 5,000 milliseconds to 500 milliseconds — a tenfold improvement. It’s a different problem than structured-output verification, but the same idea: not to assume a system behaves correctly at scale, but to measure it and rebuild the part that doesn’t.

    An LLM can be reliable in general and still be the wrong tool for a procurement pipeline if nobody checks whether its specific fields match the specific documents it was given. Kirill Pechurin built structured-eval to close this gap, giving enterprises a concrete way to check AI-driven procurement, finance, and compliance decisions before they ship.