Tag: large language models

  • How to Optimize Prompts for Better, More Reliable LLM Output

    How to Optimize Prompts for Better, More Reliable LLM Output

    Large language models can produce impressive drafts, but the quality of the result depends heavily on the quality of the request. Prompt optimization is less about finding a magic phrase and more about removing ambiguity, giving the model the right boundaries, and refining the instruction until the output is useful.

    The techniques below can be used individually, but they work best together. They apply to content creation, research, coding, data processing, and any workflow where consistency matters.

    1. State the objective with precision

    Tell the model exactly what it should produce. Include the subject, format, tone, audience, and intended outcome. A vague request often leads to a broad response because the model has to fill in missing details.

    For example, instead of asking for an article about artificial intelligence, specify the length, structure, writing style, target reader, and any facts that must remain unchanged. Precise instructions reduce back-and-forth and make the first draft more usable.

    2. Supply relevant context without clutter

    Give the model enough background to understand the task. Useful context can include prior decisions, source material, definitions, examples, or specific requirements. For professional content, mention the audience and purpose.

    At the same time, avoid adding unrelated information. Too much context can make the prompt harder to follow and distract the model from the central task.

    3. Define constraints that shape the response

    Constraints make output easier to review and reuse. Specify word counts, formatting rules, the number of sections, writing style, prohibited elements, or information that should not change.

    For instance, asking for seven points with exactly 30 words each gives clearer boundaries than asking for seven important points. Consistent constraints also improve results when the same prompt is used repeatedly.

    4. Use examples to anchor style and structure

    When a desired style is hard to describe, show an example. A sample headline, paragraph, formatting pattern, or answer can help the model identify the pattern and apply it to new material.

    Examples are especially helpful for repetitive editorial, marketing, coding, and data-processing tasks where consistent output matters.

    5. Assign a role that fits the task

    Giving the model a relevant role can establish the perspective and expertise needed for an assignment. Instead of asking for a general analysis, you might ask it to act as a technology journalist, research assistant, editor, or coding reviewer.

    The role should directly relate to the task. Pair it with clear instructions about the expected output, audience, and limitations.

    6. Specify the output structure up front

    Tell the model how the final response should be organized before it starts generating. Tables, bullet points, headings, numbered sections, or predefined fields can make complex information easier to review.

    Structured output is particularly useful when content will be published, transferred into documents, compared across datasets, or processed by another system. A consistent format can also reduce editing time.

    7. Refine prompts through iteration

    A strong prompt does not always produce the ideal response on the first attempt. Review the output, identify what needs improvement, and adjust the instruction accordingly.

    You can ask the model to shorten sections, remove repetition, clarify explanations, or follow a specific structure. Iterative prompting turns the first response into a working draft rather than treating it as the final result.

    Putting the techniques into practice

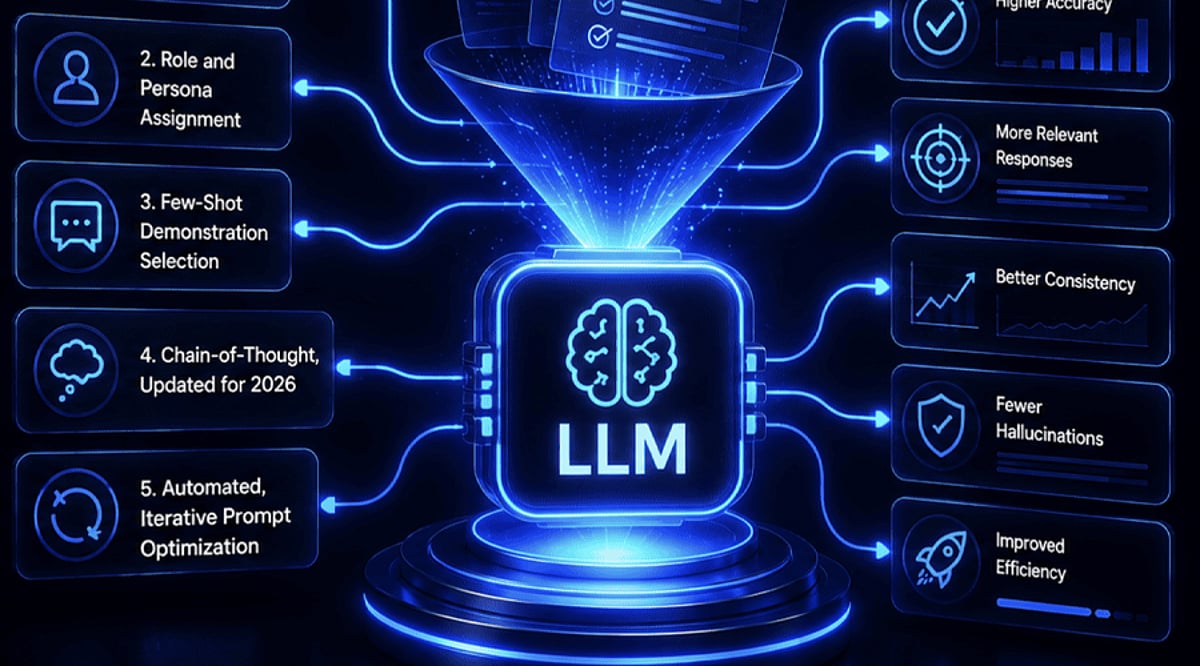
    Effective prompt optimization combines clear objectives, focused context, useful constraints, examples, roles, output structure, and iteration. Start with a precise request, review the result critically, and refine the prompt until the output meets the standard required for the task.
  • 2026 AI PC Hardware Guide: Memory, GPUs, and Storage for Local AI Models

    2026 AI PC Hardware Guide: Memory, GPUs, and Storage for Local AI Models

    Local AI in 2026: Hardware Essentials for Running Models On-Device

    Running AI models locally in 2026 hinges on more than just a capable processor. Memory, GPU power, bandwidth, and storage all play critical roles. Whether you’re using a standard laptop or a high-end workstation, understanding how these components scale with model size is key to making the right hardware choices.

    Memory: The Primary Constraint

    The amount of RAM and video memory (VRAM) directly determines which AI models your system can handle. For example, a 7-billion-parameter model at 4-bit precision requires roughly 4–5 GB for its weights. Larger models scale up quickly: a 14B model needs 8–10 GB, a 30B model needs 18–22 GB, and a 70B model demands 40–45 GB. For cutting-edge models like a 120B or 300B, you’re looking at 70–80 GB and 170–190 GB respectively.

    Beyond the model weights, your operating system, cache, and AI tools also consume memory. That’s why 32 GB is a sensible starting point for smaller models, but 64 GB or 128 GB offers far more headroom. High-end systems like AMD’s Ryzen AI Max PRO 400 series push the envelope with up to 192 GB of unified memory, enabling models over 300 billion parameters to run locally.

    GPU and Unified Memory: Boosting Performance

    For serious AI workloads, dedicated graphics hardware is non-negotiable. NVIDIA’s RTX PRO 6000 Blackwell Workstation Edition, with its 96 GB of GDDR7 memory and 1,792 GB/s bandwidth, is built for massive local models. Alternatively, NVIDIA’s RTX Spark takes a unified-memory approach, pairing a Grace CPU with a Blackwell GPU and up to 128 GB of shared memory, capable of handling inference, model development, and AI agent tasks.

    Apple’s 2026 Mac Studio follows a similar path. The M5 Max offers up to 128 GB of unified memory, while the M5 Ultra doubles that to 512 GB, making it a powerhouse for on-device large language models.

    Bandwidth and Storage: Often Overlooked

    Memory bandwidth is just as important as capacity. A system with 512 GB of memory but slow bandwidth will bottleneck large models. Apple’s M5 Ultra achieves 1.2 TB/s, while NVIDIA’s DGX Spark offers 273 GB/s with 128 GB of LPDDR5X memory. Always consider bandwidth when choosing hardware for AI.

    Storage is another critical factor. A 1 TB SSD is fine for a basic setup, but 2 TB is more practical if you plan to store multiple models. For serious development, 4 TB or more is recommended to accommodate model files, datasets, and checkpoints.

    Hardware Tiers by Use Case

    Entry-Level AI PC: 16–32 GB RAM, a 40+ TOPS NPU, and a 512 GB–1 TB SSD. Suitable for small language models, speech recognition, and basic image tasks.

    Mid-Range AI System: 32–64 GB memory and 8–16 GB GPU memory. Handles 7B, 8B, and 14B models comfortably, with room for some larger models.

    High-End AI Workstation: 64–128 GB memory and 24–32 GB GPU memory (or a large unified-memory design). Supports 30B and 70B models with ease.

    Enthusiast/Large-Model Rig: 128–512 GB memory. Systems like NVIDIA DGX Spark (128 GB, expandable to 700B parameters with four units) or Apple M5 Ultra (512 GB) are built for the most demanding local AI workloads.

    The Bottom Line

    The 2026 AI PC landscape is defined by a clear shift: while NPUs handle efficient local features, memory capacity is now the hard limit for model size. For most users, 64 GB is a strong practical target, while 128 GB offers ample headroom for future-proofing. If you’re serious about running large models locally, investing in high-bandwidth memory and a capable GPU is just as important as raw capacity.

    Frequently Asked Questions

    Q: How much RAM do I need for local AI in 2026?
    32 GB is sufficient for smaller models, but 64 GB is recommended for a more comfortable experience with demanding workloads.

    Q: Is an NPU enough for local AI?
    No. While a 40+ TOPS NPU is useful for specific features, larger models depend far more on memory capacity, GPU power, and bandwidth.

    Q: Can I run a 70B model on a PC?
    Yes, but it requires roughly 40–45 GB just for the weights. A system with 64 GB or more memory is strongly advised.

    Q: Is 128 GB RAM better than a powerful GPU?
    It depends. More memory lets you fit larger models, but GPU memory and bandwidth heavily influence inference speed. Both are important.

    Q: How much storage should I allocate?
    1 TB is a start, but 2 TB is more practical for multiple models. For serious development, 4 TB or more ensures you won’t run out of space.

  • Stanford Online’s Applied Enterprise AI Course: Strategies for Real-World Impact at Scale

    Stanford Online’s Applied Enterprise AI Course: Strategies for Real-World Impact at Scale

    Course Overview

    Stanford University’s Continuing Studies program offers Applied Enterprise AI: Making An Impact At Scale, an online course designed for professionals seeking practical AI deployment knowledge. The curriculum emphasizes scaling AI initiatives, aligning them with corporate objectives, and governing production-grade AI solutions—all without requiring deep coding skills. Real-world enterprise case studies provide actionable insights into current AI technologies and organizational change management.

    What You’ll Learn

    • Enterprise AI strategies for scalable business transformation
    • Large Language Models (LLMs) and their enterprise applications
    • Multi-Agent Systems for intelligent workflow automation
    • Vector databases and the Model Context Protocol fundamentals
    • AI governance, ethical deployment, and human-in-the-loop design

    Accessibility and Value

    Fully online and globally accessible, this course focuses on implementation strategies rather than programming. Learners explore practical business cases—such as customer service and sales forecasting—to understand how enterprises adopt and govern AI effectively.

    Comprehensive Curriculum

    • Enterprise AI: Strategies for identifying, evaluating, and scaling AI initiatives
    • Large Language Models: Enterprise use cases for modern generative AI technologies
    • Multi-Agent Systems: Collaborative AI systems designed for business automation
    • AI Governance: Responsible AI deployment, risk management, and ethical decision-making
    • Enterprise Transformation: Organizational change, workforce evolution, and AI adoption at scale

    Eligibility Criteria

    Ideal for business professionals, tech professionals, decision-makers, and anyone involved in AI implementation. No programming background is required.

    What Makes This Program Stand Out

    Rather than focusing on software engineering, the course emphasizes practical enterprise adoption—guiding learners through AI pilots, projects, and the transition from experimentation to production. Topics include LLMs, Multi-Agent Systems, vector databases, and the Model Context Protocol, all illustrated through business cases related to AI governance and implementation.

    Final Thoughts

    Stanford Online’s Applied Enterprise AI: Driving Real-World Impact at Scale provides a solid foundation for professionals aiming to master enterprise AI implementation. With a focus on large language models, multi-agent systems, and business transformation, participants gain the strategic knowledge needed to drive successful AI deployments.

  • Harvard Business School Online: Data Science and AI for Strategic Decision Making

    Harvard Business School Online: Data Science and AI for Strategic Decision Making

    Harvard Business School Online has launched a self-paced course designed for business professionals who want to leverage data science, artificial intelligence, and analytics to make evidence-based decisions. Participants gain hands-on experience with AI tools, large language models (LLMs), and data modeling to translate insights into strategic business outcomes.

    What You’ll Learn in This Course

    This course enables learners to:

    • Build a business-focused understanding of data science, machine learning, and generative AI.
    • Understand generative AI systems, large language models (LLMs), and prompt engineering to apply them responsibly.
    • Use LLM-powered analytical tools like Julius to explore, build, and validate data models.
    • Apply unsupervised and supervised learning techniques for pattern recognition, segmentation, and forecasting.
    • Translate data analysis into actionable strategic business decisions and design evidence-based experiments.

    Accessibility and Value

    The self-paced online course requires 20 to 30 hours of study time, allowing students to choose their own schedule. For a fee of $1,850, participants receive both a Certificate of Completion and access to practical business-oriented AI training. The course teaches essential skills through a combination of real-world AI applications, data science methodology, and decision-making strategies.

    Comprehensive Curriculum

    • Foundations of Data Science: The scientific principles of data science establish fundamental concepts that serve as the foundation for analytical methods and data modeling techniques.
    • AI and Machine Learning in Business: The field of AI and machine learning research develops applications for business use through generative AI technology and LLM systems.
    • Experimentation and Strategy: Business experiments require design through experimentation, and companies should base their decisions on collected evidence.
    • Data Modeling Tools: The LLM-based platform Julius provides analytical capabilities and validation functions for data modeling.
    • Applied Business Projects: The applied business projects program requires students to work on practical tasks that demonstrate how AI knowledge can be used to make important business decisions.

    Eligibility Criteria

    • Intermediate-level understanding of business, data analysis, or statistics.
    • Basic familiarity with data-driven decision-making and technology tools.

    What Makes This Course Stand Out?

    Harvard Business School Online offers a distinct educational experience that integrates practical AI and data science applications into business strategy development. The program provides students with practical training in generative AI, LLMs, and analytical tools, enabling them to transform data insights into business solutions. The program uses real projects to help students learn practical skills they can immediately use in their work.

    Final Thoughts

    The course teaches professionals how to use data science and AI for their business decision-making processes. Participants learn to develop real-world skills in analytics, experimentation, and evidence-based strategy through their work with AI tools, data modeling, and business applications.

  • Indian Startup Sarvam AI Builds 1-Trillion-Parameter Model to Compete Globally

    Indian Startup Sarvam AI Builds 1-Trillion-Parameter Model to Compete Globally

    Bengaluru-based artificial intelligence startup Sarvam AI is making a bold bet on a massive 1-trillion-parameter foundation model, signaling its ambition to compete with global AI leaders. The announcement came during the company’s Epoch 2026 event, where co-founder Pratyush Kumar outlined the model’s focus on coding, cybersecurity, scientific research, and simulation workloads.

    Developed from scratch, the model aims to enable developers and enterprises to build AI solutions tailored specifically for Indian languages and use cases. At the same event, Sarvam AI revealed pricing for its earlier Sarvam 105B model: $0.80 per one million blended tokens—significantly cheaper than comparable global large language models (LLMs).

    To bolster its efforts, the startup announced partnerships with three Indian Institutes of Technology (IITs) and two state governments for pilot projects in education and public service delivery. Additionally, the company has brought on board Devendra Singh Chaplot, a former xAI researcher, as a part-time advisor. Chaplot previously contributed to founding teams at Mistral AI and Mira Murati’s Thinking Machines Lab.

    However, industry observers question whether building ever-larger models remains the right strategy. The AI landscape has shifted toward efficiency, with many companies adopting architectures like Mixture-of-Experts (MoE) to deliver strong performance with lower computational costs. A large model alone will not guarantee success—Sarvam must also develop practical tools that solve real-world problems for users and businesses.

    While hiring a former xAI researcher and launching the 1-trillion-parameter project are significant steps, the startup’s biggest challenge will be turning these ambitious ideas into trusted, everyday products.

  • Deploy Your Own AI Agents on a VPS: A Step-by-Step Guide Using Ollama and OpenClaw

    Deploy Your Own AI Agents on a VPS: A Step-by-Step Guide Using Ollama and OpenClaw

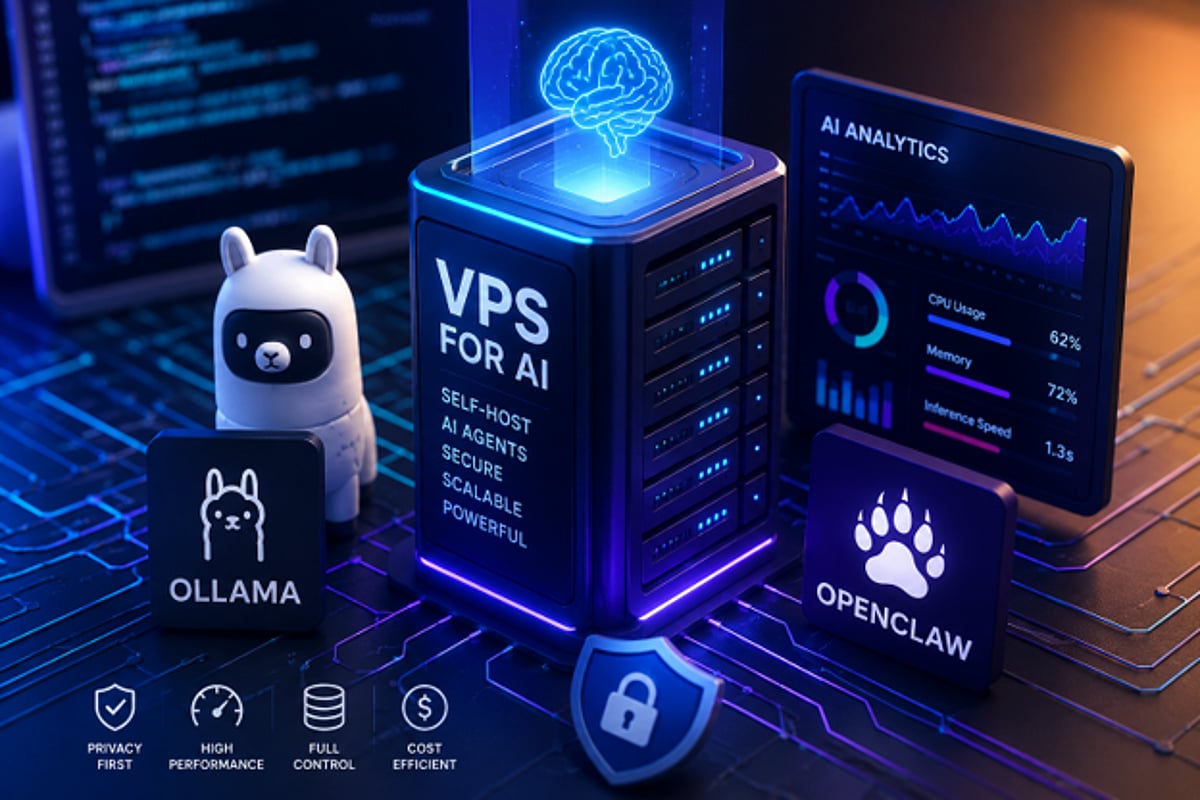
    As artificial intelligence continues to evolve, concerns around privacy, performance limitations, and recurring subscription fees have driven many developers and businesses to seek alternatives. Self-hosting AI agents on a virtual private server (VPS) offers greater control over data and infrastructure compared to cloud-based AI services. Tools like Ollama and OpenClaw make it possible to run AI workloads in a flexible, scalable manner directly on your own VPS.

    By using a VPS for AI, developers, researchers, and companies can create a dedicated environment to test, automate, analyze, and generate AI workflows without relying on third-party cloud providers. This approach ensures data sovereignty, customizable configurations, and predictable resource availability.

    Why Choose Self-Hosted AI Agents?

    AI agents can handle tasks such as automation, internal process management, and private data analysis. Hosting your own AI agents on a VPS puts you in full control of your data, system configuration, and security policies. Unlike public AI services, self-hosting allows you to tailor how your agent operates, manage resources efficiently, and reduce dependency on external platforms.

    With a dedicated VPS, you also avoid resource contention. CPU, RAM, and disk space are consistently available for your AI applications, leading to predictable performance—critical for production environments.

    Understanding Ollama and OpenClaw

    Ollama simplifies deploying and managing large language models (LLMs). You can set up AI models on your local machine or VPS with just a few commands. It provides a command-line interface for downloading, launching, and interacting with AI models.

    OpenClaw works alongside Ollama as an open-source platform for building and operating AI agents. These agents can generate content, conduct research, automate tasks, and analyze data. Together, Ollama and OpenClaw form an ideal toolkit for creating personalized, locally-hosted AI solutions.

    Choosing the Right VPS

    AI workloads are more resource-intensive than typical web applications. Before installing Ollama and OpenClaw, evaluate your VPS hardware based on the model size and expected demand. Key considerations include:

    • Memory (RAM): The most critical resource; larger models require more RAM.
    • CPU cores: More cores improve processing speed, especially for concurrent tasks.
    • GPU: Optional but beneficial for heavy LLM workloads.
    • Storage speed: High-speed SSD storage significantly reduces model load times.

    Many users start with a low-cost VPS for testing, but scale up resources as needs grow.

    Setting Up Ollama and OpenClaw on Your VPS

    The installation process is straightforward:

    1. Create a Linux VPS and connect via SSH or console.
    2. Update all software packages on the system.
    3. Install Ollama following the official installation guide. Download the models you need from Ollama’s model repository and import them.
    4. Install OpenClaw and configure it to use Ollama’s APIs. OpenClaw enables your AI agent to perform tasks locally through the VPS.
    5. Both applications run on their own server, allowing you to control security settings and access permissions for each model independently.

    Analytics and Performance Benefits

    Self-hosted environments provide full visibility into AI performance metrics, including CPU usage, memory consumption, response times, and workload trends in real time. Administrators can use these insights to optimize infrastructure costs and ensure reliable operation. Performance data helps identify resource-intensive processes and potential bottlenecks—insights that are often unavailable in fully managed AI services.

    Privacy Advantages of Self-Hosted AI

    Running Ollama and OpenClaw on your own VPS gives you unmatched control over AI infrastructure, data privacy, and flexibility. This approach is ideal for internal automation services, language model testing, and AI workload analysis. As interest in AI grows, self-hosted solutions offer a path for those who want full ownership of their data, compute environment, and future AI strategy.

  • Andrej Karpathy: Speak Naturally, Not Perfectly — Why Casual Voice Prompts Outperform Polished AI Instructions

    Andrej Karpathy: Speak Naturally, Not Perfectly — Why Casual Voice Prompts Outperform Polished AI Instructions

    Artificial intelligence researcher Andrej Karpathy, the mind behind the term “vibe coding,” is challenging the common obsession with crafting the perfect AI prompt. Instead, he advocates for a more natural approach: simply say what you want, even if your thoughts are messy or incomplete.

    In a post on X on July 21, 2026, Karpathy explained his preference for using voice mode when interacting with large language models (LLMs). Rather than typing carefully refined instructions, he speaks freely, allowing the AI to organize his scattered ideas into a coherent response. He often tells the chatbot upfront that his thoughts may be messy or contain mistakes, so the model focuses on intent rather than literal interpretation.

    “One pattern I find useful for working with LLMs is a nice long ramble session. Sometimes the LLM needs more bits to understand what you’re trying to achieve, but you’re too lazy to type them. In these cases I like to lean back, switch to voice and just ramble.”

    Karpathy argues that many users provide too little context. He believes longer, more natural instructions give the AI a better chance to grasp the real objective than short, polished prompts. His comments come amid growing investment by AI companies in voice-driven assistants designed to facilitate more fluid conversations.

    Karpathy coined the term “vibe coding” in early 2025, referring to a coding method where developers use natural language prompts to generate code via AI instead of writing every line manually. His latest message reinforces that philosophy: forget about perfect prompts, focus on clear communication.

  • OpenAI Dominates in Users, but Anthropic Surpasses in Enterprise Revenue Growth, IDC Data Shows

    OpenAI Dominates in Users, but Anthropic Surpasses in Enterprise Revenue Growth, IDC Data Shows

    OpenAI’s ChatGPT remains the world’s most widely used artificial intelligence chatbot by user numbers. However, new estimates from IDC suggest Anthropic may generate more annual revenue despite serving a much smaller audience. The findings highlight contrasting business models within the fast-growing AI industry.

    ChatGPT Maintains Largest Global User Base

    IDC Research Vice President Arnal Dayaratna estimated that ChatGPT has more than 900 million weekly active users worldwide, placing OpenAI well ahead of other consumer AI chatbot providers. IDC also estimated that Google Gemini serves between 200 million and 250 million weekly active users, while Anthropic’s Claude has between 40 million and 60 million weekly active users. These figures show that OpenAI remains the largest consumer-facing AI platform by a wide margin.

    Dayaratna noted that OpenAI has built multiple revenue streams across consumer subscriptions, workplace seats, APIs, and platform services. IDC estimates OpenAI generates between $30 billion and $40 billion in annualized revenue, with consumer subscriptions accounting for about $10 billion to $13 billion, and API and platform services contributing as much as $20 billion. Reports published earlier this month also stated that OpenAI generated $5.7 billion in revenue during the first quarter of 2026 while spending about $3.7 billion, with a net loss reaching approximately $39 billion in 2025.

    Anthropic Builds Revenue Through Enterprise Customers

    Although Anthropic serves far fewer users, IDC estimates its annualized revenue stands between $40 billion and $50 billion. Consumer subscriptions contribute less than $2 billion, according to the research firm. Most of Anthropic’s revenue comes from enterprise subscriptions, Claude Code seats, API usage, and other developer-focused workloads. This business mix differs significantly from OpenAI’s larger consumer-focused platform.

    Dayaratna commented, “Usage scale tells a different story from revenue mix,” adding that Claude’s business is more focused on enterprise and developer customers than consumer adoption. Anthropic also referenced its May 2026 company blog, which announced its annualized revenue run rate exceeded $47 billion, supporting IDC’s broader revenue estimates.

    Research Firms Report Different Strengths for Both Companies

    Counterpoint Research reported similar findings in its April 2026 analysis, estimating Anthropic captured 31.4% of global large language model revenue during the first quarter of 2026, with OpenAI following at an estimated 29% market share. Counterpoint also estimated Anthropic generated average monthly revenue of $33.30 per user, compared to OpenAI’s $2.20 per user. During the same period, Counterpoint estimated OpenAI had approximately 900 million monthly active users versus about 65 million for Anthropic.

    Both OpenAI and Anthropic have reportedly started confidential preparations for possible future public offerings. In May, Anthropic completed a $65 billion Series H funding round that valued the company at $965 billion. The latest estimates present two different measures of success in the AI industry: OpenAI continues to lead by user reach, while IDC estimates suggest Anthropic currently earns more revenue through enterprise customers and developer services. As Dayaratna summarized, “Usage scale tells a different story from revenue mix,” reflecting the divergent strategies followed by both companies.

  • xAI Launches Grok 4.5 Beta: Musk Claims It Outperforms Anthropic’s Claude Opus

    xAI Launches Grok 4.5 Beta: Musk Claims It Outperforms Anthropic’s Claude Opus

    Elon Musk’s artificial intelligence company, xAI, has introduced Grok 4.5 in private beta, marking the latest update to its flagship chatbot. The company claims the new model delivers stronger performance than rival AI systems, including Anthropic’s Claude Opus, across several benchmarks.

    The release comes as AI companies continue to roll out increasingly capable models, with firms racing to improve reasoning, coding, and conversational abilities while attracting enterprise customers.

    Grok 4.5 Enters Limited Testing

    According to xAI, Grok 4.5 is currently available only to a select group of testers. The company said the private beta will help evaluate the model’s performance before a wider rollout. Musk described the model as the company’s most advanced AI system so far, saying it offers improvements in reasoning, factual accuracy, and response quality. He also claimed the latest version performs better than competing frontier models in several evaluation tests. However, xAI has not released detailed benchmark data or independent validation to support all of its performance claims.

    Competition in AI Heats Up

    The launch adds yet another chapter to the fast-moving AI race, where companies like OpenAI, Anthropic, Google, and Meta keep releasing new models at a rapid pace. Over the past few months, developers have been fixated on sharpening coding help, multimodal skills, extended-context reasoning, and enterprise setups. Performance comparisons have become a major marketing focus, with AI firms regularly releasing benchmark results to show they are improving faster than others.

    Analysts point out that even if benchmark scores provide a way to judge progress, real-life results often hinge on how well models actually handle everyday business and consumer tasks.

    xAI Expands Its AI Ambition

    Since developing Grok, xAI has been increasing the bot’s functionality on the X platform while making substantial investments in computational technology and large language models. xAI presents Grok as a competing solution to current AI assistants for its real-time information provision and better conversational capabilities. The new release of Grok 4.5 shows that xAI continues competing with other AI firms as the demand for advanced generative AI solutions grows rapidly.

    The wider launch is expected after testing is complete and feedback from beta users is received. xAI has provided no official timeline; however, the update reveals that competition among top AI firms is not weakening.

  • Understanding Claude AI Tokens: Context Windows and Token Limits Explained

    Understanding Claude AI Tokens: Context Windows and Token Limits Explained

    Artificial intelligence models like Claude rely on tokens to process text, understand questions, retain context, and generate responses. Tokens and context windows are fundamental to how the system operates. With recent upgrades, Claude now supports up to 1 million tokens in a single context window, enabling larger tasks and improved performance.

    What Are Tokens in Claude AI?

    Tokens are small units of text that an AI model reads instead of processing full sentences as humans do. A token can be a complete word, part of a word, a punctuation mark, or even a space. For example, the phrase “Artificial Intelligence” may use two to four tokens depending on how the system splits the text. Generally, 1,000 tokens equal about 750 English words.

    Every Claude interaction uses tokens in two ways: input tokens (the text you provide) and output tokens (the AI’s response). Both count toward the total token limit. Every question, document, command, and response consumes part of this capacity.

    What Is a Context Window?

    A context window is the amount of information Claude can keep in memory at one time. It functions like temporary memory that helps the AI understand everything within a conversation. The context window includes the prompt, earlier messages, uploaded files, instructions, and previous responses. Claude reviews all this information before generating an answer.

    If a conversation becomes too long and the token limit is reached, older information begins to drop from memory, which can reduce answer quality. Older Claude models had a context window of 200,000 tokens—already much larger than many competing systems.

    Latest Claude Token Limits in 2026

    Anthropic made significant improvements to Claude in 2026, pushing token capacity much further. The latest models now support around 1 million tokens in a single context window:

    • Claude Sonnet 4.6 handles 1,000,000 tokens.
    • Claude Opus 4.6 also supports 1,000,000 tokens.
    • Claude Opus 4.8 expands further with dynamic workflow systems for even larger and more flexible processing.

    A 1 million token context window equals roughly 700,000 to 750,000 words—enough to process several books, analyze huge research documents, or examine large software codebases in one session. Few commercial AI systems currently offer memory at this scale.

    Why Token Limits Matter

    Larger context windows allow longer conversations without losing details, which is crucial for maintaining instructions across multiple messages. They also simplify document analysis: long contracts, reports, research papers, and technical documents stay in memory instead of being broken into smaller parts. Software developers benefit because Claude can review entire code repositories at once, detecting errors and improving code structure. More context also reduces incorrect answers, as Claude can check more details before responding.

    Extra Usage Limits in Claude

    Large context windows do not mean unlimited access. Anthropic imposes additional compute controls for heavy workloads. Current systems use a 5-hour rolling usage window to limit activity within a short period. Weekly compute limits also exist for frequent large-task users. Each session tracks token usage separately, and API users who exceed normal limits may face additional pay-as-you-go billing. These measures prevent overload while keeping performance stable.

    New Claude Efficiency Updates

    In May 2026, Claude Opus 4.8 introduced customizable effort levels. Simple tasks can use fewer reasoning tokens, while complex tasks can draw more processing power as needed. This improves cost control and efficiency. Another major update is Dynamic Workflows, which allows Claude to split large tasks across multiple AI sub-agents within one session, making complex tasks faster and token usage more organized.

    Future of Large Context AI Models

    Context window size is becoming a key area of AI development. Claude’s move to 1 million tokens shows the direction of the industry—toward long memory, large document understanding, complete software analysis, and advanced multi-step task execution. As models grow more powerful, token efficiency will become as important as intelligence itself. Claude’s token architecture demonstrates how modern AI relies on smart memory management and efficient token usage.