Author: vitorcherulli

  • Why Agile Testing Quadrants Need a Third Axis for AI-Generated Tests

    Why Agile Testing Quadrants Need a Third Axis for AI-Generated Tests

    The classic Agile Testing Quadrants model, introduced by Brian Marick and later refined by Lisa Crispin and Janet Gregory, has served the software testing community for over two decades. It organizes tests along two axes: business-facing versus technology-facing, and tests that support the team versus tests that critique the product. This framework has aged well because it focuses on why a test is run rather than what tool executes it. However, the model was built on a critical assumption: that a human wrote the test, understood its purpose, and could explain why it exists. In today’s AI-native development pipelines, that assumption no longer holds for a significant portion of tests.

    The Missing Dimension: Test Provenance

    When a feature is scaffolded by an AI coding assistant, tested by an AI test generator, and merged after a quick skim review, the resulting test suite may pass hundreds of tests—yet no one on the team can articulate what many of them actually assert. The quadrants treat all tests within a given quadrant identically, but the trustworthiness of those tests varies dramatically. A Q1 unit test written by a senior engineer after a production incident is fundamentally different from a Q1 unit test generated by a large language model from a docstring and approved without meaningful review.

    According to a survey by quality assurance practitioners, 65% of development teams actively use AI to generate code, and 16% do so occasionally. Respondents rated their trust in AI-generated code at 3.16 out of 5, and 58% reported that their testing workload has grown as a direct result. The gap between adoption and trust is exactly what the original quadrants were never designed to express.

    Introducing a Third Axis: Provenance

    A natural evolution of the model is to add a third dimension: provenance. This axis captures where a test originated and how much unsupervised trust it carries. Rather than adding another box to the existing grid, think of it as a Z-axis that transforms the flat model into a cube. Every quadrant can now be evaluated through an additional trust dimension based on three states of test provenance:

    • Human-authored and reviewed: The traditional case the original model assumed.
    • AI-authored, human-verified: A developer or tester used an AI test generator, reviewed the output, and signed off before merging.
    • AI-authored, unverified: The test passed continuous integration (CI), but no one meaningfully reviewed its assertion logic.

    The third bucket is where flaky test root-cause analysis becomes expensive. A Q4 performance test scaffolded by an autonomous agent against staging, with load parameters never validated against real production traffic, is no longer a technology-facing test in the way Marick intended—it’s an unverified hypothesis wearing the shape of a test.

    Why Provenance Changes Coverage Metrics

    Coverage percentage has always been a blunt instrument, but it becomes actively misleading when test authorship is mixed. A suite reporting 85% coverage tells you nothing about whether that coverage reflects deliberate risk-based testing or an AI test generator filling gaps to satisfy a coverage gate.

    Consider a payments team that asks an AI test generator to bring a checkout module from 60% to 85% coverage before a release freeze. The tool delivers, every new branch has a corresponding test, the build goes green, and the coverage dashboard reports success. Three weeks later, a currency-rounding edge case reaches production because eleven of those new tests asserted that a function returned a value—not that the value was correct. Coverage went up; risk did not go down. The dashboard never had a field for “asserted with intent” versus “present to satisfy a gate.”

    Mean time to detect (MTTD) suffers the same distortion. An AI-authored test that passes without asserting anything meaningful doesn’t reduce MTTD; it merely delays discovery until a customer reports the issue.

    Applying the Updated Model Today

    You don’t need to rebuild your test management tooling to start using this extension. Three practical moves deliver most of the value:

    1. Tag provenance, not just category. Add a field in your test management system for authorship: human, AI-generated-verified, or AI-generated-unverified. This alone surfaces where actual risk is concentrated, quadrant by quadrant.
    2. Route unverified AI tests through a human-facing quadrant. A Q1 unit test that no human has verified behaves, from a trust standpoint, more like an unreviewed Q3 exploratory finding than a reliable technology-facing check. Treat it accordingly until someone signs off.
    3. Build verification into the pipeline, not just generation. Generating tests faster without a matching investment in verification simply moves the bottleneck downstream. Self-healing automation can reduce maintenance burden, but maintenance and verification are different challenges—solving only one still leaves the trust gap open.

    The Final Argument

    The four quadrants still answer why a test exists. The missing question in an AI-native pipeline is whether that test deserves trust. Adding provenance does not replace the Agile Testing Quadrants; it extends the model for a world where humans and AI systems increasingly collaborate to build, test, and maintain software. By acknowledging the provenance of each test, teams can make smarter decisions about where to invest verification effort and how to interpret coverage and quality metrics.
  • Why AI Coding Assistants Aren’t Speeding Up Mobile Projects (and What Will)

    Why AI Coding Assistants Aren’t Speeding Up Mobile Projects (and What Will)

    Ask a mobile team how much of their code an assistant drafts today, and the honest answer is a large share of it. Ask whether the last project shipped in half the time, and the tone changes. Both things are true at once: code appears faster than ever, but delivery dates have barely moved. That gap is not a failure of the tools, nor a reason to ignore them. It is a signal that typing was never the constraint.

    Writing Code Was Never the Bottleneck

    Break a mobile project into where the calendar actually goes, and code generation turns out to be a modest slice. There is deciding what to build, design iterations, integration with external systems, testing across a device matrix, the store submission cycle, and review—which has quietly become the busiest station on the line. Speeding up one step only shortens the chain if that step was the bottleneck. Generation was not. The saving is real but small, and it pushes the pressure elsewhere.

    The Bottleneck Moved to Review

    Reading code you did not write is slower than reading code you did. An assistant can produce a plausible 300-line change in the time it takes to describe the requirement. Understanding that change well enough to approve it takes what it always has. Output rose; review capacity did not. Pull requests get bigger, review gets shallower, and defects surface later, when they are more expensive. Teams that get real value impose three rules: keep diffs small, require an author who can explain every line, and never merge on a green test run alone.

    Platform Knowledge Gaps

    Suggestions are shaped by the code a model has seen, and public mobile code skews old. The assistant reaches for a deprecated API, an outdated permission flow, a threading pattern from before structured concurrency, or a library whose last release predates the current toolchain. All of it compiles. Some will not pass store review. Dependencies add further risk: Apple now requires privacy manifests and signatures for common SDKs, and every dependency carries a license, data collection disclosure, and maintenance risk. A model that suggests a package is not weighing any of that. None of these problems announce themselves; a compiler will not catch them.

    Where AI Genuinely Excels

    Assistants are excellent at boilerplate: data classes, serialization, wiring between layers. They are good at tests, especially edge cases people skip when tired. They excel at mechanical migrations (Java to Kotlin, Objective-C to Swift) and shorten the time to get oriented in an unfamiliar API. Throwaway code becomes almost free, changing what is worth prototyping. The gain is largest where work is mechanical, verifiable, and cheap to be wrong about. It shrinks to nothing where work depends on something the model has no access to: your data model, users, regulatory constraints, or historical decisions.

    What This Changes About Buying Mobile Development

    If the constraint has moved from production to verification, then the thing worth buying has moved too. Useful questions for a prospective partner now sound different: What is the review policy? Who is accountable for a line nobody wrote by hand? How does a new dependency get approved? What runs automatically on every commit, and on how many real devices? Those questions say more about the outcome than headcount or day rate. The mobile development teams that succeed today look less like typing and more like reviewing: fewer hands, more judgment, and a process that assumes code needs to be defended rather than merely delivered.

    The Real Lever: Feedback Loops

    If generation is fast and verification is slow, invest in verification. Continuous integration on every commit, an automated device matrix, static analysis and dependency scanning in the pipeline, builds that reach testers in minutes. The teams that actually got faster over the last two years are the ones that shortened the distance between writing something and finding out whether it works. The assistant is one input into that loop. It was never going to be the loop itself.

  • 5 Best AI-Powered Note-Taking Apps for Research and Knowledge Management in 2026

    5 Best AI-Powered Note-Taking Apps for Research and Knowledge Management in 2026

    Traditional note-taking mainly focused on storing information. AI-powered tools are shifting that experience toward finding, understanding, and using information. Explore AI-powered apps for smarter note-taking, research, and knowledge management in 2026, including Gemini Notebook, Notion AI, Mem, Obsidian, and Capacities.

    Overview

    Gemini Notebook and Notion AI offer powerful research and information-management capabilities. Mem, Obsidian, and Capacities take different approaches to organizing personal knowledge. The best AI note-taking app depends on your workflow, privacy needs, and research habits.

    Gemini Notebook

    Google’s NotebookLM is now called Gemini Notebook. The standalone research tool remains focused on understanding trusted sources. It can work with PDFs, websites, YouTube videos, audio files, and documents. Users can ask questions about their sources and receive cited answers. This makes it useful for research-heavy workflows. Students, analysts, writers, and researchers can keep project materials together. Now, Gemini Notebook has also gained stronger research capabilities. Google added code execution and new output formats. Users can create reports, charts, spreadsheets, and presentations from their sources. For source-based research, few tools are as focused.

    Notion AI

    Notion combines notes, databases, documents, and project management. Its AI features make that workspace more useful. Notion AI can summarize pages and organize information. It can also help users search across their workspace. Its Research Mode goes further for complex questions. It can search Notion content, connected apps, uploaded files, and the web. That makes Notion useful for teams managing large knowledge bases. It also works well for personal project planning. The biggest advantage is flexibility. Users can build their own system instead of following one fixed structure.

    Mem

    Mem takes a different approach to personal knowledge management. It focuses on capturing information without requiring constant organization. Users can save notes, meetings, ideas, and research as they work. Mem then helps connect and retrieve that information later. Its AI can summarize and reorganize existing content. The platform also uses persistent context across notes and projects. That approach suits people who dislike managing folders and complicated tags. Mem is particularly interesting for professionals handling large amounts of information. It can act like a searchable external memory for everyday work.

    Obsidian

    Obsidian remains popular with users who want control over their knowledge base. Notes are stored locally as Markdown files. The platform connects information through links, backlinks, graphs, and properties. It also supports thousands of community plugins. AI capabilities come mainly through plugins rather than one built-in AI system. Users can add tools for summarization, transcription, and AI-assisted writing. That makes Obsidian highly customizable. It can also suit users who care about ownership and flexible workflows. The learning curve is higher than simpler note-taking apps. However, the customization options are difficult to match.

    Capacities

    Capacities takes a structured approach to personal knowledge management. It treats information as connected objects rather than simple documents. Users can organize people, books, projects, ideas, and other information. This structure can make larger knowledge collections easier to navigate. Its AI features help users summarize and work with stored information. The object-based approach is particularly useful for research and long-term learning. Capacities can appeal to users who want more structure than basic notes. It sits between traditional note-taking and a personal knowledge database.

    How to Choose the Right AI Notes App

    The best tool depends on how you work. Researchers may prefer Gemini Notebook for source-heavy projects. Teams may benefit more from Notion’s connected workspace. Mem works well for people who want automatic organization. Obsidian is better suited to users wanting deep customization. Capacities offers a structured approach to connected knowledge. Privacy should also influence the decision. Check how each service stores and processes your information. AI-generated summaries can also contain errors. Important facts should always be checked against sources.

    AI Is Turning Notes Into Working Knowledge

    Modern note-taking apps are becoming more than digital notebooks. They are increasingly becoming systems for finding and using information. The biggest shift is moving from storage to retrieval. Instead of simply saving information, AI can help users understand it later. Research tools are also becoming more capable. Google’s latest Gemini Notebook upgrades show where this category is heading. The right choice ultimately depends on your workflow. A good app should reduce friction rather than create more organizational work. For researchers, students, and professionals, that difference can save hours every week.

    FAQs

    What are the best AI note-taking apps in 2026?

    Several strong options are available in 2026, including Gemini Notebook, Notion AI, Mem, Obsidian, and Capacities. Each takes a different approach. Gemini Notebook focuses heavily on research, while Notion combines notes with workspace management. Obsidian emphasizes customization and local Markdown files.

    What is Gemini Notebook, and how is it different from NotebookLM?

    Gemini Notebook is the new name for Google’s NotebookLM. Google renamed the product in July 2026 while keeping its research-focused purpose. It now connects more closely with Gemini and Google Search. The platform also gained code execution and expanded research capabilities.

    Is Gemini Notebook useful for research?

    Yes, Gemini Notebook is particularly suited to source-based research. Users can organize research materials and ask questions about those sources. Google has also added code execution and new output formats. These capabilities can support deeper analysis, reports, charts, spreadsheets, and presentations.

    Is Notion AI good for knowledge management?

    Notion AI can be useful for both personal and team knowledge management. Its workspace combines documents, databases, projects, and other information. Research Mode can search across connected sources and the web. This makes it useful when information is spread across multiple workplace systems.

    Which AI note-taking app is best for students?

    Students can benefit from several tools depending on their study style. Gemini Notebook is useful for working with course materials and research sources. Notion can organize assignments and notes in one workspace. Obsidian can also work well for students building detailed, connected knowledge systems.

  • How Your Smartphone Apps Track You: A Deep Dive into 2026’s Biggest Data Collectors

    How Your Smartphone Apps Track You: A Deep Dive into 2026’s Biggest Data Collectors

    Your smartphone can reveal significant details about your habits—location, purchases, searches, contacts, identifiers, and usage data can create a detailed digital profile. However, data collection is not automatically the same as harmful tracking. Some information is necessary for app functionality, security, personalization, or analytics. Learn what app tracking means and how to reduce your personal data exposure.

    Meta Apps Lead in Data Collection

    A 2026 Surfshark analysis highlighted Meta apps among the biggest data collectors. The study examined 171 iOS apps from major technology companies. Meta apps disclosed an average of 25 data types. This does not mean every user shares every data type; it shows what developers disclose through Apple’s privacy system. Seven of the study’s most data-hungry apps belonged to Meta. Meta AI reportedly listed 33 of 35 possible data types. Meta Horizon, Messenger, Facebook, and other apps followed closely. The categories can include identifiers, location, product interactions, and browsing information. Some Meta apps also declare data linked directly to users. Meta says information from businesses can help personalize content and AI experiences. Its June 2026 update expanded how this activity can influence personalization. The important point is context: data collection does not automatically mean misuse.

    Google Apps Also Gather Broad Data

    Google apps ranked below Meta on average in the same study. However, Google’s enormous app portfolio makes the picture more complicated. The research examined 44 Google apps. Twenty-nine Google apps appeared among those declaring the broadest data collection. Different Google apps can collect different types of data, including search history, purchases, photos, email addresses, and identifiers. Some collection directly supports useful features like search personalization, account synchronization, and security. Users should examine individual app disclosures rather than relying on a company’s overall reputation.

    Amazon and Other Popular Apps

    Amazon’s apps also collect several categories of user information. The study found an average of 12 data types across Amazon’s apps. Amazon apps commonly declared names, email addresses, device identifiers, and product interactions. Some also declared precise location information. Fitness apps deserve separate attention. Health and fitness applications can access particularly sensitive information. The Surfshark analysis found Fitbit, Strava, and Nike Training Club among data-heavy fitness apps. Fitbit declared 24 data types in that analysis. Fitness data can reveal routines, locations, activities, and other personal details, making permission choices especially important.

    What Does ‘Tracking’ Actually Mean?

    Data collection and tracking are not the same thing. Apple’s privacy system separates these concepts. ‘Data linked to you’ means collected information connects with your identity. ‘Data used to track you’ involves linking information with third-party data. That distinction matters when reading privacy labels. An app can collect information without necessarily using it for cross-service tracking. Apple’s App Store labels show declared data categories and their purposes. Developers provide this information themselves, so privacy labels should be treated as a starting point—not a complete technical audit of an application.

    How to Reduce Your Data Exposure

    You do not need to delete every app to improve privacy. Start by reviewing permissions you rarely use. Location access deserves particular attention. Consider whether an app really needs precise location access. Review microphone, camera, contacts, photos, and Bluetooth permissions too. Disable access when those features are unnecessary. On iPhone, the App Privacy Report can show network activity and accessed domains, providing visibility into connections made by apps and websites. Android users can similarly review permissions through system privacy controls. App-store privacy information can provide another useful reference. Users should also review advertising and personalization settings regularly, as these controls can change as platforms update their privacy systems.

    The Goal Is Smarter Privacy, Not Zero Data

    Modern apps need some information to function properly. Navigation apps need location, while shopping apps need account and purchase details. The bigger issue is understanding what information leaves your device and why companies collect it. The data-hungry app rankings offer a useful warning: popular services can collect far more categories than users expect. That does not make every data-heavy app dangerous, but it does make privacy settings worth reviewing. A few minutes spent checking permissions can significantly improve your digital privacy. The best approach is informed use, not fear of every app.

    FAQs

    What are data-hungry apps?
    Data-hungry apps are applications that report collecting many categories of user information. These categories can include location, identifiers, browsing history, purchases, contacts, and usage data. Collection levels vary between apps, and gathering more data does not automatically mean an app is unsafe or malicious.

    Which apps collect the most personal data in 2026?
    Surfshark’s August 2026 analysis found Meta had the highest average data collection among five major technology companies. Meta apps collected an average of 25 out of 35 possible data types. Meta AI ranked highest individually, declaring 33 data types.

    Does data collection mean an app is tracking me?
    Not necessarily. Data collection and tracking have different meanings. Apple defines tracking as linking app or device data with information from other companies for targeted advertising or measurement. An app can collect information without necessarily using it for cross-service tracking.

    What personal information can mobile apps collect?
    Depending on the app, collected information can include location, email addresses, names, device identifiers, purchase history, browsing history, photos, and usage information. Health and fitness apps can also handle sensitive activity-related information. The exact categories depend on the app and its disclosed practices.

    Are Meta apps the most data-hungry apps?
    According to Surfshark’s 2026 study, Meta had the highest average among the five Big Tech companies analyzed. Its apps averaged 25 of 35 possible data types. The study found that Meta’s seven highest-collection apps occupied the top seven positions.

  • 9 Essential Facts About ISRO’s EOS-05: India’s First Geo-Imaging Satellite

    9 Essential Facts About ISRO’s EOS-05: India’s First Geo-Imaging Satellite

    1. India’s First Geo-Imaging Satellite in Geosynchronous Orbit

    EOS-05 is India’s first dedicated Earth-observation imaging satellite placed in geosynchronous orbit, enabling persistent monitoring of large regions.

    2. Launched Aboard the Powerful GSLV-F17

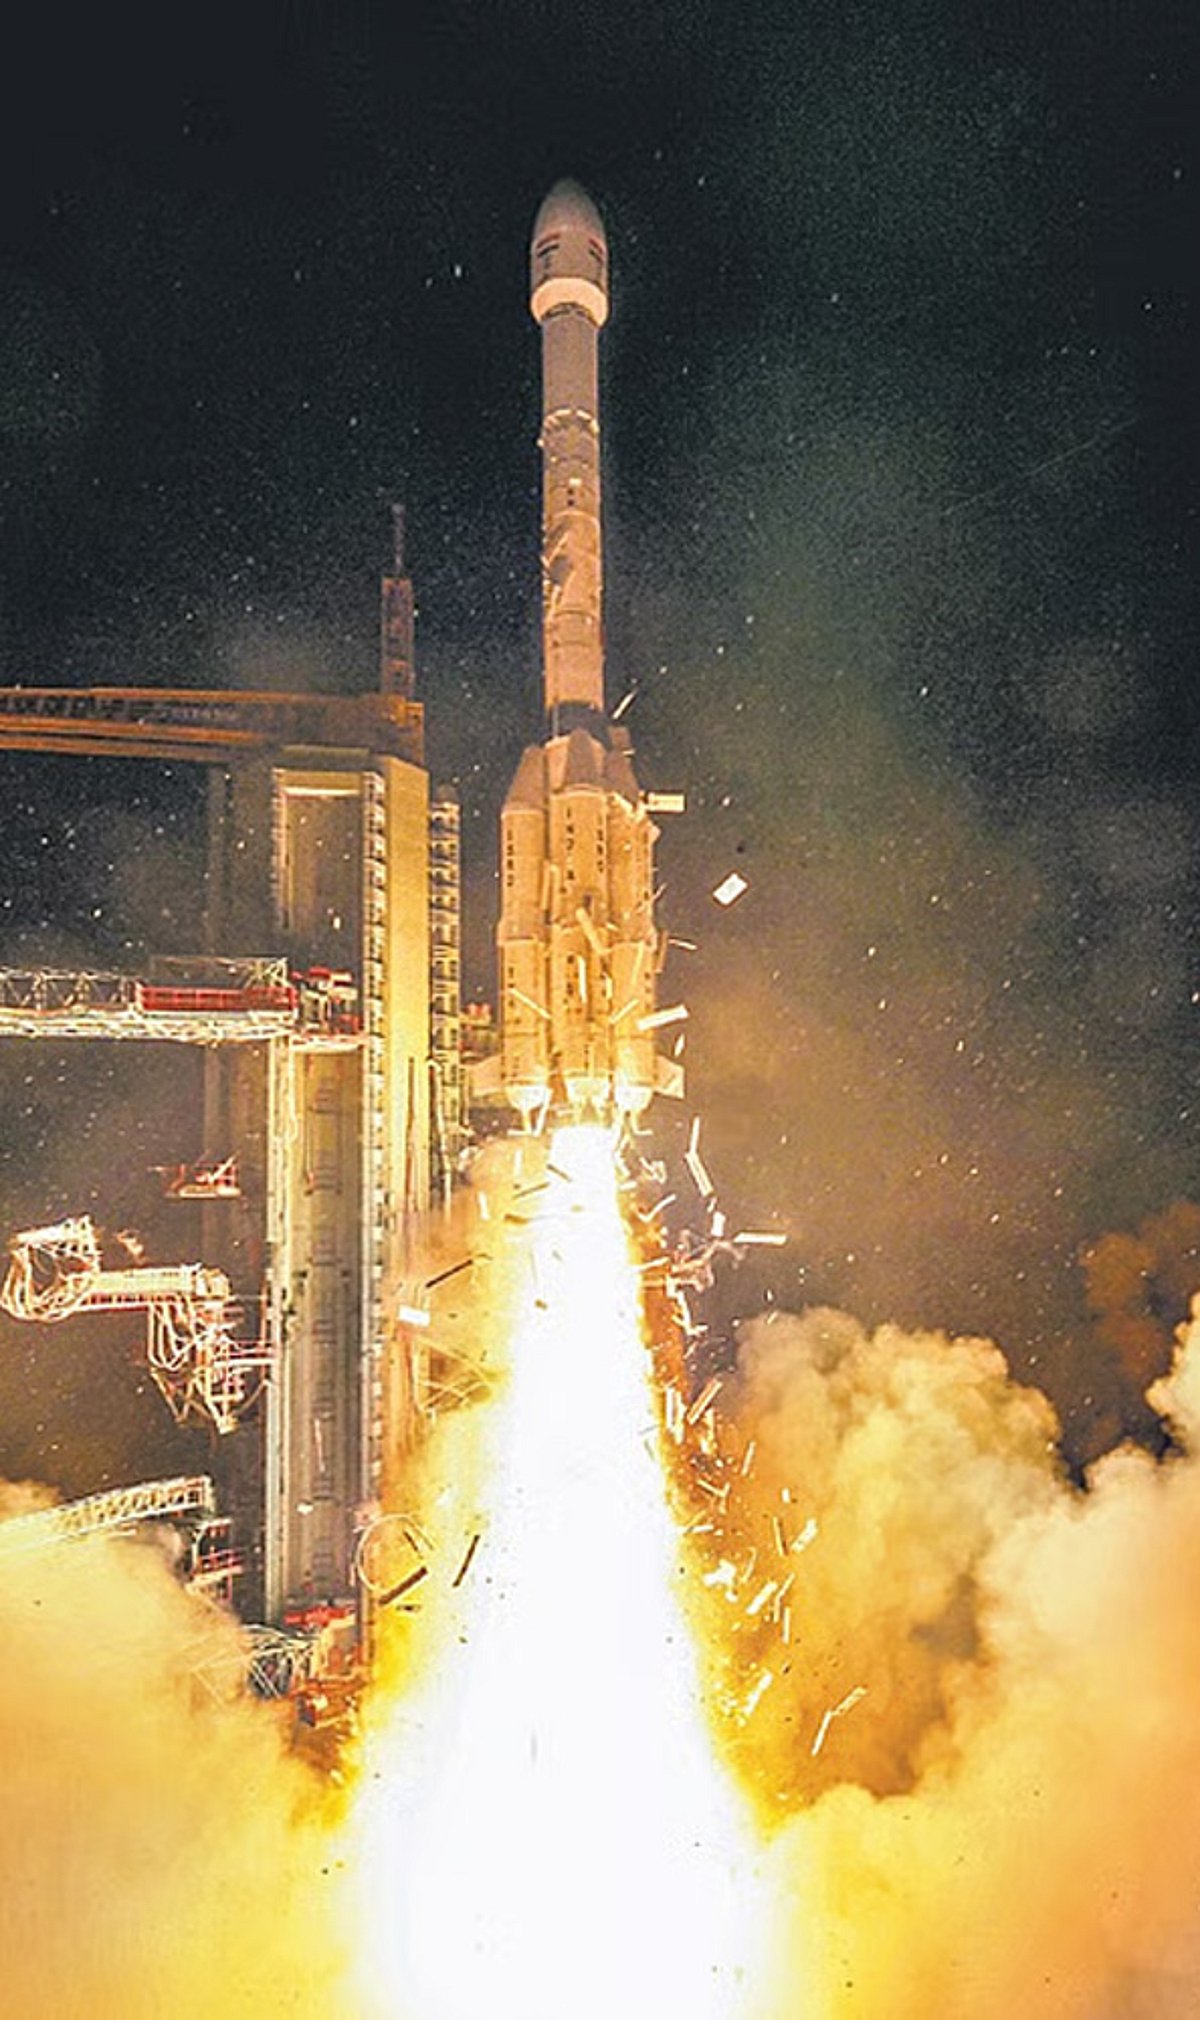
    ISRO launched EOS-05 aboard the GSLV-F17 rocket on September 4, marking the rocket’s heaviest mission and 19th flight.

    3. Operating at Nearly 36,000 Kilometers

    EOS-05 operates in an elliptical geosynchronous orbit, ranging approximately between 34,903 and 35,884 kilometers above Earth.

    4. Continuous Regional Observation

    Its geosynchronous position allows EOS-05 to repeatedly monitor the Indian subcontinent, offering sustained coverage unavailable from conventional low-Earth orbits.

    5. Strengthening Disaster Management

    The satellite is designed to provide frequent imagery that can improve monitoring of natural disasters and enhance response planning.

    6. Supporting Agriculture and Forestry

    EOS-05 can capture imagery of large areas frequently, supporting agricultural assessment, forestry monitoring, and broader environmental management.

    7. Strategic Defense Applications

    Beyond civilian uses, EOS-05 is expected to provide strategic imagery, including supporting the Indian Navy’s information requirements.

    8. Designed for a Ten-Year Mission Life

    With a planned operational lifespan of approximately ten years, EOS-05 provides India with a long-term Earth-observation capability from geosynchronous orbit.

    9. A Milestone for GSLV Reliability

    The successful mission strengthens confidence in the GSLV after several recent launch setbacks and demonstrates India’s high-orbit launch capabilities.

  • Key AI Innovations Transforming Healthcare Today

    Key AI Innovations Transforming Healthcare Today

    Artificial intelligence is rapidly reshaping the healthcare landscape, offering unprecedented speed and accuracy in diagnostics, treatment planning, and administrative workflows. Below are the most impactful AI trends driving change across the industry.

    AI-Powered Diagnostics

    AI systems analyze medical images and clinical data far faster than traditional methods, helping healthcare professionals detect diseases, identify abnormalities, and support accurate diagnoses with greater confidence.

    Generative AI

    Generative AI tools create clinical summaries, draft documentation, organize patient information, and reduce repetitive administrative work, freeing up clinicians to focus on patient care.

    AI Healthcare Agents

    AI agents manage multi-step workflows, coordinate appointments, support follow-ups, and complete routine healthcare tasks with minimal human intervention, improving operational efficiency.

    Personalized Treatment

    By combining patient records, genetic information, and clinical data, AI helps doctors develop more individualized treatment strategies tailored to each patient’s unique profile.

    Predictive Analytics

    Predictive AI identifies potential health risks by analyzing large datasets, enabling earlier interventions and supporting better-informed clinical decisions that can save lives.

    AI Drug Discovery

    Pharmaceutical companies leverage AI to analyze molecules, identify promising compounds, and accelerate the research processes involved in developing new medicines.

    Remote Patient Monitoring

    AI analyzes data from wearable devices and connected medical equipment, helping clinicians detect concerning changes and monitor patients remotely, improving access to care.

    AI-Assisted Surgery

    AI-powered surgical technologies support planning, precision, and decision-making, helping surgeons perform complex procedures while maintaining essential human oversight throughout.

    Responsible AI Governance

    Healthcare organizations increasingly prioritize privacy, bias management, transparency, security, accuracy, and human oversight when implementing artificial intelligence systems, ensuring ethical and safe deployment.

  • IIM Indore 2026 Admission: Full List of Management Programmes and Key CAT Deadlines

    IIM Indore 2026 Admission: Full List of Management Programmes and Key CAT Deadlines

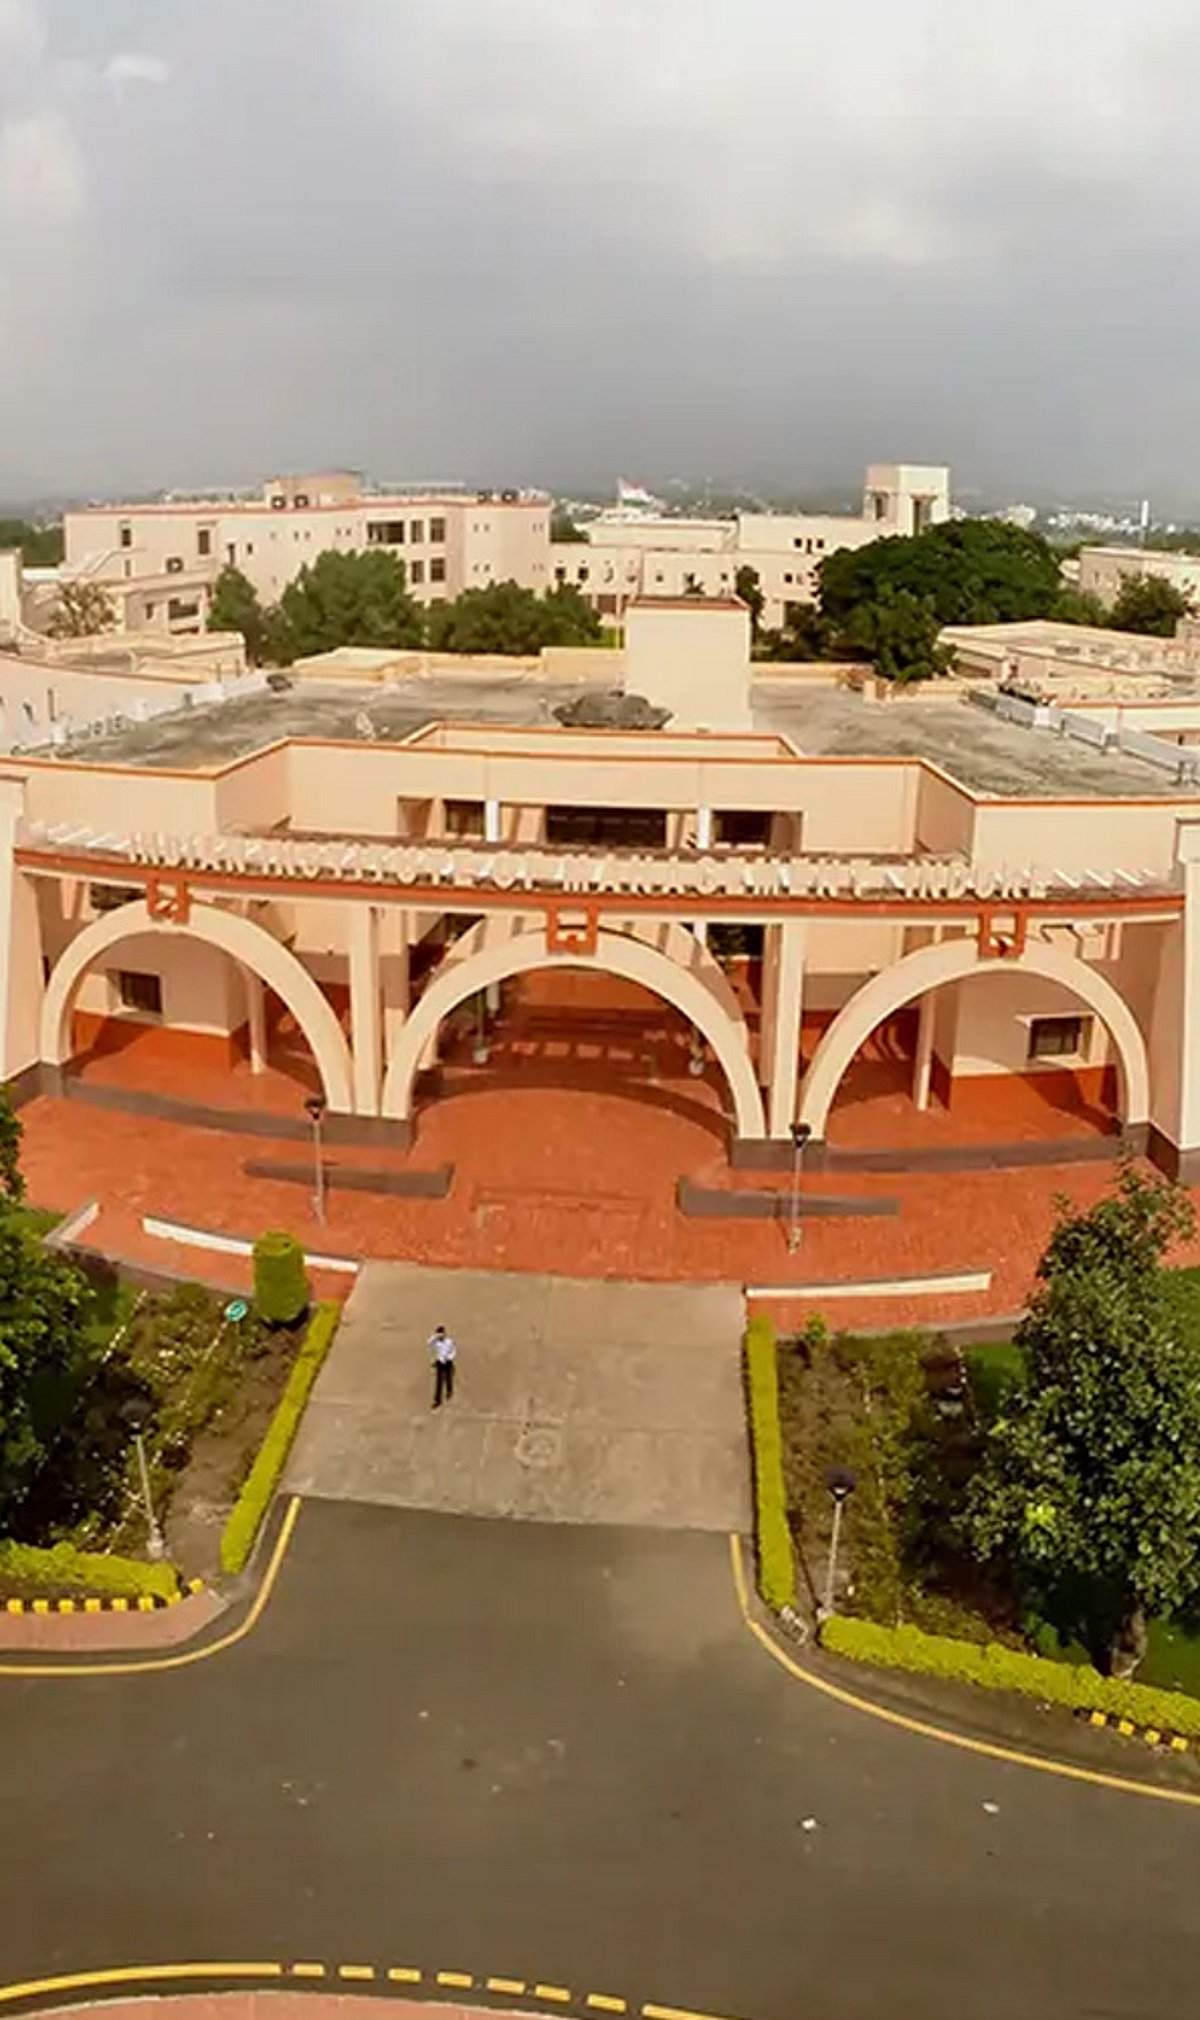
    IIM Indore offers a wide range of management programmes at postgraduate, undergraduate, executive, and doctoral levels, providing students and working professionals with multiple academic pathways in management and related disciplines.

    Flagship MBA: Post Graduate Programme in Management (PGP)

    The two-year, full-time PGP is IIM Indore’s flagship MBA programme. It combines core management subjects with electives in finance, marketing, strategy, and analytics, preparing students for leadership roles.

    PGP in Human Resource Management (PGP-HRM)

    This two-year residential programme focuses on human resource management, equipping students for careers in people management, organisational behaviour, and talent development.

    Integrated Programme in Management (IPM)

    The five-year IPM is designed for students after Class 12. It combines undergraduate study with management education and leads to dual degrees upon successful completion.

    Master of Science in Data Science and Management (MSDSM)

    This programme blends data-focused learning with management education, making it ideal for students interested in analytics and technology-driven decision-making.

    PGPMX for Working Executives

    The PGPMX is a two-year alternate-weekend management programme offered in Mumbai, allowing working executives and entrepreneurs to earn an MBA without leaving their jobs.

    Doctoral Programme in Management (Ph.D.)

    Designed for advanced research, this programme provides intensive training in research methods for scholars aiming to contribute to management knowledge.

    2026 Admission Key Dates and Requirements

    For the 2026 admission cycle, CAT 2026 is scheduled for November 29, with the registration window closing at 5 PM on September 15, 2026. Executive programmes have separate eligibility criteria. For the EPGP 2027-28 cycle, applicants need at least five years of work experience and must submit GMAT, GRE, or CAT scores.

  • Flipkart Big Billion Days 2026: Maximize Savings with Bank Card Discounts and Stackable Offers

    Flipkart Big Billion Days 2026: Maximize Savings with Bank Card Discounts and Stackable Offers

    Flipkart’s Big Billion Days sale offers shoppers the chance to combine bank card discounts with already reduced product prices. The bank discount is applied after the sale price, allowing customers to lower the final amount even further. However, only one bank offer can be used per purchase, along with SuperCoins or an exchange bonus.

    The order in which offers are applied matters. Customers first get the Big Billion Days sale price, then the eligible bank card discount. SuperCoins or an exchange bonus can further reduce the cost if the product qualifies.

    How Flipkart Bank Card Discounts Work

    Bank card discounts during Big Billion Days are typically offered as instant discounts, commonly up to 10%, when customers pay with an eligible card at checkout. The discount applies separately from the promotional sale price. Customers should check the minimum purchase amount and maximum discount limit before paying. For example, a 10% bank discount with a ₹2,000 limit stops at ₹2,000 even if the purchase value is higher.

    Steps to Stack Offers

    1. Add an eligible product to your cart at the sale price.
    2. Check the product page for an available bank offer.
    3. At checkout, select the participating bank card listed for the offer.
    4. The instant discount should apply automatically after selecting the correct card.
    5. Check the final payable amount, as minimum purchase requirements and discount caps can affect savings.
    6. If eligible, add SuperCoins or an exchange bonus after the bank discount.

    Can Two Bank Offers Be Combined?

    Flipkart generally allows only one bank card discount per purchase. If a shopper owns cards from two participating banks, only the card selected at checkout will receive the applicable discount. Bank discounts can still work with SuperCoins, exchange bonuses, and no-cost EMI, since these offers operate separately.

    Instant Discount vs. No-Cost EMI

    An instant bank discount is deducted immediately and suits shoppers paying the full amount upfront. No-cost EMI splits the payment into installments without added interest but typically doesn’t offer the same instant discount. For shoppers seeking the lowest final price, the instant bank discount generally offers better value.

    SuperCoins and exchange bonuses can also be combined with bank discounts, making a combination of sale price, bank offer, and exchange bonus one of the most effective ways to reduce the final cost during Big Billion Days.

  • Sitharaman Calls AI a ‘Double-Edged Sword’ for Fintech, Urges Human Oversight and Smart Regulation

    Sitharaman Calls AI a ‘Double-Edged Sword’ for Fintech, Urges Human Oversight and Smart Regulation

    Finance Minister Nirmala Sitharaman warned about the dual nature of artificial intelligence at the Global Fintech Fest 2026 in Mumbai, describing AI as a ‘double-edged sword’ that can both enhance and endanger financial systems. Speaking to a gathering of industry leaders, she highlighted the potential for AI to improve fraud detection and operational efficiency, but cautioned that the same technology could amplify cyber threats, systemic risks, and even influence public opinion and elections.

    Sitharaman emphasized that while AI can assist judgment, ultimate responsibility must remain with humans and institutions. She called for stronger oversight as financial firms increasingly rely on automated systems for fraud monitoring, risk assessment, and customer services. The minister argued that faster technology should not come at the cost of resilience in critical financial infrastructure.

    She advocated a ‘soft-touch regulation’ approach, developed in consultation with the Reserve Bank of India, aimed at fostering innovation without creating unnecessary barriers. Sitharaman welcomed the RBI’s recognition of the Unified FinTech Forum as a self-regulatory organization under its SRO-FT framework, noting that this reflects the evolving regulatory needs of India’s expanding fintech ecosystem.

    Higher-risk AI applications should face deeper scrutiny before deployment and throughout their lifecycle, she said, urging regulators, company boards, and senior executives to understand how these systems influence financial outcomes. The minister also proposed a federated industry platform to help Indian technology companies navigate cross-border rules on data, taxation, cybersecurity, and financial regulation.

    Sitharaman also called on the RBI to advance its wholesale and retail Central Bank Digital Currency pilots. Her broader message placed resilience alongside efficiency as a central requirement for India’s AI strategy, signaling that fintech companies will face greater expectations around accountability, cybersecurity, and responsible AI deployment.

    The Global Fintech Fest drew around 8,000 organizations, with technology-related entities accounting for 43% of participants and fintech firms representing another 20%. Sitharaman noted that young Indians are already building companies and shaping future economic growth, underscoring the importance of developing technology systems that can withstand failures and misuse.

  • Consumer Court Orders EPFO to Pay 6% Interest on Delayed Provident Fund Claim of Rs. 14.06 Lakh

    Consumer Court Orders EPFO to Pay 6% Interest on Delayed Provident Fund Claim of Rs. 14.06 Lakh

    The Mumbai Suburban District Consumer Disputes Redressal Commission has directed the Employees’ Provident Fund Organization (EPFO) to pay 6% annual interest on a delayed provident fund claim of Rs. 14.06 lakh. The ruling came after the commission found that EPFO had delayed the payment by 35 days, from November 9 to December 13, 2016.

    Background of the Case

    The case involves a retired employee of Fleet Maritime Services (India) Pvt Ltd who filed a PF claim for Rs. 14,06,272 on October 19, 2016. The claimant stated that he submitted a complete application, but EPFO later argued that a required joint declaration was missing from the original submission.

    According to EPFO, the documents were returned to the claimant on November 7, and a complete set was received only on December 2. The organization then settled the claim on December 14, maintaining that the payment was made within the prescribed 20-day period.

    EPFO’s Defense Rejected

    The consumer commission rejected EPFO’s explanation, noting that the organization failed to produce any written communication showing that the claimant was informed about the missing document. Without such evidence, the commission concluded that EPFO had not adequately established that the original claim was incomplete.

    The commission held that the claim should have been processed within the applicable 20-day period and that the failure to do so constituted a deficiency in service.

    Commission Orders 6% Interest

    The commission ordered EPFO to pay interest at 6% per annum on the claim amount for the 35-day delay. It is important to note that this does not mean the retiree receives 6% of the entire PF amount as a full-year payment; rather, the annual interest rate applies only to the specific period of delay identified by the commission.

    EPFO has been given 45 days to comply with the order.

    What This Means for PF Claimants

    The ruling underscores the importance of clear documentation when filing provident fund claims. Claimants are advised to keep copies of all submitted documents, acknowledgments, and any communications with EPFO. This can be crucial if a dispute arises over when a claim was received or whether additional paperwork was requested.

    The case also highlights that simply citing a missing document may not be enough to justify a delay if the organization cannot prove that the claimant was properly informed about the deficiency.

    Also Read: How to Change Your Bank Account Details in EPFO After Job Switch