Category: AI Strategy

  • How AI Agents Are Transitioning from Assistants to Autonomous Digital Workers

    How AI Agents Are Transitioning from Assistants to Autonomous Digital Workers

    Artificial intelligence has entered a new stage. In the past, most AI systems answered questions, wrote text, or helped users complete small tasks. Today, AI plays a much larger role. Modern AI agents can understand a goal, create a plan, use different software tools, check results, fix mistakes, and complete entire jobs with minimal human support. This evolution moves AI from a simple assistant to a digital worker that can handle complex tasks from start to finish.

    Key Takeaways

    • Reasoning models help AI solve complex problems through careful step-by-step decisions.
    • Autonomous workflows allow AI agents to complete entire business tasks with limited human support.
    • Memory, software tools, and multi-agent teamwork make AI more capable, reliable, and useful for enterprises.

    Reasoning Models Bring Better Decisions

    The latest AI models focus more on reasoning than on larger size. Earlier models mostly predicted the next word in a sentence. New reasoning models spend more time before they respond. They study the problem, divide it into smaller parts, test different solutions, and verify the final answer. This method helps them solve difficult problems with greater accuracy. Such models perform well in software development, mathematics, scientific research, legal work, and business planning because they can think through each step before acting.

    AI Agents Work Until the Goal Is Complete

    A normal language model usually gives one answer and stops. An AI agent works very differently. It first understands the goal, then creates a plan, selects the right tools, completes one task after another, checks the outcome, and makes changes if something goes wrong. The process continues until the final objective is achieved. This ability makes AI agents useful for long and complicated work rather than just simple conversations.

    Autonomous Workflows Change Business Operations

    Businesses now look beyond basic automation. Older automation systems followed fixed rules and worked well only when every step stayed the same. Autonomous workflows offer much more flexibility. AI agents can study new situations, collect information from different sources, use business software, connect with online services, create reports, and verify results before delivering the final output. This approach reduces manual effort and allows companies to complete many business processes with greater speed and accuracy.

    Teams of AI Agents Solve Bigger Problems

    Many organizations now use several AI agents instead of one large system. Each agent has a special role. One agent may collect information, another may write code, another may study data, while another may check quality or prepare documents. A manager agent coordinates all of them and combines their work into one final result. This teamwork enables faster task completion and better quality because every agent focuses on a specific responsibility.

    Software Tools Become Part of AI Work

    Modern AI agents do much more than produce text. They can use web browsers, databases, spreadsheets, cloud platforms, programming tools, email services, calendars, and customer management systems. Instead of only giving advice, they can complete real work inside these applications. This ability has become one of the biggest changes in AI because it allows agents to operate software just as a human employee would.

    Memory Makes AI More Useful

    Memory has turned into a significant aspect of modern AI agents. Short-term memory retains information about the present task, while long-term memory holds information about user preferences, company knowledge, and experiences from previous jobs. Some agents also maintain records of past mistakes and accomplishments. Thus, AI agents can leverage stored knowledge and experience to enhance future work rather than starting from scratch each time.

    New Enterprise Systems Support AI Agents

    Large companies now build special platforms to manage AI agents. These systems control task planning, memory, security, software access, and performance checks. They also monitor every action so that organizations can maintain safety and follow business rules. Human approval remains an important part of many business processes, especially when AI handles financial, legal, or sensitive information.

    Software Development Leads AI Adoption

    Software development has become one of the fastest areas for AI agent use. Modern agents can write code, test software, identify errors, review updates, prepare technical documents, and assist with system maintenance. Developers now spend less time on repetitive work and more time on design, innovation, and difficult technical problems. This change has improved productivity across many software teams.

    Why This Matters

    There are still some prominent challenges facing AI agents today. They can generate false information, misinterpret commands, and take wrong actions in tough situations. Safety and security remain key areas of concern, as AI agents may work on sensitive business systems or handle personal information. Companies must develop solid procedures for protecting data, monitoring AI agent behavior, validating outcomes regularly, and documenting every action taken.

    The Future of Autonomous AI

    The future of AI agents will focus less on conversation and more on completed work. Businesses already expect AI to research information, create reports, manage projects, analyze data, communicate with customers, and support daily operations. Better reasoning, stronger memory, smarter planning, and closer cooperation between multiple AI agents will make these systems even more capable. Over the next few years, AI will become an essential part of many industries, not because it can answer questions, but because it can complete valuable work from beginning to end with greater reliability and efficiency.

    Frequently Asked Questions

    1. What is an AI agent?
    An AI agent is a system that can plan, use tools, make decisions, and complete tasks instead of only answering questions.

    2. How are reasoning models different from traditional AI models?
    Reasoning models spend more time analyzing problems before they respond, which improves accuracy for complex tasks.

    3. What are autonomous workflows?
    Autonomous workflows allow AI to manage complete business processes by planning, executing tasks, checking results, and making corrections when needed.

    4. Why is memory important for AI agents?
    Memory helps AI remember user preferences, previous tasks, and useful knowledge, which leads to more personalized and efficient results.

    5. Which industries benefit the most from AI agents?
    Software development, healthcare, finance, customer service, legal research, marketing, sales, human resources, and business operations are among the industries that benefit the most.

  • Anthropic Unveils Claude Sonnet 5 and Cloud Tasks, Paving the Way for an AI Super App

    Anthropic Unveils Claude Sonnet 5 and Cloud Tasks, Paving the Way for an AI Super App

    Anthropic has taken a significant step toward building an all-in-one AI platform with the launch of Claude Sonnet 5 and the integration of cloud-based task execution. The update merges chat, coding, and task management into a single interface, allowing users to run lengthy projects in the cloud even after closing their laptops.

    Available now for Claude Max subscribers on desktop, web, and mobile, the new features eliminate the need to keep devices powered on for long-running tasks. This shift gives users greater flexibility and simplifies complex workflows, marking a move beyond the traditional chatbot model.

    Claude Evolves into a Full Work Platform

    Anthropic is transforming Claude from a simple conversational agent into a comprehensive work environment. Instead of switching between separate apps for coding, research, writing, and planning, users can now handle multiple tasks within Claude. The company believes this unified approach will benefit both developers and everyday users.

    Earlier this year, Anthropic hinted at the vision of remote AI work that doesn’t require constant device activity. The latest update realizes that vision, bringing Claude closer to becoming a true super app. The platform now includes Claude Code, Claude Science, and Claude Design, along with integrations with popular tools like Slack, Chrome, and Microsoft 365.

    New AI Model and Enterprise Focus

    Central to the update is Claude Sonnet 5, which Anthropic describes as its most powerful model yet for coding and professional tasks. It supports smarter AI agents that can tackle larger projects with less manual intervention.

    Anthropic is also deepening its enterprise push, partnering with companies like TCS and engaging with government organizations. The company aims to deliver safe, accurate AI for industries such as healthcare, finance, cybersecurity, and public services.

    The competitive landscape remains intense: OpenAI continues to expand ChatGPT, while Microsoft broadens Copilot across its ecosystem. Anthropic differentiates itself by emphasizing safety and business-friendly features rather than consumer-focused gimmicks.

    Room for Improvement

    Despite the advances, Claude still has gaps. Cowork conversations do not fully sync between desktop and mobile devices yet. Anthropic has promised better cross-device integration in future updates, which will smooth the user experience.

    This release underscores a broader industry trend: AI companies are moving away from simple chatbots and toward complete work platforms. A single AI service may soon handle coding, research, writing, planning, and collaboration, helping businesses reduce tool sprawl and save time.

  • China Considers New Restrictions on Overseas Access to Advanced AI Models

    China Considers New Restrictions on Overseas Access to Advanced AI Models

    Beijing Reviews Frontier AI as Strategic Technology

    China is evaluating potential new controls that would restrict overseas access to its most advanced artificial intelligence models, according to sources familiar with recent government-led discussions. The talks signal that Beijing now views frontier AI systems as strategic assets rather than mere commercial software, raising the stakes for global developers and businesses that rely on Chinese AI technology.

    Over the past month, officials from China’s Ministry of Commerce and the state planning agency met with major technology firms including Alibaba, ByteDance, and Z.ai to discuss possible limits on the use of top AI models outside the country. The proposals cover both closed-source systems and open-weight models, which allow users to download and modify parts of the technology. Sources told Reuters that the plans remain under review and that no final decision has been made.

    National Security Concerns Drive the Initiative

    The Ministry of Commerce led the meetings, with one proposal suggesting that leaks or theft of proprietary AI technology could be treated as an offense under China’s national security law. Officials also discussed tightening controls on who can fund domestic AI startups, adding another layer of oversight around sensitive technology and data.

    Chinese authorities are reportedly worried about advanced US AI systems, such as Anthropic’s Mythos model, and their potential use in finding software vulnerabilities. This mirrors US concerns that foreign actors could misuse frontier AI tools for military or intelligence purposes. The talks reflect a growing mutual anxiety between the two countries over AI security.

    Scope of Restrictions Remains Unclear

    Alibaba’s Qwen, ByteDance’s Doubao, and Z.ai’s GLM-5.2 are among the Chinese models that have gained global attention for their lower costs and strong performance. However, officials indicated that any new rules may apply only to future models, leaving existing systems unaffected. The scope and timeline remain uncertain, creating ambiguity for companies that integrate Chinese AI tools into software, research, automation, and customer service.

    Legal experts in China have already discussed a tiered approach for open-source AI. Under one proposal, basic tools would require simple filing, more powerful systems would face security reviews, and the most sensitive frontier models could be limited to domestic use only.

    Global Developers Face Potential Disruption

    Chinese AI models, particularly DeepSeek’s R1, have become a low-cost alternative for developers worldwide. If Beijing proceeds with restrictions, foreign companies may lose access to affordable AI options, potentially shifting to US or European alternatives or seeking domestic solutions. Costs could rise for businesses that have come to rely on Chinese AI systems.

    For now, formal rules have not been announced. Sources said it is not clear when, or even whether, the curbs will take effect. The global AI community continues to watch closely as China’s advanced models become central to national technology policy.

  • SpaceXAI Unveils Grok 4.5 to Challenge Rivals in the AI Race

    SpaceXAI Unveils Grok 4.5 to Challenge Rivals in the AI Race

    The AI race has become even more intense. SpaceXAI will launch Grok 4.5, its latest language model, on July 9, 2026. The new model arrives before the expected release of next-generation AI systems from several rivals, making the timing hard to ignore.

    Elon Musk has been clear about his goal. He wants Grok to stand alongside the best AI models available today. With every new release, the company is trying to improve reasoning, speed, and the overall user experience. Grok 4.5 is another step in that plan.

    Grok 4.5 Brings New Upgrades to the AI Race

    Earlier this year, Elon Musk launched Grok 4.3 and stated that the company is preparing a more advanced model that will build on improved reasoning, stronger coding support, and better responses across tasks. In an official post, Musk has announced that the upcoming LLM is built on XAI’s new V9 foundation model, which features 1.5 trillion parameters. The model is also expected to handle longer conversations more naturally and provide more accurate answers.

    SpaceXAI says Grok is designed to be useful to both everyday users and developers. The company continues to expand its AI tools while keeping Grok closely connected to X. This gives users quick access to AI without leaving the platform.

    The launch also shows that Musk wants to compete directly with the biggest names in AI. OpenAI, Google, and Anthropic have all released stronger models over the past year. Grok 4.5 is SpaceXAI’s answer to that growing competition.

    Why Launch Grok 4.5 Now?

    The timing may be just as important as the technology. Several AI companies are expected to introduce major updates in the coming months. By releasing Grok 4.5 now, SpaceXAI keeps itself in the spotlight before its rivals make their next moves. Even Musk has mentioned that Grok 4.5 is ‘Opus-Class,’ which is a direct reference to its rival Claude’s general language model, Claude Opus.

    The company also wants developers and businesses to use Grok before newer models from competitors arrive. Companies often go for early releases to get feedback and improve performance. This helps them strengthen their user base before the next stage of the AI race begins.

    Competition in AI is moving faster than ever. Every launch now becomes part of a larger battle to attract users, developers, and businesses.

    What Grok 4.5 Could Mean for X Users?

    The most significant transformation isn’t the launch of the model; instead, it’s the implementation. If it works properly, tasks like searching, content discovery, and writing will be much more convenient on X.

    With the arrival of an advanced tool like Grok, the platform may grow larger than a mere social network. It can be a powerful solution to many tasks such as information discovery, post creation, and communication with users.

  • Multi-Agent Systems: Enhancing AI Speed, Accuracy, and Scalability

    Multi-Agent Systems: Enhancing AI Speed, Accuracy, and Scalability

    Artificial intelligence has transformed how we solve problems, create content, analyze data, and automate workflows. As AI evolves, tasks grow increasingly complex. A single AI agent can handle many duties, but it often struggles when a job demands diverse skills, careful planning, or simultaneous steps. This challenge has given rise to multi-agent systems—a setup where multiple AI agents collaborate, each with a specific role, to achieve superior performance.

    How Multi-Agent Systems Work

    A multi-agent system breaks a large task into smaller, manageable pieces. An orchestrator agent receives the initial request and decides the workflow. Then, specialized agents take over based on their strengths: a planner outlines the strategy, a researcher gathers data, a tool agent interacts with software or databases, a reviewer checks for errors, and a final agent compiles the response. This division of labor makes the entire process more organized and reliable.

    Better Results Through Specialization

    Specialization is a key advantage. Instead of burdening one agent with everything, each agent focuses on a single objective. For example, a coding agent writes code while another inspects it for bugs. A research agent finds facts while a verifier confirms their accuracy. This clear separation improves quality because every agent performs tasks aligned with its design.

    Faster Performance with Parallel Execution

    Multi-agent systems excel at speed by running tasks in parallel. While a single agent processes sequentially, multiple agents can simultaneously gather data, analyze it, and produce reports. This concurrency dramatically reduces completion times, especially for large-scale operations in software development, research, and enterprise projects.

    Higher Accuracy Through Verification

    Accuracy is a top priority. Multi-agent systems add a verification layer: one agent reviews another’s work. For instance, an agent drafts a report, then a reviewer checks facts, calculations, and references. Errors are flagged before finalization, cutting down on misinformation and boosting trust in the output.

    Research Backing Multi-Agent Systems

    Recent Google research examined 180 different multi-agent designs. The study found these systems perform best when tasks split into independent parts. Researchers also developed prediction models to identify the optimal agent structure for various jobs. Fields like software development, customer support, enterprise automation, and data analysis benefit greatly from this approach.

    More Agents ≠ Better Performance

    Adding more agents doesn’t automatically improve results. Some complex multi-agent systems can be ten times more expensive than a strong single-agent solution while yielding weaker outcomes. Poor coordination leads to delays, redundant work, and excessive communication. Experts emphasize careful design over sheer quantity—a small, well-organized team of specialized agents often outperforms a large, uncoordinated group.

    Why Real-Time Information Matters

    Modern businesses operate in fast-changing environments. Multi-agent systems perform better when all agents access the latest data. Event-driven architectures allow agents to share current information, reducing conflicting decisions and enabling quicker responses to changes while maintaining consistency.

    Enterprise Improvements

    Companies now build multi-agent systems for business operations. Recent enterprise frameworks achieve up to 4.5 times higher throughput without major resource increases, using smaller models for specific tasks. This efficiency lets organizations process larger workloads cost-effectively.

    Common Business Applications

    • Software Development: Agents handle planning, coding, testing, debugging, and documentation, improving quality and speed.
    • Research: One agent searches, another summarizes, a third verifies references, and a fourth prepares the final report, reducing errors.
    • Customer Support: Specialized agents classify requests, search knowledge bases, verify policies, draft responses, and review replies, boosting consistency and satisfaction.
    • Business Automation: Multi-agent systems manage financial analysis, supply chain operations, compliance checks, and scheduling.

    Current Challenges

    Despite benefits, multi-agent systems introduce infrastructure costs and complexity. Communication between agents requires careful management to avoid duplication or conflicting decisions. Debugging becomes harder due to multiple interactions. Companies need robust monitoring, clear governance, and reliable coordination to maintain high performance.

    Final Thoughts

    Multi-agent systems represent a significant advancement in AI. Instead of relying on a single agent, they leverage the strengths of many to handle complex tasks more efficiently. They improve speed, accuracy, scalability, and reliability across diverse fields. However, success depends on thoughtful design—not just the number of agents. A well-structured team of specialized agents consistently outperforms general-purpose or poorly designed systems.

    Frequently Asked Questions

    1. What is a multi-agent system? A group of AI agents collaborating, each handling a specific task toward a common goal.
    2. Why are they better than a single AI agent? They boost speed, accuracy, and efficiency by dividing complex work among specialized agents.
    3. Where are they commonly used? In software development, research, customer service, business automation, financial analysis, and supply chain management.
    4. Do more agents always improve performance? No. Well-designed systems outperform large, poorly coordinated groups.
    5. What is the biggest advantage? The ability to solve complex problems faster and more accurately through collaboration between specialized agents.
  • Why Enterprise AI Projects Stall: A Data Foundation Problem

    Why Enterprise AI Projects Stall: A Data Foundation Problem

    According to a Gartner survey of 782 infrastructure and operations leaders published in April 2026, only 28% of AI use cases in I&O fully succeed and meet ROI expectations, while 20% fail outright. Thirty-eight percent of leaders who faced setbacks cited poor data quality or limited data availability as a direct cause. The conclusion increasingly shared across the industry is that the root of most AI failures lies not in the quality of the model itself, but in the underlying level of data and infrastructure.

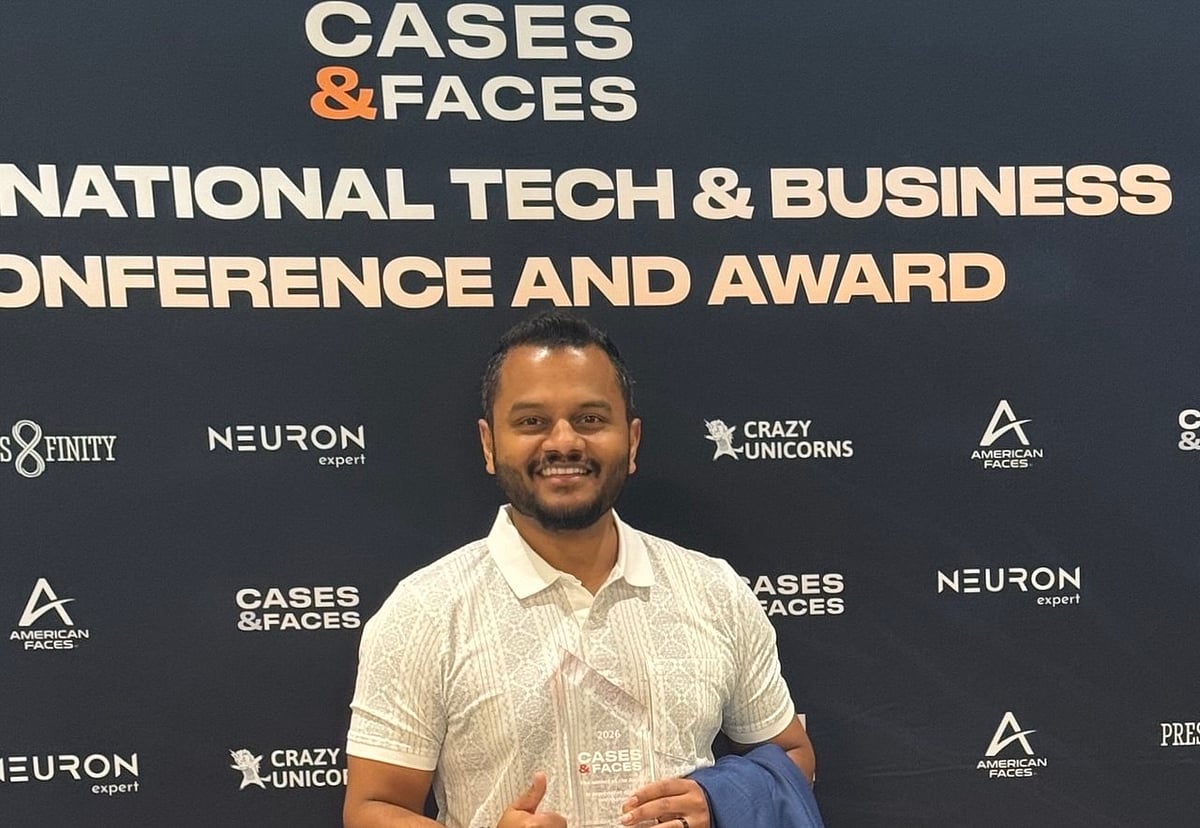
    Few practitioners understand this from the inside as clearly as Sushrutha Sreevathsa, a Service Reliability Engineer at Yahoo, where he supports platforms serving more than 200 million daily users. A member of the D2A2 Council — an exclusive thought leadership group in Digital, Data, Analytics, and AI — and a contributing author to the AWS Marketplace publication Build Strong Data Foundations for Agentic Analytics and Intelligent Agents, Sreevathsa recently received the Cases & Faces International Business Award for Achievement in Product Innovation in the Data Analytics & Big Data category. We spoke with him about why enterprise AI keeps stalling, and what it actually takes to build the foundations that make it work.

    Adoption vs. Impact

    “Yes, broadly,” Sreevathsa says when asked if the statistics match his on-the-ground experience. “What I see across the industry matches what the research is pointing to: the adoption numbers are real, but the value is often not following. Part of that is because a lot of organisations are measuring the wrong thing. They track how many teams are using an AI tool, or how many dashboards have been built, and conclude that adoption is working. But adoption does not necessarily mean impact. The more honest question is: are decisions actually changing because of this data? And in many cases, the answer is no — because the underlying data is not in a state where people trust it enough to act on it.”

    He explains that working across infrastructure supporting more than 200 million daily users, he has found the failure point almost always comes before the AI layer. “Teams are generating enormous volumes of operational data, but when different parts of the organisation use different definitions, baselines, and reporting views, the AI ends up amplifying disagreement rather than resolving it — a sophisticated tool sitting on top of an unresolved problem.”

    Where AI Projects Actually Break

    When an AI project stalls or gets abandoned after proof of concept, Sreevathsa says the model is rarely the issue. “What is broken is usually one of three things: the data is not clean or consistent enough to be trusted, there is no clear ownership of what the data is supposed to mean, or the business question the AI is supposed to answer was never properly defined in the first place.”

    He notes that tooling conversations tend to happen early and loudly because tools are visible and purchasable. “The data foundation conversation is a lot less exciting to have in a board presentation — but it is the one that actually determines whether the project delivers measurable results.”

    The Connected Intelligence Operating Model

    Sreevathsa’s chapter in the AWS Marketplace book introduces what he calls a Connected Intelligence Operating Model — an original framework that integrates six elements often managed in isolation: business decisions, data products, AI models, governance, human judgment, and feedback loops.

    “Connected intelligence means that AI-enabled decision-making requires more than aggregating data from different sources. It requires building a coherent, governed layer where technical, operational, and business signals are all speaking the same consistent language. When a leadership team looks at a dashboard, every number should have a clear, agreed-upon meaning, and every person in the room should be working from the same version of reality.”

    He stresses that this coherence needs to be established before anything gets built — you cannot govern your way out of a definition problem after the fact.

    Solving the Data Trust Problem at Yahoo

    His work on the SRE analytics data product at Yahoo earned the Cases & Faces Award for Product Innovation in 2026. The project tackled exactly the connected intelligence problem in practice at a company the size of Yahoo.

    “When every team has its own reporting view, and those views have been in place for a while, people become attached to their version of the numbers. There is usually a legitimate reason why a particular team measures something the way they do, but when the goal is to give leadership a single, reliable picture of what is happening across the organisation, those differences become a problem.”

    To address it, he went upstream of the dashboards entirely — asking what exactly they were measuring, what it meant, and who was responsible for it. Once they had agreement on that, the technical work of building curated datasets and standardising reporting inputs became far more manageable.

    Making Definitions Explicit

    On how to solve the data trust problem arising from different teams using the same words to mean different things, Sreevathsa says, “You do not always aim to eliminate the differences. More often, you make them explicit and agree on what the canonical version is for a specific purpose.”

    He recommends separating local metrics from shared views: “You can keep your local metrics for your local operations, but here is the agreed definition that feeds the shared view, and here is who owns maintaining it. That ownership piece is critical. Definitions drift when nobody is accountable for keeping them stable. Once you assign clear ownership and document it, you have something that can be maintained and audited rather than argued over every quarter.”

    Real-World Impact: RevMon and Revenue Protection

    Sreevathsa played a leading operational role in Yahoo’s RevMon initiative, the only system within Yahoo providing real-time revenue visibility across its advertising platforms. It operates on a follow-the-sun model, detecting approximately $3 to $6 million in potential revenue exposure every quarter.

    “A significant part of it was the trust,” he explains. “The monitoring infrastructure was important — without real-time visibility into what was happening across Yahoo’s ad delivery systems, you simply could not catch revenue-impacting incidents fast enough. But what prevented losses was not the monitoring alone. It was the ability to act immediately when something surfaced — and that became possible because everyone was looking at the same data and could act on it without spending time on additional confirmation.”

    Anomaly as Operational Risk

    Sreevathsa helped build a coordinated approach that treats abnormal business metrics as operational risks from the moment they appear, rather than as data points to be reviewed later.

    “The core shift was in how the organization treated a business metric anomaly when it surfaced. In most environments, an unusual number in a revenue dashboard triggers a reporting workflow where it gets noted, logged, and may or may not prompt action depending on how serious it appears. What we built treats that same anomaly as the start of an operational response: there is a defined triage process, a clear escalation path, and accountability distributed across the teams who need to act.”

    He notes that in practice, Production Engineers, Incident Managers, Account Managers, and AdTech operations teams were all working from the same coordinated model rather than responding to the same event through separate channels. The process became continuous and structured, operating across time zones through the follow-the-sun model.

    What Separates Successful AI Organizations

    Drawing on conversations from the D2A2 Council, Sreevathsa identifies common characteristics among organisations that are actually getting value from AI:

    • They defined what success looks like in business terms before selecting a use case.
    • They treated data as a product — with owners, SLAs, and governance — rather than as an output of their systems.
    • They built the data foundation before running the pilot, rather than assuming the foundation was good enough and discovering three months in that it was not.

    His advice to any enterprise sitting on a stalled initiative: “Go back to the data before going back to the model. Not to run another audit, but to ask one specific question: do the people who are supposed to act on this AI output actually trust the data it is drawing from? If the answer is anything other than an unambiguous yes, that is where the work needs to happen. It is slower and less visible than running another proof of concept — but it is the only path to something that holds up in production.”

  • Top 5 AI Agent Performance Issues and Engineering Solutions for Production Systems

    Top 5 AI Agent Performance Issues and Engineering Solutions for Production Systems

    Many AI agent failures stem from system design rather than limitations of the underlying model. Runaway loops, context drift, and poor tool orchestration can reduce accuracy while increasing costs. Practical engineering safeguards help prevent these issues and create more dependable production systems.

    Overview

    • Most agent failures trace back to five root causes: runaway loops, tool misuse, memory rot, weak grounding, and uncoordinated multi-agent handoffs.
    • Each failure carries an operational signal worth tracking, such as tool-call fidelity, handoff latency, or hallucination rate, before damage compounds.
    • Fixing agents is a systems engineering problem rather than a prompting problem, and continuous evaluation has become standard practice across mature 2026 production stacks.

    The biggest risk to an AI agent is not a weak model. It is a system that looks reliable until real users, live data, and unpredictable situations expose its flaws. Most production failures come from engineering choices, not model capability. How an agent plans work, selects tools, manages context, and coordinates with other agents determines whether it performs reliably or fails under production pressure. Performance goes beyond accuracy. It includes latency, cost, task completion, and reliability. This is why engineering teams now rely on observability, catching regressions before they ever disrupt production.

    Runaway Loops and Unbounded Execution

    Repeated tool calls, where an AI agent uses external tools such as APIs or databases to complete a task, rarely signal a weak model. They usually point to missing execution constraints in the orchestration layer. Without a hard stop condition, an agent has no built-in reason to quit even after progress has clearly stalled, and every extra loop burns tokens and time.

    The fix starts with runtime limits: a maximum number of steps, a cap on tool calls, and a token budget set per task. Pairing these limits with a simple progress check that compares the latest output with the previous step helps detect stalled runs early. If no new information is produced, the run aborts instead of continuing. Deduplicating repeated tool arguments closes the most common variant of this failure, where an agent quietly retries the same query with identical inputs.

    Tool Misuse and Weak Orchestration

    Agents given too many tools tend to pick the wrong one, pass malformed arguments, or invoke a tool call that does not match anything registered in the system. Many engineering teams track tool-call fidelity, the ratio of attempted calls to clean, error-free results, as an operational signal. A sustained decline typically indicates a mismatch between the agent’s understanding of a tool and the tool’s actual schema.

    The exact threshold worth flagging varies by team and workload. Restriction and validation solve most of this: give the agent the smallest tool set the task actually needs, validate every argument against a predefined schema before execution, and route simple requests away from the agent entirely when a direct API call would do the job faster.

    Memory Rot and Context Drift

    Long-running agents do not simply forget details. Their working memory can actively corrupt itself over time. Engineers sometimes call this memory rot: small errors in an agent’s own reasoning trace accumulate across a long task, and each step continues to look locally coherent even as the overall state drifts from what is actually true. Multi-agent chains make this worse, since one agent can pass its already-degraded context downstream, and the next agent builds on that flawed foundation with full confidence.

    Treating context as a working surface rather than a permanent record fixes this at the root: summarize aggressively once a thread grows long, keep a single source of truth for any fact that matters, and separate durable memory from disposable conversation history.

    Weak Grounding and Unmeasured Hallucinations

    An ungrounded agent answers with confidence even when it is wrong, and this often surfaces only after a bad output has already triggered a downstream action. Grounding reduces this risk through retrieval from live or verified data, citations for high-risk claims, and human review before high-impact actions are executed.

    Mature engineering teams run golden-set evaluations after prompt, workflow, or model updates and monitor hallucination rates through automated pipelines instead of assuming quality holds steady between releases. Expanding an adversarial test set over time catches regressions before users ever notice them.

    Multi-Agent Coordination and Prompt Injection

    Multi-agent workflows raise a new challenge: coordination now rivals reasoning in importance. One common failure is the infinite handoff loop, where Agent A passes a task to B, B forwards it to C, and C sends it back to A, with no single agent owning the outcome. Every transfer raises the risk of context degradation and slows completion.

    Clear task ownership and well-defined handoff rules prevent these failures. Multi-agent systems also face prompt injection risks, where malicious instructions hidden in documents, emails, or tool outputs can alter an agent’s behavior. Marking external content untrusted by default, separating read and write permissions, and requiring approval for sensitive actions help contain these attacks.

    Tracking the right operational metrics helps teams verify that these engineering improvements continue to work as production workloads evolve.

    Final Thoughts

    An AI agent succeeds or fails less on model capability and more on system design. Production-ready agents carry clear guardrails, measurable performance, and well-defined ownership from the start. Engineering discipline, backed by steady monitoring and evaluation, is what lets these agents run reliably at scale.

    Frequently Asked Questions

    1. What are the most common AI agent performance problems?

    The most common AI agent performance problems include runaway execution loops, tool misuse, context drift, weak grounding, prompt injection, and poor coordination between multiple agents. These issues can reduce reliability, increase costs, and affect task completion in production environments.

    2. Why do AI agents fail in production even when they work in testing?

    AI agents often perform well in controlled environments but encounter unpredictable inputs, live data, and complex workflows in production. Weak orchestration, missing guardrails, poor context management, and inadequate monitoring are common causes of production failures.

    3. How can engineering teams improve AI agent reliability?

    Engineering teams can improve reliability by setting runtime limits, validating tool calls, maintaining accurate context, grounding outputs in trusted data, assigning clear task ownership, and continuously monitoring performance through operational metrics and evaluations.

    4. Which metrics should be tracked to evaluate AI agent performance?

    Important AI agent evaluation metrics include task completion rate, tool-call fidelity, latency, token consumption, hallucination rate, handoff latency, and security-related indicators. Monitoring these metrics helps identify performance regressions before they affect production systems.

    5. Why is observability important for AI agents?

    Observability provides visibility into how AI agents execute tasks by tracking execution traces, tool usage, latency, token consumption, and system behavior. It helps engineering teams detect failures early, troubleshoot issues faster, and maintain reliable performance as workloads evolve.

  • Revolutionizing Visa Applications: How AI Streamlines the Process for Indian Travelers

    Revolutionizing Visa Applications: How AI Streamlines the Process for Indian Travelers

    The process of traveling abroad—whether for leisure, business, education, or visiting relatives—has never been simpler for Indian tourists. While booking flights and accommodations can take just minutes, the visa application process remains a time-consuming and stressful endeavor. Collecting required documents, understanding each country’s specific requirements, filling out forms correctly, and tracking application status can be daunting.

    Fortunately, artificial intelligence is radically changing that. By automating processes, validating documents, and providing step-by-step assistance, AI makes the visa application process faster and less intimidating.

    Challenges Faced by Indian Travelers

    Every nation has its own visa requirements and application procedures. A small mistake—such as uploading the wrong document or filling in a field incorrectly—can lead to delays or requests for additional information. Common challenges include:

    • Navigating country-specific document requirements
    • Organizing financial and supporting documents
    • Filling out lengthy application forms accurately
    • Tracking the status of submitted applications
    • Dealing with multiple document formats (PDF, scans, photos)

    For those juggling work, studies, or family obligations, these tasks can become overwhelming.

    The Role of AI in Streamlining Visa Applications

    Artificial intelligence simplifies the visa application process by reducing manual tasks. Advanced AI guides users through every step, from initial document preparation to final submission. Current systems can analyze uploaded documents, identify gaps, and flag potential errors before submission. AI also provides personalized checklists based on the traveler’s destination and visa type.

    Automated Document Validation

    Document preparation is often the most time-consuming part of visa applications. Travelers must ensure that passports, financial records, identification papers, photographs, and letters of invitation are correct and complete. AI-powered validation tools automatically check documents for errors, missing pages, or inconsistencies. Instead of receiving a rejection notice after submission, travelers get real-time feedback and can fix issues immediately.

    Enhancing Transparency Throughout the Process

    One of the biggest frustrations for applicants is the lack of clarity after submitting documents. Travelers often wonder if more information is needed and when a decision will be made. AI-based platforms solve this by offering centralized dashboards that track status, send notifications, and provide updates on any changes. This transparency helps travelers—especially business travelers and families with fixed trip dates—plan more effectively.

    Visarun AI: An Example in Action

    Visarun AI is a prime example of how artificial intelligence can make visa applications easier for travelers. This AI-enabled B2C platform simplifies the entire process, from preparing the application and organizing documents to tracking status and receiving updates. Rather than leaving travelers to navigate complex requirements alone, Visarun AI uses automation to guide them step by step.

    Advantages Beyond Faster Processing

    In addition to reduced processing time, AI offers several other benefits:

    • Less paperwork and manual effort
    • Greater accuracy in documentation
    • Tailored assistance based on the traveler’s profile
    • Shorter preparation time
    • Increased transparency about application progress
    • Reduced stress during the entire visa process

    These benefits are especially valuable for first-time international travelers.

    The Future of AI in Travel

    Artificial intelligence is expected to play an even larger role in international travel in the coming years. Future advancements may include multilingual assistance, better document recognition, predictive process improvements, and personalized travel recommendations. AI does not replace immigration officials but works alongside existing systems to produce better-prepared applications that are easier to evaluate. As governments worldwide continue digitizing their processes, AI travel assistants will become as common as booking flights, arranging accommodations, and purchasing insurance.

    Conclusion

    For Indian citizens, securing a visa has traditionally involved extensive paperwork, diligence, and uncertainty. Artificial intelligence is revolutionizing this process by automating checks, simplifying document preparation, and increasing transparency. With tools like Visarun AI, travelers can now streamline the visa application process, avoid common mistakes, and minimize stress.

  • Norway’s New School Rules Restrict AI Use for Kids to Foster Critical Thinking

    Norway’s New School Rules Restrict AI Use for Kids to Foster Critical Thinking

    Norway has introduced a comprehensive set of guidelines restricting the unrestricted use of artificial intelligence in classrooms, aiming to encourage independent thinking, creativity, and stronger foundational learning among students. The new rules apply to all age groups but impose stricter limitations on younger students, while older learners receive guided access under structured educational supervision.

    Teacher Oversight and Academic Integrity

    Educators remain responsible for supervising AI usage, ensuring technology supports education without replacing critical learning or student participation. The rules also discourage students from submitting AI-generated work without proper disclosure, protecting fairness and maintaining educational standards nationwide.

    Critical Thinking and Digital Literacy

    Schools are now required to teach students how to evaluate AI-generated content critically, rather than accepting automated responses without verification. Digital literacy education covers responsible AI use, ethical considerations, online safety, and understanding algorithmic limitations.

    Privacy and Responsible Innovation

    Guidelines emphasize safeguarding student data and preventing unauthorized sharing of personal information with AI platforms and online services. Norway promotes a balanced approach to AI adoption, encouraging technological advancement while protecting educational quality, fairness, and meaningful student engagement.

    The updated framework may influence other countries considering similar regulations for integrating artificial intelligence into school education responsibly.

  • OpenAI Expands GPT-5.6 Access After U.S. Government Safety Review

    OpenAI Expands GPT-5.6 Access After U.S. Government Safety Review

    OpenAI has begun rolling out its GPT-5.6 models to a wider audience after completing a review by the U.S. government. The company had delayed the full release while officials assessed the models for potential risks, and with the review now concluded, the rollout is moving forward.

    The new lineup includes three variants: GPT-5.6 Sol, Terra, and Luna. Each model is optimized for different use cases:

    • Sol is the most capable model, designed for high-end performance.
    • Terra balances cost and performance for everyday tasks.
    • Luna is built for speed and lower-cost operations.

    OpenAI first shared these models with a small group of users before expanding access. With the government review complete, businesses, developers, and ChatGPT users can expect broader availability over time.

    Improved Performance and Safety

    The company claims GPT-5.6 models offer better performance in writing, coding, question answering, and handling long-context tasks. They also include stronger safety checks compared to earlier versions. The brief delay highlights growing government scrutiny of advanced AI systems, as officials seek to understand risks before wide-scale deployment.

    Why OpenAI Waited

    OpenAI first announced GPT-5.6 in late June but limited access while the U.S. government conducted its review, reportedly focusing on security risks. After receiving approval, the company proceeded with the broader rollout. OpenAI has expressed hope that such reviews will not become a standard requirement for every new AI release, but the process underscores the increasing importance of safety assessments in AI development.

    Conclusion

    The wider release of GPT-5.6 Sol, Terra, and Luna marks a significant step for OpenAI. It brings advanced AI capabilities to more users while demonstrating how AI development is evolving—companies are now accountable for safety and security before public release. As the rollout continues, observers will watch how the models perform and whether similar reviews become routine for future AI launches.